
Compare / Claude Sonnet 5.5 vs Mistral Large 4
Claude Sonnet 5.5 vs Mistral Large 4
Which is cheaper, which is more capable, and which does better at each kind of work, from 72 results on 5 sources that measured both models.
Claude Sonnet 5.5 or Mistral Large 4? The short answer
- Mistral Large 4 is cheaper: $1.03 against $4.00 per million tokens, 3.9 times less.
- Claude Sonnet 5.5 scores higher on the Artificial Analysis Intelligence Index: 56.0 against 38.4.
- Claude Sonnet 5.5 writes faster: 137 tokens a second against 106.
- On our business benchmarks, Claude Sonnet 5.5 ranks higher for product listings, decks from an analysis, marketing planning, agents and tool use and reasoning and knowledge.
- On our business benchmarks, Mistral Large 4 ranks higher for speed under pressure.
At a glance
| Claude Sonnet 5.5 | Mistral Large 4 | |
|---|---|---|
| Price per million tokens | $2.00 in · $10.00 out | $0.68 in · $2.09 out |
| Blended (3 in : 1 out) | $4.00 | $1.03 |
| Cheapest host, blended | $4.00 (Google) | – |
| Intelligence Index | 56.0 | 38.4 |
| Spring Prompt overall | 64 | 31 |
| Output speed, tokens a second | 137 | 106 |
| Context window | 1,000,000 tokens | 524,288 tokens |
| Weights | Closed | Closed |
| Developer based in | the US | France |
Prices are the developer's list price where we have read it, otherwise the typical host on OpenRouter; see every model's price. Intelligence and speed from Artificial Analysis.
Which is better for what
Each model's rank among models available today, for each kind of work, from our own benchmarks and licensed sources. The better rank is in green.
| Use case | Claude Sonnet 5.5 | Mistral Large 4 |
|---|---|---|
| Product listingsTurning a sparse product feed and photos into listings that can go live | 10 of 19 | 17 of 19 |
| Decks from an analysisTurning a finished analysis into a deck you could present as it is | 4 of 18 | 18 of 18 |
| Marketing planningPlanning a year of ad spend without overspending | 4 of 18 | 10 of 18 |
| Agents and tool useMulti-step tasks with tools: support desks, coding agents, function calls | 1 of 161 | 20 of 161 |
| Professional workReal tasks from banking, consulting and law, business documents and freelance projects | 1 of 51 | not measured |
| Reasoning and knowledgeHard questions across science, maths and general knowledge | 2 of 195 | 43 of 195 |
| Sticking to the factsSummarising without inventing things, and factual answers | 61 of 153 | not measured |
| Speed under pressureGood decisions against a real clock (fast chess) | 21 of 21 | 13 of 21 |
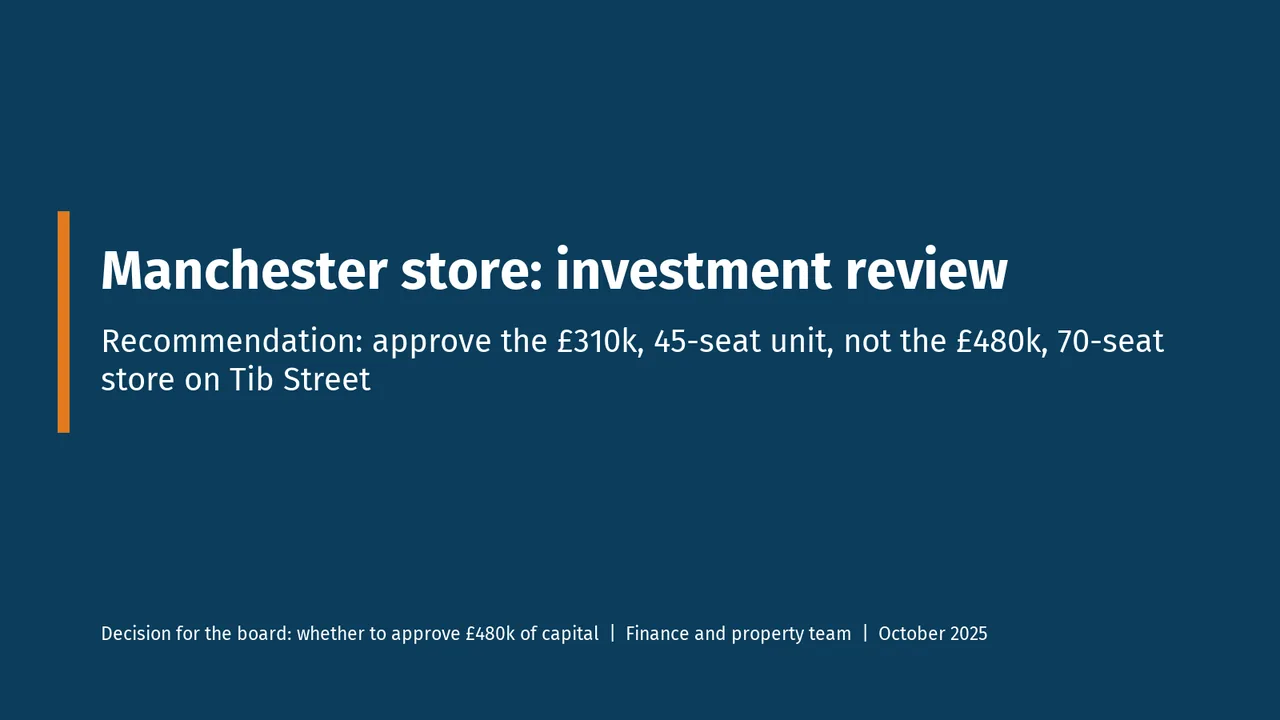
Their slides, side by side
The same brief for both: Manchester store investment review for Hearthside Coffee, an invented company. First slide of each deck from DeckBench.

From our research
Every shared result
| Benchmark | Metric | Claude Sonnet 5.5 | Mistral Large 4 |
|---|---|---|---|
| BulletBenchmeasured by us | Cost per gameUS dollars | $0.12 | $0.0082 |
| BulletBenchmeasured by us | Games lost on time% of games | 37.5% | 0.0% |
| BulletBenchmeasured by us | Invalid moves% of moves | 0.0% | 0.6% |
| BulletBenchmeasured by us | Ladder Eloladder Elo | 557 | 555 |
| BulletBenchmeasured by us | Median move timemilliseconds | 8.1 s | 0.8 s |
| BulletBenchmeasured by us | Cost per gameUS dollars | $0.0080 | $0.0117 |
| BulletBenchmeasured by us | Games lost on time% of games | 91.7% | 58.3% |
| BulletBenchmeasured by us | Invalid moves% of moves | 0.0% | 1.8% |
| BulletBenchmeasured by us | Ladder Eloladder Elo | 33 | 249 |
| BulletBenchmeasured by us | Median move timemilliseconds | 2.1 s | 0.8 s |
| CatalogBenchmeasured by us | Channel rules broken% of products | 0.6% | 1.2% |
| CatalogBenchmeasured by us | Claims to check% of products | 0.6% | 3.3% |
| CatalogBenchmeasured by us | Content quality% of checks | 97.3% | 95.9% |
| CatalogBenchmeasured by us | Failed outputs% of products | 0.0% | 0.0% |
| CatalogBenchmeasured by us | Missing UK information% of products | 0.0% | 0.0% |
| CatalogBenchmeasured by us | Not findable% of products | 0.6% | 3.0% |
| CatalogBenchmeasured by us | Publish-ready listings% of products | 27.4% | 10.7% |
| CatalogBenchmeasured by us | Reliably publish-ready% of products | 10.7% | 1.8% |
| CatalogBenchmeasured by us | Unsupported claimsclaims per product | 1.71 | 3.69 |
| CatalogBenchmeasured by us | Unsupported claims% of products | 59.5% | 80.4% |
| CatalogBenchmeasured by us | Wrong attributes% of products | 20.8% | 17.3% |
| CatalogBenchmeasured by us | Wrong category or variant% of products | 3.0% | 1.8% |
| CatalogBenchmeasured by us | Channel compliance% of products | 99.4% | 100.0% |
| CatalogBenchmeasured by us | Channel rules broken% of products | 1.2% | 3.0% |
| CatalogBenchmeasured by us | Claims to check% of products | 0.0% | 0.7% |
| CatalogBenchmeasured by us | Conflicts caught% of conflicts | 100.0% | 100.0% |
| CatalogBenchmeasured by us | Content quality% of checks | 96.5% | 96.5% |
| CatalogBenchmeasured by us | Cost per productUS dollars | $0.0172 | $0.0033 |
| CatalogBenchmeasured by us | Decision accuracy% of decisions | 95.7% | 93.1% |
| CatalogBenchmeasured by us | Failed outputs% of products | 0.0% | 0.0% |
| CatalogBenchmeasured by us | Field accuracy% of missing fields | 91.5% | 94.4% |
| CatalogBenchmeasured by us | Invented values% of filled values | 0.8% | 3.5% |
| CatalogBenchmeasured by us | Missing UK information% of products | 0.0% | 0.0% |
| CatalogBenchmeasured by us | Not findable% of products | 1.2% | 4.2% |
| CatalogBenchmeasured by us | Publish-ready listings% of products | 46.4% | 39.9% |
| CatalogBenchmeasured by us | Reliably publish-ready% of products | 32.1% | 10.7% |
| CatalogBenchmeasured by us | Unsupported claims% of products | 39.3% | 33.3% |
| CatalogBenchmeasured by us | Unsupported claimsclaims per product | 1.08 | 0.91 |
| CatalogBenchmeasured by us | Wrong attributes% of products | 19.1% | 19.6% |
| CatalogBenchmeasured by us | Wrong category or variant% of products | 3.0% | 1.2% |
| DeckBenchmeasured by us | Accurate decks% of tasks | 66.7% | 0.0% |
| DeckBenchmeasured by us | Caveat dropped% of tasks | 16.7% | 16.7% |
| DeckBenchmeasured by us | Clean layout% of tasks | 100.0% | 33.3% |
| DeckBenchmeasured by us | Cost per deckUS dollars | $0.15 | $0.0148 |
| DeckBenchmeasured by us | Deck ratingrating | 1,356 | 515 |
| DeckBenchmeasured by us | Design quality% of the maximum | 78.5% | 30.5% |
| DeckBenchmeasured by us | Draft figure quoted% of tasks | 0.0% | 16.7% |
| DeckBenchmeasured by us | Findings missing% of tasks | 0.0% | 0.0% |
| DeckBenchmeasured by us | Head-to-head win rate% of comparisons | 79.6% | 10.7% |
| DeckBenchmeasured by us | Layout defects% of tasks | 0.0% | 66.7% |
| DeckBenchmeasured by us | Misleading metric used% of tasks | 0.0% | 0.0% |
| DeckBenchmeasured by us | Presentable decks% of tasks | 50.0% | 0.0% |
| DeckBenchmeasured by us | Recommendation late or wrong% of tasks | 16.7% | 83.3% |
| DeckBenchmeasured by us | Slides needing work% of tasks | 33.3% | 100.0% |
| DeckBenchmeasured by us | Unsupported claims% of tasks | 0.0% | 50.0% |
| DeckBenchmeasured by us | Unsupported numbers% of tasks | 0.0% | 33.3% |
| ROASBenchmeasured by us | Audience scorescore out of 100 | 61.8 | 55.8 |
| ROASBenchmeasured by us | Business scorescore out of 100 | 57.2 | 34.2 |
| ROASBenchmeasured by us | Consistency scorescore out of 100 | 28.5 | 16.7 |
| ROASBenchmeasured by us | Contribution profitsimulated US dollars | $571,203 | $533,401 |
| ROASBenchmeasured by us | Cost of a runUS dollars | $0.42 | $0.0657 |
| ROASBenchmeasured by us | Months over budgetmonths of 12 | 0 | 0 |
| ROASBenchmeasured by us | Overall scorescore out of 100 | 52.0 | 37.0 |
| ROASBenchmeasured by us | Planning scorescore out of 100 | 55.1 | 55.0 |
| ROASBenchmeasured by us | Return on ad spendprofit per $1 spent | $0.70 | $0.45 |
| Artificial Analysisreported | Artificial Analysis Intelligence Indexindex score | 56.0 | 38.4 |
| Artificial Analysisreported | Humanity's Last Exam% of questions | 55.0% | 35.0% |
| Artificial Analysisreported | Long-context reasoning (AA-LCR)% of questions | 82.7% | 81.3% |
| Artificial Analysisreported | Output speedtokens per second | 137 | 106 |
| Artificial Analysisreported | SciCode% of problems | 61.0% | 54.2% |
| Artificial Analysisreported | Terminal-Bench 4.0% of tasks | 63.6% | 26.8% |
| Artificial Analysisreported | Time to first answer tokenseconds | 0.67 | 19.8 |
Bold green marks the better value on that metric. Where a source reports ranges that overlap, the difference may not be meaningful; see the benchmark page for ranges.
Quick answers
Is Claude Sonnet 5.5 better than Mistral Large 4?
It depends on the task. Among models available today, on our benchmarks and licensed sources, Claude Sonnet 5.5 ranks higher for product listings, decks from an analysis, marketing planning, agents and tool use and reasoning and knowledge; Mistral Large 4 ranks higher for speed under pressure.
Which is cheaper, Claude Sonnet 5.5 or Mistral Large 4?
Mistral Large 4 costs $1.03 per million tokens (three input to one output), against $4.00 for Claude Sonnet 5.5.
Which is faster, Claude Sonnet 5.5 or Mistral Large 4?
Claude Sonnet 5.5 writes about 137 tokens a second on its usual API, against 106 for Mistral Large 4 (Artificial Analysis).
Run Claude Sonnet 5.5 and Mistral Large 4 on your own prompt
Benchmarks aren't your data. Try both side by side in the playground, with the cost of every answer.