Benchmarks / BulletBench

Measured by Spring Prompt

BulletBench

When every second of thinking time comes off the clock, which models are fast enough to still make good decisions?

Last updated 13 Nov 2026

Results dated
1 Oct 2026 to 13 Nov 2026
Results
70 configurations of 58 models
Unit
ladder Elo
Licence
Spring Prompt original
Sample
8 to 12 games per configuration

BulletBench in brief

What it measures. BulletBench is a Spring Prompt benchmark. When thinking time comes off the clock, which models are quick enough to still make good decisions? It scores: Decision quality under real time pressure; Response latency at the provider's default settings; Which reasoning settings are fast enough to use.

Latest results. , 70 configurations ranked.

Top 3 on Bullet 60s (ladder Elo, higher is better):

  1. Gemini 3.8 Flash (low reasoning) (Google): 1,068
  2. GPT-6.1 Sol Ultrafast (low reasoning) (OpenAI): 928
  3. Gemini 3.1 Flash-Lite (minimal reasoning) (Google): 912

The first 5 are too close to tell apart, so read the order among them as a tie.

How to cite. Spring Prompt, "BulletBench", results dated 13 November 2026. https://springprompt.com/benchmarks/bulletbench

Ladder Elo: Drex v1.5

Top 15 of 70 results · ladder Elo, higher is better · lines show the 95% range · ≈ cannot be told apart from the leader. Choose a model to highlight it.Clear highlight

  1. 1≈ Gemini 3.8 Flash (low reasoning)Google 1,068
  2. 2≈ GPT-6.1 Sol Ultrafast (low reasoning)OpenAI 928
  3. 3≈ Gemini 3.1 Flash-Lite (minimal reasoning)Google 912
  4. 4≈ Gemini 3.5 Flash (minimal reasoning)Google 810
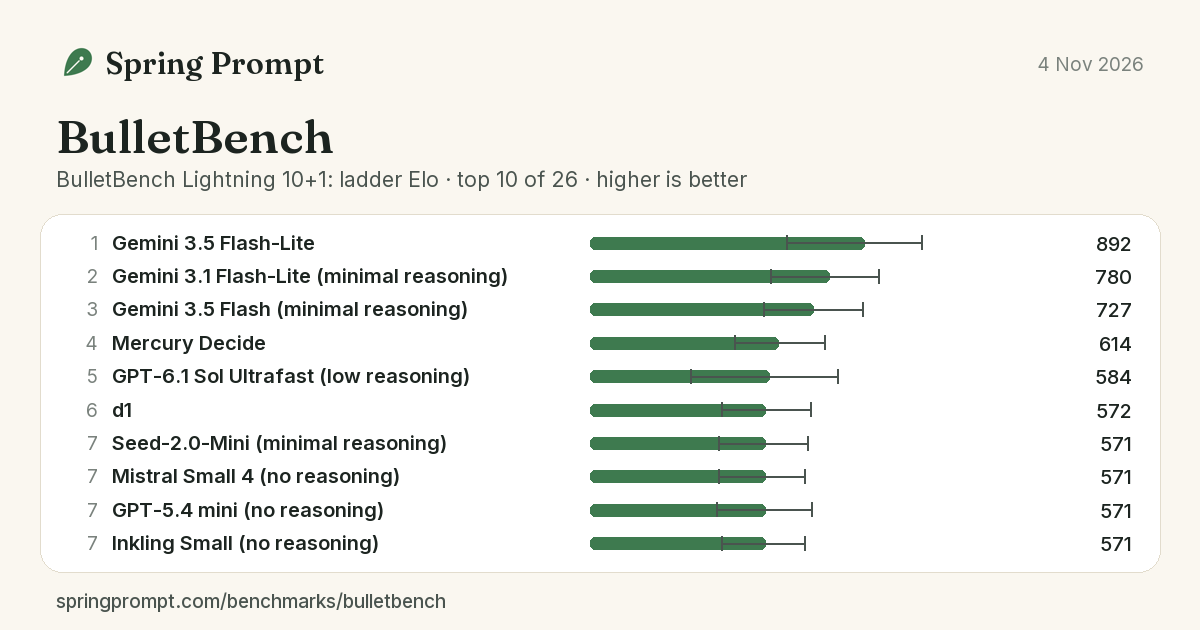
  5. 5≈ Gemini 3.5 Flash-LiteGoogle 780
  6. 6 Gemini 3.6 Flash (minimal reasoning)Google 628
  7. 7 d1.1Decision modelLiquid AI 614
  8. 7 ReflexDecision modelMorph 614
  9. 9 d1Decision modelLiquid AI 584
  10. 10 Mercury DecideDecision modelInception 572
  11. 10 d1 UltraDecision modelLiquid AI 572
  12. 10 Mistral Medium 3.5 (no reasoning)Mistral AI 572
  13. 10 Drex MaxDecision modelNace AI 572
  14. 10 Jev 1.13Decision modelTypeSafe 572
  15. 15 Elephant 1Decision modelBaseten 571
  16. 41 Drex v1.5Decision modelNace AI 449

Lightning: strength against thinking time

Each configuration's median time per move at 10 seconds plus 1 a move. Right of the line, a model thinks longer than the increment it earns and the clock drains.

Named: the six bestOther models (hover for names)

-200300800 0.1 s1 s10 s Median time per move (log scale) Ladder Elo 1 s increment Gemini 3.5 Flash-Lite Gemini 3.1 Flash-Lite (minimal reasoning) Gemini Decision 1 Gemini 3.5 Flash (minimal reasoning) Clef Omni Reflex

Full results

BulletBench Bullet 60s: ladder Elo, ladder Elo, higher is better
#ModelBullet 60s · 95% range
ladder Elo, higher is better
Lightning 10+1
ladder Elo
Blitz 3+2
ladder Elo
Move time
seconds
Lost on time
% of games
Cost per game
US dollars
Slowest 10% of moves
seconds, 90th percentile
Games
at this clock
1≈ Gemini 3.8 Flash (low reasoning)Google
1,068
888–1,241
197–1.8 s50.0%$0.0165 2.2 s12
2≈ GPT-6.1 Sol Ultrafast (low reasoning)OpenAI
928
676–1,184
584–1.4 s25.0%$0.34 ––
3≈ Gemini 3.1 Flash-Lite (minimal reasoning)Google
912
697–1,087
780–0.8 s8.3%$0.0068 ––
4≈ Gemini 3.5 Flash (minimal reasoning)Google
810
582–1,006
727–1.2 s25.0%$0.0289 1.4 s12
5≈ Gemini 3.5 Flash-LiteGoogle
780
586–956
8927070.9 s0.0%$0.0058 ––
6 Gemini 3.6 Flash (minimal reasoning)Google
628
429–849
33–1.6 s41.7%$0.0113 1.9 s12
7 d1.1Decision modelLiquid AI
614
470–766
572–0.6 s0.0%$0.0003 0.8 s12
7 ReflexDecision modelMorph
614
470–746
616–0.6 s0.0%$0.0006 0.7 s12
9 d1Decision modelLiquid AI
584
435–749
572–0.6 s0.0%$0.0007 0.7 s12
10 Mercury DecideDecision modelInception
572
428–717
614–0.4 s0.0%$0 0.5 s12
10 d1 UltraDecision modelLiquid AI
572
412–727
529–0.6 s0.0%$0.0003 1.0 s12
10 Mistral Medium 3.5 (no reasoning)Mistral AI
572
428–708
529–0.5 s0.0%$0.0354 0.7 s12
10 Drex MaxDecision modelNace AI
572
412–727
409–1.2 s33.3%$0.0011 2.0 s12
10 Jev 1.13Decision modelTypeSafe
572
429–720
571–0.5 s0.0%$0.0013 0.6 s12
15 Elephant 1Decision modelBaseten
571
420–699
614–0.5 s0.0%$0.0008 0.6 s12
15 Mammoth 1Decision modelBaseten
571
429–719
571–0.6 s0.0%$0.0017 0.6 s12
15 Clef OmniDecision modelCloudflare
571
429–719
616–0.5 s0.0%$0.0049 0.6 s12
15 Gemini Decision 1Decision modelGoogle
571
434–727
755–0.7 s0.0%$0.0023 0.8 s12
15 Drex Max FinanceDecision modelNace AI
571
420–710
614–0.7 s0.0%$0.0010 1.2 s12
15 Drex v2.0Decision modelNace AI
571
420–710
571–0.6 s0.0%$0.0009 1.0 s12
15 Parallel Decisions FastDecision modelParallel
571
420–710
529–0.8 s0.0%$0 1.0 s12
15 Decider v1.2Decision modelPerplexity
571
429–719
572–0.6 s0.0%$0.0003 0.9 s12
15 Span-02Decision modelRespan
571
428–724
614–0.9 s0.0%$0.0002 1.2 s12
24 Gemini 4 Hydrogen (low reasoning)Google
557
370–727
––2.6 s62.5%$0.0439 ––
24 Gemini 4 HydrogenGoogle
557
370–727
–1,0523.4 s62.5%$0.0451 ––
26 GPT-6.1 Sol UltrafastOpenAI
540
296–765
1979271.7 s41.7%$0.36 3.0 s12
27 Joey 1Decision modelBaseten
529
409–642
529–0.5 s0.0%$0.0003 0.5 s12
27 Clef FlashDecision modelCloudflare
529
388–670
529–0.5 s0.0%$0.0025 0.7 s12
27 ClefDecision modelCloudflare
529
373–653
529–0.7 s0.0%$0.0056 1.0 s12
27 Gemini 3.1 Pro Preview (low reasoning)Google
529
329–698
––3.1 s58.3%$0.0446 4.4 s12
27 Gemini 3.8 FlashGoogle
529
263–688
–1,1262.8 s58.3%$0.0154 4.8 s12
27 Inkling Small (no reasoning)Thinking Machines
529
393–652
571–0.6 s0.0%$0.0075 1.5 s12
27 Jev 1.14Decision modelTypeSafe
529
404–671
529–0.5 s0.0%$0.0014 0.5 s12
34 Claude Fable 5.2 (low reasoning)Anthropic
491
230–714
––3.0 s62.5%$0.0800 4.3 s8
34 Claude Fable 5.2Anthropic
491
187–738
–1,1003.4 s62.5%$0.0948 5.3 s8
34 Mercury 3 (no reasoning)Inception
491
299–659
555–0.4 s0.0%$0.0020 ––
37 Microsoft Decision 1Decision modelMicrosoft
490
381–600
453–0.6 s0.0%$0.0009 0.7 s12
38 GPT-6 Luna DecisionsDecision modelOpenAI
489
376–608
529–0.5 s0.0%$0.0026 0.7 s12
38 Decider Flash v1.2Decision modelPerplexity
489
363–621
489–0.5 s0.0%$0.0003 0.6 s12
40 Seed-2.0-Mini (minimal reasoning)ByteDance
453
355–538
571–0.3 s0.0%$0.0030 0.4 s12
41 Drex v1.5Decision modelNace AI
449
266–608
489–0.6 s8.3%$0.0007 0.9 s12
42 Claude Haiku 4.5Anthropic
445
135–626
334911.2 s25.0%$0.0163 1.7 s12
42 GPT-6 Sol (no reasoning)OpenAI
445
215–639
––1.6 s50.0%$0.0297 2.1 s12
44 Muse Wonder (minimal reasoning)Meta
409
100–609
––1.9 s58.3%$0.0663 4.1 s12
45 Mistral Medium 3.5Mistral AI
385
276–464
5295550.5 s8.3%$0.0420 1.0 s12
45 Decider V1 27BDecision modelPerplexity
385
279–459
420–0.6 s8.3%$0.0010 0.8 s12
47 Mistral Small 4 (no reasoning)Mistral AI
367
126–564
571–0.6 s25.0%$0.0039 1.1 s12
48 Gemini 4 Carbon (low reasoning)Google
358
0–619
–8483.2 s75.0%$0.0167 5.9 s8
48 GPT-6.1 Terra (low reasoning)OpenAI
358
0–595
491–2.8 s75.0%$0.0172 5.1 s8
48 GLM-5.3 FlashX Legal (low reasoning)Z.ai
358
0–600
310–1.4 s37.5%$0.0061 3.0 s8
51 GPT-6.1 Sol (low reasoning)OpenAI
323
51–529
––2.2 s75.0%$0.0243 ––
51 GPT-6 Astra (low reasoning)OpenAI
323
0–528
––2.3 s75.0%$0.10 5.7 s12
53 Claude Haiku 5.5 (no reasoning)Anthropic
310
0–575
––1.7 s37.5%$0.0019 2.5 s8
53 Muse Ember (minimal reasoning)Meta
310
0–595
––1.8 s62.5%$0.0038 3.2 s8
55 GPT-6 Luna (no reasoning)OpenAI
249
0–453
––1.5 s50.0%$0.0016 2.3 s12
56 GPT-5.4 mini (no reasoning)OpenAI
197
0–445
571–0.9 s50.0%$0.0205 ––
56 GPT-6 AstraOpenAI
197
0–439
–8393.0 s83.3%$0.0943 6.1 s12
58 DeepSeek-V4.1-Flash-1017 (low reasoning)DeepSeek
147
0–443
––3.3 s87.5%$0.0047 ––
58 Gemini 4 ArgonGoogle
147
0–381
–1,1472.9 s87.5%$0.0036 9.8 s8
58 Mercury 3 (low reasoning)Inception
147
0–381
––4.2 s87.5%$0.0032 16.1 s8
58 Muse Ember (low reasoning)Meta
147
0–381
––2.8 s75.0%$0.0106 8.4 s8
58 Muse EmberMeta
147
0–443
––3.4 s87.5%$0.0108 22.2 s8
58 Kimi K3.1 Pro (low reasoning)Moonshot AI
147
0–381
––5.0 s87.5%$0.0175 18.1 s8
64 MiniMax M3.1 Flash (low reasoning)MiniMax
115
0–485
––3.0 s75.0%$0.0016 9.3 s8
65 Muse Spark 1.3 (minimal reasoning)Meta
33
0–270
––4.2 s91.7%$0.0142 11.4 s12
65 Kimi K3 (low reasoning)Moonshot AI
33
0–270
––2.6 s91.7%$0.0540 11.3 s12
65 GPT-5.4 nano (no reasoning)OpenAI
33
0–273
197–1.1 s66.7%$0.0050 ––
65 GPT-6.1 SolOpenAI
33
0–270
–6453.0 s91.7%$0.0210 8.7 s12
65 GLM-5.3 (low reasoning)Z.ai
33
0–270
––1.6 s83.3%$0.0220 ––
65 GLM-5.3Z.ai
33
0–270
––3.6 s91.7%$0.0156 ––

Swipe the table sideways for more columns.

Source: Spring Prompt, springprompt.com/benchmarks/bulletbench. Test your own prompt on these models →

Ranks follow the score as shown, so equal numbers share a rank. ≈ marks results whose 95% range overlaps the leader's: they cannot be told apart from it. Each model runs at its provider's default reasoning setting and, where the provider offers a faster one, again at its fastest setting, listed separately. Blitz 3+2 was run at default settings only. Equal ratings are not a glitch: the ladder's ratings come in steps (see Honest caveats below).

Progress over time

Ladder Elo, plotted at each model's release date, higher is better. Each model counts once, at its best setting. Scores are today's, not launch day's; 27 models without a known release date are left off. Hover or tap a mark for its model.

Best score so far

Every model at its release date. The line moves each time a new release beats every earlier one, and each new best is named where there is room.

-50005001,0001,500 2026AprJulOct Claude Haiku 4.5Gemini 3.1 Pro PreviewGemini 3.1 Flash-LiteGemini 3.8 Flash

Best score by lab

Each lab's best so far, stepping whenever one of its releases beats its own earlier models. The 6 labs with the best scores today; 5 others not drawn.

GoogleOpenAIMistral AIThinking MachinesAnthropicInception

05001,000 2026AprJulOct GoogleOpenAIMistral AIThinking MachinesAnthropicInception

Too slow for the clock

These configurations lost their first four games on time, so they were stopped there and are not rated for that clock. Each shows its median time per move and the time that 1 move in 10 took or exceeded: a median under the increment still loses on time when the slow tail is long. Being too slow is the result, not a fault.

Bullet 60s

  • Claude Fable 5.1 median 4.2 s, 1 in 10 moves 6.3 s+
  • Claude Fable 5.1 (low reasoning) median 4.3 s, 1 in 10 moves 9.3 s+
  • Claude Haiku 5.5 median 4.6 s, 1 in 10 moves 8.1 s+
  • Claude Haiku 5.5 (low reasoning) median 3.6 s, 1 in 10 moves 9.5 s+
  • Claude Opus 5.5 median 3.1 s, 1 in 10 moves 5.8 s+
  • Claude Opus 5.5 (low reasoning) median 3.1 s, 1 in 10 moves 5.3 s+
  • Claude Sonnet 5.5 median 3.0 s, 1 in 10 moves 9.4 s+
  • Claude Sonnet 5.5 (low reasoning) median 2.6 s, 1 in 10 moves 5.0 s+
  • DeepSeek V4 Pro 0423 median 5.0 s, 1 in 10 moves 27.8 s+
  • DeepSeek V4.1 Flash (low reasoning) median 1.9 s, 1 in 10 moves 10.6 s+
  • DeepSeek V4.1 Flash 1017 median 2.4 s, 1 in 10 moves 20.0 s+
  • Gemini 3.1 Pro Preview median 4.9 s, 1 in 10 moves 8.4 s+
  • Gemini 4 Argon (low reasoning) median 5.0 s, 1 in 10 moves 5.0 s+
  • Gemini 4 Carbon median 5.1 s, 1 in 10 moves 8.7 s+
  • Mercury 3 median 4.2 s, 1 in 10 moves 25.6 s+
  • Kev 4B median 1.9 s, 1 in 10 moves 15.4 s+
  • Muse Spark 1.3 median 7.0 s, 1 in 10 moves 28.1 s+
  • Muse Wonder median 3.6 s, 1 in 10 moves 8.1 s+
  • MiniMax M3.1 Flash median 4.1 s, 1 in 10 moves 17.9 s+
  • minimax/minimax-m3.1-flash:free median 3.9 s, 1 in 10 moves 20.8 s+
  • minimax/minimax-m3.1-flash:free (low reasoning) median 3.0 s, 1 in 10 moves 8.4 s+
  • Mistral Large 4 median 0.8 s, 1 in 10 moves 2.9 s+
  • Kimi K3 median 3.2 s, 1 in 10 moves 33.8 s+
  • Kimi K3.1 Pro median 6.1 s, 1 in 10 moves 16.1 s+
  • GPT-6 Luna median 4.6 s, 1 in 10 moves 10.8 s+
  • GPT-6 Sol median 4.2 s, 1 in 10 moves 9.4 s+
  • GPT-6.1 Terra median 3.4 s, 1 in 10 moves 7.3 s+
  • Particle-1 median 4.3 s, 1 in 10 moves 12.7 s+
  • Particle-1 (low reasoning) median 4.4 s, 1 in 10 moves 12.8 s+
  • Qwen3.8 Flash median 3.8 s, 1 in 10 moves 16.9 s+
  • Qwen3.8 Max (0902) median 4.9 s, 1 in 10 moves 22.8 s+
  • Qwen3.8 Max (0902) (minimal reasoning) median 4.7 s, 1 in 10 moves 10.3 s+
  • Grok 4.7 median 4.7 s, 1 in 10 moves 17.7 s+
  • Grok 4.7 (low reasoning) median 5.4 s, 1 in 10 moves 15.5 s+
  • MiMo-V2.6-Flash median 4.0 s, 1 in 10 moves 11.7 s+
  • GLM 4.7 Flash median 9.7 s, 1 in 10 moves 23.1 s+
  • GLM 5.3 Flash (low reasoning) median 2.2 s, 1 in 10 moves 5.3 s+
  • GLM 5.3 FlashX Legal median 2.1 s, 1 in 10 moves 11.0 s+

Lightning 10+1

  • Claude Fable 5.1 median 4.4 s, 1 in 10 moves 6.7 s+
  • Claude Fable 5.1 (low reasoning) median 4.1 s, 1 in 10 moves 6.7 s+
  • Claude Fable 5.2 median 2.2 s, 1 in 10 moves 4.1 s+
  • Claude Fable 5.2 (low reasoning) median 3.7 s, 1 in 10 moves 4.4 s+
  • Claude Haiku 5.5 median 1.9 s, 1 in 10 moves 4.8 s+
  • Claude Haiku 5.5 (low reasoning) median 1.9 s, 1 in 10 moves 2.9 s+
  • Claude Haiku 5.5 (no reasoning) median 1.8 s, 1 in 10 moves 2.2 s+
  • Claude Opus 5.5 median 3.0 s, 1 in 10 moves 3.5 s+
  • Claude Opus 5.5 (low reasoning) median 2.8 s, 1 in 10 moves 3.3 s+
  • Claude Sonnet 5.5 median 2.1 s, 1 in 10 moves 2.7 s+
  • DeepSeek V4 Pro 0423 median 4.6 s, 1 in 10 moves 6.6 s+
  • DeepSeek V4.1 Flash (low reasoning) median 0.8 s, 1 in 10 moves 1.7 s+
  • DeepSeek V4.1 Flash 1017 median 1.4 s, 1 in 10 moves 4.9 s+
  • DeepSeek V4.1 Flash 1017 (low reasoning) median 1.2 s, 1 in 10 moves 5.3 s+
  • Gemini 3.1 Pro Preview median 2.7 s, 1 in 10 moves 3.4 s+
  • Gemini 3.1 Pro Preview (low reasoning) median 2.5 s, 1 in 10 moves 3.0 s+
  • Gemini 3.8 Flash median 2.3 s, 1 in 10 moves 2.9 s+
  • Gemini 4 Argon median 3.5 s, 1 in 10 moves 5.2 s+
  • Gemini 4 Argon (low reasoning) median 2.6 s, 1 in 10 moves 6.6 s+
  • Gemini 4 Carbon median 3.6 s, 1 in 10 moves 4.1 s+
  • Gemini 4 Carbon (low reasoning) median 2.6 s, 1 in 10 moves 4.4 s+
  • Gemini 4 Hydrogen median 1.8 s
  • Gemini 4 Hydrogen (low reasoning) median 1.9 s
  • Mercury 3 median 0.9 s, 1 in 10 moves 2.7 s+
  • Mercury 3 (low reasoning) median 1.2 s, 1 in 10 moves 4.7 s+
  • Muse Ember median 1.7 s, 1 in 10 moves 5.0 s+
  • Muse Ember (low reasoning) median 1.7 s, 1 in 10 moves 2.9 s+
  • Muse Ember (minimal reasoning) median 1.4 s, 1 in 10 moves 2.6 s+
  • Muse Spark 1.3 median 4.6 s, 1 in 10 moves 9.5 s+
  • Muse Spark 1.3 (minimal reasoning) median 2.2 s, 1 in 10 moves 4.9 s+
  • Muse Wonder median 2.9 s, 1 in 10 moves 3.9 s+
  • Muse Wonder (minimal reasoning) median 1.6 s, 1 in 10 moves 2.8 s+
  • MiniMax M3.1 Flash median 2.8 s, 1 in 10 moves 4.5 s+
  • MiniMax M3.1 Flash (low reasoning) median 2.2 s, 1 in 10 moves 3.4 s+
  • minimax/minimax-m3.1-flash:free median 1.9 s, 1 in 10 moves 3.8 s+
  • minimax/minimax-m3.1-flash:free (low reasoning) median 1.8 s, 1 in 10 moves 3.9 s+
  • Kimi K3 median 1.4 s, 1 in 10 moves 6.5 s+
  • Kimi K3 (low reasoning) median 1.7 s, 1 in 10 moves 4.2 s+
  • Kimi K3.1 Pro median 4.5 s, 1 in 10 moves 5.8 s+
  • Kimi K3.1 Pro (low reasoning) median 3.6 s, 1 in 10 moves 4.6 s+
  • GPT-6 Astra median 2.0 s, 1 in 10 moves 3.4 s+
  • GPT-6 Astra (low reasoning) median 2.1 s, 1 in 10 moves 3.1 s+
  • GPT-6 Luna median 2.9 s, 1 in 10 moves 4.2 s+
  • GPT-6 Luna (no reasoning) median 2.1 s, 1 in 10 moves 3.1 s+
  • GPT-6 Sol median 1.6 s, 1 in 10 moves 3.7 s+
  • GPT-6 Sol (no reasoning) median 1.6 s, 1 in 10 moves 2.0 s+
  • GPT-6.1 Sol median 2.0 s, 1 in 10 moves 3.4 s+
  • GPT-6.1 Sol (low reasoning) median 1.6 s, 1 in 10 moves 3.2 s+
  • GPT-6.1 Terra median 1.3 s, 1 in 10 moves 3.4 s+
  • Particle-1 median 2.2 s, 1 in 10 moves 3.5 s+
  • Particle-1 (low reasoning) median 1.3 s, 1 in 10 moves 3.6 s+
  • Qwen3.8 Flash median 2.5 s, 1 in 10 moves 3.8 s+
  • Qwen3.8 Max (0902) median 3.1 s, 1 in 10 moves 4.6 s+
  • Qwen3.8 Max (0902) (minimal reasoning) median 2.9 s, 1 in 10 moves 4.9 s+
  • Grok 4.7 median 2.5 s, 1 in 10 moves 5.5 s+
  • Grok 4.7 (low reasoning) median 2.3 s, 1 in 10 moves 4.3 s+
  • MiMo-V2.6-Flash median 3.1 s, 1 in 10 moves 4.6 s+
  • GLM 4.7 Flash median 4.4 s, 1 in 10 moves 6.0 s+
  • GLM 5.3 median 1.8 s, 1 in 10 moves 6.2 s+
  • GLM 5.3 (low reasoning) median 1.2 s, 1 in 10 moves 4.0 s+
  • GLM 5.3 Flash (low reasoning) median 0.9 s, 1 in 10 moves 2.6 s+
  • GLM 5.3 FlashX Legal median 1.3 s, 1 in 10 moves 3.1 s+

Blitz 3+2

  • DeepSeek V4 Pro 0423 median 6.4 s, 1 in 10 moves 29.7 s+
  • DeepSeek V4.1 Flash 1017 median 4.7 s, 1 in 10 moves 62.2 s+
  • Mercury 3 median 9.0 s, 1 in 10 moves 72.7 s+
  • Muse Ember median 6.1 s, 1 in 10 moves 48.0 s+
  • Muse Spark 1.3 median 19.4 s, 1 in 10 moves 60.0 s+
  • MiniMax M3.1 Flash median 9.1 s, 1 in 10 moves 46.9 s+
  • minimax/minimax-m3.1-flash:free median 5.3 s, 1 in 10 moves 76.0 s+
  • Mistral Large 4 (high reasoning) median 26.1 s, 1 in 10 moves 69.5 s+
  • Kimi K3 median 6.8 s, 1 in 10 moves 32.1 s+
  • Kimi K3.1 Pro median 10.8 s, 1 in 10 moves 47.7 s+
  • GPT-6 Sol median 8.2 s, 1 in 10 moves 22.9 s+
  • Particle-1 median 5.0 s, 1 in 10 moves 39.3 s+
  • Qwen3.8 Max (0902) median 7.4 s, 1 in 10 moves 88.9 s+
  • Grok 4.7 median 9.9 s, 1 in 10 moves 32.9 s+
  • GLM 5.3 FlashX Legal median 3.0 s, 1 in 10 moves 33.7 s+

Decision models

Decision models answer a typed question instead of writing text. Each move is one question whose options are the legal moves, so they cannot play an illegal move, and they are not told their clock. They play the same clock, ladder and engine and are in the table above; here they are ranked among themselves.

BulletBench Bullet 60s: ladder Elo, ladder Elo, higher is better
#ModelBullet 60s · 95% range
ladder Elo, higher is better
Lightning 10+1
ladder Elo
Move time
seconds
Lost on time
% of games
Cost per game
US dollars
Slowest 10% of moves
seconds, 90th percentile
Games
at this clock
1≈ d1.1Liquid AI
614
470–766
5720.6 s0.0%$0.0003 0.8 s12
1≈ ReflexMorph
614
470–746
6160.6 s0.0%$0.0006 0.7 s12
3≈ d1Liquid AI
584
435–749
5720.6 s0.0%$0.0007 0.7 s12
4≈ Mercury DecideInception
572
428–717
6140.4 s0.0%$0 0.5 s12
4≈ d1 UltraLiquid AI
572
412–727
5290.6 s0.0%$0.0003 1.0 s12
4≈ Drex MaxNace AI
572
412–727
4091.2 s33.3%$0.0011 2.0 s12
4≈ Jev 1.13TypeSafe
572
429–720
5710.5 s0.0%$0.0013 0.6 s12
8≈ Elephant 1Baseten
571
420–699
6140.5 s0.0%$0.0008 0.6 s12
8≈ Mammoth 1Baseten
571
429–719
5710.6 s0.0%$0.0017 0.6 s12
8≈ Clef OmniCloudflare
571
429–719
6160.5 s0.0%$0.0049 0.6 s12
8≈ Gemini Decision 1Google
571
434–727
7550.7 s0.0%$0.0023 0.8 s12
8≈ Drex Max FinanceNace AI
571
420–710
6140.7 s0.0%$0.0010 1.2 s12
8≈ Drex v2.0Nace AI
571
420–710
5710.6 s0.0%$0.0009 1.0 s12
8≈ Parallel Decisions FastParallel
571
420–710
5290.8 s0.0%$0 1.0 s12
8≈ Decider v1.2Perplexity
571
429–719
5720.6 s0.0%$0.0003 0.9 s12
8≈ Span-02Respan
571
428–724
6140.9 s0.0%$0.0002 1.2 s12
17≈ Joey 1Baseten
529
409–642
5290.5 s0.0%$0.0003 0.5 s12
17≈ Clef FlashCloudflare
529
388–670
5290.5 s0.0%$0.0025 0.7 s12
17≈ ClefCloudflare
529
373–653
5290.7 s0.0%$0.0056 1.0 s12
17≈ Jev 1.14TypeSafe
529
404–671
5290.5 s0.0%$0.0014 0.5 s12
21≈ Microsoft Decision 1Microsoft
490
381–600
4530.6 s0.0%$0.0009 0.7 s12
22≈ GPT-6 Luna DecisionsOpenAI
489
376–608
5290.5 s0.0%$0.0026 0.7 s12
22≈ Decider Flash v1.2Perplexity
489
363–621
4890.5 s0.0%$0.0003 0.6 s12
24≈ Drex v1.5Nace AI
449
266–608
4890.6 s8.3%$0.0007 0.9 s12
25 Decider V1 27BPerplexity
385
279–459
4200.6 s8.3%$0.0010 0.8 s12

Swipe the table sideways for more columns.

Source: Spring Prompt, springprompt.com/benchmarks/bulletbench. Test your own prompt on these models →

Too slow for the clock. These lost their first four games on time and are not rated for that clock.

Bullet 60s

  • Kev 4B median 1.9 s, 1 in 10 moves 15.4 s+

Real games: the clock at Lightning 10+1

Each model's clock after every move of one game. A fast model earns back more than it spends; a slow one runs out within a few moves, whatever the position.

0 s5 s10 s15 s 0481216202428 Move Clock left Won by checkmate after 28 moves Gemini 3.5 Flash Lite Lost on time after 3 moves Claude Opus 5.5
Gemini 3.5 Flash LiteWon by checkmate after 28 moves
  1. e40.6 s10.4 s left
  2. Nf30.9 s10.4 s left
  3. Bc40.6 s10.9 s left
  4. O-O0.9 s10.9 s left
  5. c30.6 s11.4 s left
  6. d40.9 s11.4 s left
  7. Nxe51.0 s11.4 s left
  8. Nxc60.6 s11.8 s left
  9. Qxg40.9 s11.9 s left
  10. Qxc8+0.9 s12.0 s left
  11. … 18 more moves
Claude Opus 5.5Lost on time after 3 moves
  1. e43.5 s7.5 s left
  2. Nf33.5 s5.0 s left
  3. d43.3 s2.6 s left

More from the results

Bullet: strength against thinking time

The same at 60 seconds for the whole game, no increment. A 40-move game leaves 1.5 seconds a move.

Named: the six bestOther models (hover for names)

-50005001,0001,500 0.1 s1 s10 s Median time per move (log scale) Ladder Elo 1.5 s a move Gemini 3.8 Flash (low reasoning) GPT-6.1 Sol Ultrafast (low reasoning) Gemini 3.1 Flash-Lite (minimal reasoning) Gemini 3.5 Flash (minimal reasoning) Gemini 3.5 Flash-Lite Gemini 3.6 Flash (minimal reasoning)

How games are lost

Share of games lost on time, and moves with no legal reply, by clock.

ModelOn time, LightningOn time, BulletInvalid moves, LightningInvalid moves, Bullet
Gemini 3.5 Flash-LiteGoogle0.0%0.0%0.0%0.0%
Gemini 3.1 Flash-Lite (minimal reasoning)Google0.0%8.3%0.2%0.0%
Gemini Decision 1Google0.0%0.0%0.0%0.0%
Gemini 3.5 Flash (minimal reasoning)Google33.3%25.0%0.6%0.5%
Clef OmniCloudflare0.0%0.0%0.0%0.0%
ReflexMorph0.0%0.0%0.0%0.0%
Elephant 1Baseten0.0%0.0%0.0%0.0%
Mercury DecideInception0.0%0.0%0.0%0.0%
Drex Max FinanceNace AI0.0%0.0%0.0%0.0%
Span-02Respan0.0%0.0%0.0%0.0%
GPT-6.1 Sol Ultrafast (low reasoning)OpenAI50.0%25.0%0.0%0.0%
d1.1Liquid AI0.0%0.0%0.0%0.0%
d1Liquid AI0.0%0.0%0.0%0.0%
Decider v1.2Perplexity0.0%0.0%0.0%0.0%
Mammoth 1Baseten0.0%0.0%0.0%0.0%
Seed-2.0-Mini (minimal reasoning)ByteDance0.0%0.0%0.8%0.4%
Mistral Small 4 (no reasoning)Mistral AI0.0%25.0%1.0%0.6%
Drex v2.0Nace AI0.0%0.0%0.0%0.0%
GPT-5.4 mini (no reasoning)OpenAI0.0%50.0%0.0%0.0%
Inkling Small (no reasoning)Thinking Machines0.0%0.0%5.3%7.2%
Jev 1.13TypeSafe0.0%0.0%0.0%0.0%
Mercury 3 (no reasoning)Inception0.0%0.0%0.4%0.0%
Joey 1Baseten0.0%0.0%0.0%0.0%
Clef FlashCloudflare0.0%0.0%0.0%0.0%
ClefCloudflare0.0%0.0%0.0%0.0%
d1 UltraLiquid AI0.0%0.0%0.0%0.0%
Mistral Medium 3.5 (no reasoning)Mistral AI0.0%0.0%0.0%0.4%
Mistral Medium 3.5Mistral AI0.0%8.3%0.3%0.8%
GPT-6 Luna DecisionsOpenAI0.0%0.0%0.0%0.0%
Parallel Decisions FastParallel0.0%0.0%0.0%0.0%
Jev 1.14TypeSafe0.0%0.0%0.0%0.0%
GPT-6.1 Terra (low reasoning)OpenAI62.5%75.0%0.0%0.0%
Drex v1.5Nace AI0.0%8.3%0.0%0.0%
Decider Flash v1.2Perplexity0.0%0.0%0.0%0.0%
Microsoft Decision 1Microsoft0.0%0.0%0.0%0.0%
Decider V1 27BPerplexity0.0%8.3%0.0%0.0%
Drex MaxNace AI25.0%33.3%0.0%0.0%
GLM-5.3 FlashX Legal (low reasoning)Z.ai62.5%37.5%0.0%0.0%
Mistral Large 4Mistral AI58.3%–1.8%–
Gemini 3.8 Flash (low reasoning)Google83.3%50.0%0.0%0.0%
GPT-5.4 nano (no reasoning)OpenAI75.0%66.7%4.0%3.1%
GPT-6.1 Sol UltrafastOpenAI83.3%41.7%0.0%0.0%
Claude Haiku 4.5Anthropic83.3%25.0%0.0%0.3%
Claude Sonnet 5.5 (low reasoning)Anthropic91.7%–0.0%–
Gemini 3.6 Flash (minimal reasoning)Google91.7%41.7%0.0%0.3%
Kev 4BJared Palmer66.7%–0.0%–

Lightning: strength against cost

What one Lightning game cost at the run date's prices, on a log scale. Up and to the left is better; the dashed line joins the strongest model at each cost.

Named: the six best and the best for the moneyOther models (hover for names)Best score at each cost

-200300800 $0.0001$0.001$0.01$0.1$1 Cost per game, US dollars (log scale) Ladder Elo Gemini 3.5 Flash-Lite Gemini 3.1 Flash-Lite (minimal reasoning) Gemini Decision 1 Gemini 3.5 Flash (minimal reasoning) Clef Omni Reflex Span-02

Best per budget

  1. Span-02: 614 at $0.0001
  2. Reflex: 616 at $0.0007
  3. Gemini Decision 1: 755 at $0.0018
  4. Gemini 3.1 Flash-Lite (minimal reasoning): 780 at $0.0058
  5. Gemini 3.5 Flash-Lite: 892 at $0.0070

Cheapest first: each model here beats every cheaper one on score.

How BulletBench works

  1. 1

    The position

    The model gets the position, the moves so far, its remaining clock and the legal moves.

  2. 2

    The reply

    It answers with one move. The whole API round trip, including any hidden reasoning, comes off its clock.

  3. 3

    The engine

    Stockfish replies instantly at the model's current ladder level.

  4. 4

    The ladder

    Win and the next game is a level up; lose and it is a level down; draw and it stays. The results give a rating with a 95% interval.

Why chess on a clock

Many products need an answer in about a second: routing, triage, autocomplete, live agents. BulletBench asks which models can still think usefully at that speed. Chess gives a hard, objective score, and the clock makes slow thinking a real cost instead of a free extra.

The clocks

Lightning 10+1
Ten seconds, plus one second a move. A model can play for ever, but only at about a second an answer.
Bullet 60s
One minute for the whole game, no increment.
Blitz 3+2
Three minutes plus two seconds a move: room for reasoning models, for comparison.

Fair play

Same prompt
Every model gets the same system prompt and position format.
Invalid replies
A reply with no legal move gets two corrective retries, then a random legal move is played and counted.
Settings
Each model runs at its provider's default and, where the provider offers one, its fastest reasoning setting, shown separately.

Honest caveats

A dozen games or fewer per clock (the table gives each configuration's count) give wide intervals, so neighbouring ranks are often within each other's ranges. Ratings also come in steps: the engine plays at fixed levels and the rating is fitted from which levels a model beat, drew or lost to, so models with the same results against the same levels get exactly the same rating. Latency depends on the provider's servers on the day. The ladder's Elo anchors come from v1's Stockfish; this edition runs Stockfish 19, so ratings are not comparable with v1's.

What it measures

  • Decision quality under real time pressure
  • Response latency at the provider's default settings
  • Which reasoning settings are fast enough to use

What it does not measure

  • Any business skill: this is chess against an engine
  • Chess strength without a clock

Method

  • Games against a Stockfish ladder; every second of response time comes off the model's clock
  • Each model at its default setting and, where offered, its fastest reasoning setting
  • Ladder Elo with a 95% interval; it orders models, it is not a FIDE rating

How all our benchmarks work

Use the data

Every result on this page is free to reuse under CC BY 4.0: results.csv · results.json. Credit Spring Prompt with a link. All downloads · Embed the chart

Embed this chart

Put BulletBench's current top 10 in your article. Free to reuse under CC BY 4.0; the code includes the credit link. Add ?n=5 for fewer rows, ?models= with model slugs (as in our model page addresses) for your own comparison, or ?theme=dark.

Interactive chart

<iframe src="https://springprompt.com/embed/bulletbench" title="BulletBench results by Spring Prompt" width="100%" height="456" style="border:0;max-width:720px" loading="lazy"></iframe>
<p><a href="https://springprompt.com/benchmarks/bulletbench">BulletBench results by Spring Prompt</a></p>

Image, for sites that block iframes

<a href="https://springprompt.com/benchmarks/bulletbench"><img src="https://springprompt.com/og/benchmarks/bulletbench.png" alt="BulletBench: the top 10 AI models by ladder elo" width="1200" height="630" style="max-width:100%;height:auto"></a>
<p><a href="https://springprompt.com/benchmarks/bulletbench">BulletBench results by Spring Prompt</a></p>
See the image