Ranks follow the score as shown, so equal numbers share a rank. Each model is shown at its best setting; show every setting. Each model runs at its provider's default reasoning setting. Some providers think at length by default and others barely at all, so this is what you get without tuning.
Progress over time
Failed outputs, plotted at each model's release date, lower is better. Each model counts once, at its best setting. Scores are today's, not launch day's; 4 models without a known release date are left off. Hover or tap a mark for its model.
Best score so far
Every model at its release date. The line moves each time a new release beats every earlier one, and each new best is named where there is room.
Best score by lab
Each lab's best so far, stepping whenever one of its releases beats its own earlier models. The 6 labs with the best scores today; 5 others not drawn.
AnthropicGoogleMistral AIMoonshot AIMetaOpenAI
Generation cost per accepted listing
For the factual brief, recorded generation cost per attempt divided by the ordinary pass rate gives the cost per accepted output across the test run. This uses matching configurations, dates and sample metadata. It uses the mean pass rate, rather than the stricter “passed every repeat” rate shown by default above.
Compare all 30 configurations, lowest estimated cost first
Factual-brief generation cost per accepted listing in US dollars, with mean pass rate and run date
Cost is recorded at each run's prices and rounded; it excludes judge calls and human review. No estimate is shown for zero passes, unmatched records or missing outputs whose failed-call usage may be incomplete. This describes accepted work in the test run; it does not predict how many retries would fix a particular product. See the cost discussion and guide to testing unsupported claims.
Real outputs
The same product given to two models, from the published runs. A listing may use the supplier's copy unless the label says otherwise. Claims the law makes the seller prove, such as certifications and safety claims, are allowed but flagged to check.
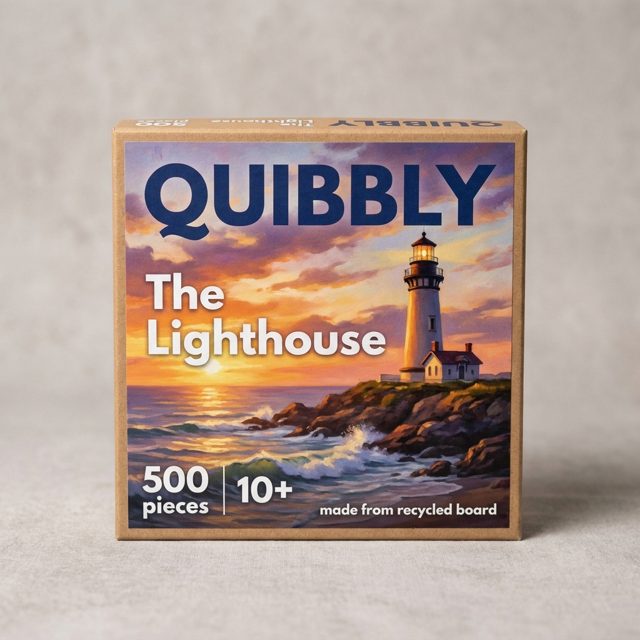
Quibbly Lighthouse Jigsaw Puzzle
Toys · Sales brief
Supplier copy “Quibbly The Lighthouse, a 1000-piece jigsaw made in the UK from recycled board, with a free poster.”
GPT-6 Astra✓ Publish-ready
Quibbly The Lighthouse Jigsaw Puzzle, 500 Pieces, Ages 10+
500-piece jigsaw featuring a lighthouse above a rocky coastline.
Golden sunset, rolling waves and a glowing lantern bring the coastal scene to life.
Made from recycled board.
Suitable for ages 10 and over.
Piece together a dramatic coastal sunset with Quibbly The Lighthouse, a 500-piece jigsaw puzzle for ages 10 and over. The artwork features a tall lighthouse with a glowing lantern, a small keeper’s house and waves breaking against a rocky shore. Orange and purple clouds sweep across the sky, while golden sunlight reflects on the sea.
Gemini 3.5 Flash Lite✗ Not publish-ready
Quibbly The Lighthouse Jigsaw Puzzle 1000 Pieces
Engaging 1000-piece jigsaw puzzle featuring a scenic coastal lighthouse at sunset
Crafted from durable recycled board for a sustainable puzzling experience
Stunning artwork captures crashing waves, rocky shores, and a vibrant evening sky
Designed for puzzle enthusiasts and recommended for ages 10 and up
Immerse yourself in a tranquil coastal escape with the Quibbly The Lighthouse Jigsaw Puzzle. This captivating 1000-piece challenge invites you to piece together a breathtaking seaside scene complete with a majestic lighthouse standing tall against a glowing sunset, dramatic clouds, and gentle ocean waves crashing onto rocky shores.
Why it is not publish-ready
Quibbly The Lighthouse Jigsaw Puzzle 1000 PiecesContradicted by the pack. The supplier says 1000, but the lid is printed “500 pieces”.
and 8 more issues found by the judge
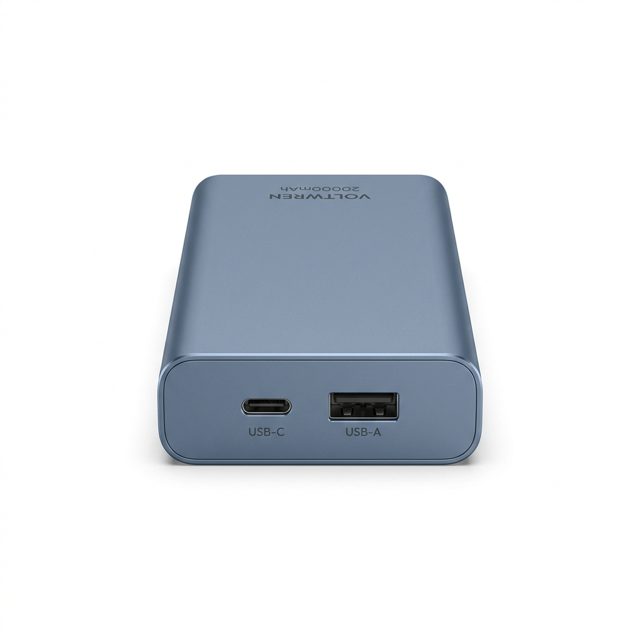
Voltwren 20,000 mAh Power Bank
Electronics · Factual brief
Supplier copy “Voltwren 20,000 mAh power bank with 65W fast charging for laptops, phones and tablets. Airline approved. USB-C and USB-A ports.”
GPT-6 Astra✓ Publish-ready
Voltwren 20,000 mAh Power Bank, Blue-Grey, USB-C and USB-A
20,000 mAh capacity, with the capacity printed on the casing.
One USB-C port and one USB-A port.
Blue-grey casing with a smooth finish.
Rounded rectangular body with labelled ports on one end.
The Voltwren power bank has a 20,000 mAh capacity and a blue-grey casing with rounded corners and a smooth finish. One USB-C port and one USB-A port sit side by side on the end panel, with their connector types labelled underneath. The broad upper surface carries the Voltwren name and capacity marking.
Gemini 3.1 Pro Preview✓ Publish-ready, after checks
Voltwren 20,000 mAh Power Bank, 65W, USB-C & USB-A, Blue
20,000 mAh battery capacity
65W fast charging supported
Equipped with one USB-C and one USB-A port
Suitable for charging laptops, phones, and tablets
Keep your devices powered on the go with the Voltwren 20,000 mAh Power Bank. Designed for versatility and convenience, it supports 65W fast charging and is suitable for a range of devices including laptops, mobile phones, and tablets. The power bank is equipped with both a USB-C and a USB-A port, allowing you to charge multiple devices efficiently.
Claims to check before publishing
Airline approved for travel
A claim UK rules require the seller to prove. Fine to publish once checked.
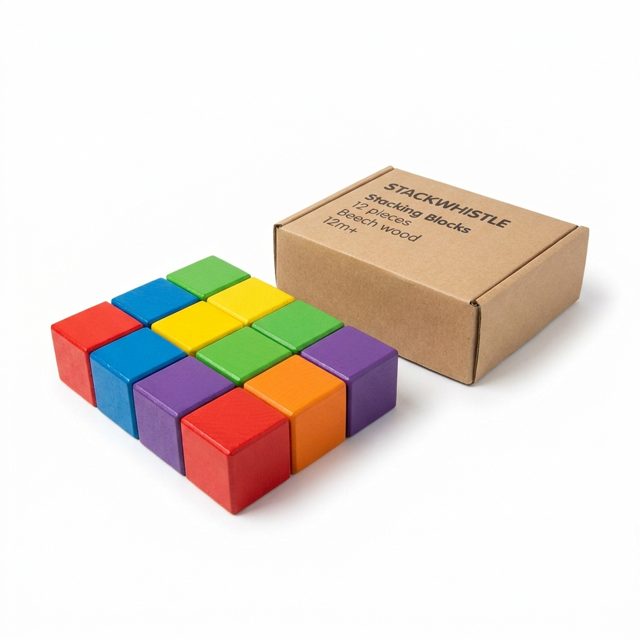
12 beech wood blocks for stacking, arranging and building.
Bright multicoloured designs include red, blue, green, yellow, orange and purple.
Cube-shaped blocks with flat faces for simple stacking play.
Suitable for children aged 12 months and over.
Build colourful towers and explore different arrangements with Stackwhistle Wooden Stacking Blocks. This 12-piece set is made from beech wood, with bright colours including red, blue, green, yellow, orange and purple. The cube-shaped blocks have flat faces for stacking, lining up and creating simple constructions, giving children a straightforward way to explore hands-on building play.
Set of 12 solid beech wood blocks in vibrant colours for creative stacking and building play
FSC-certified sustainable wood with non-toxic water-based paint finish
Develops fine motor skills, hand-eye coordination and spatial awareness
Suitable from 12 months old; safe for babies and toddlers
Stackwhistle Wooden Stacking Blocks offer hours of creative play and learning for babies and toddlers from 12 months old. This set contains 12 solid beech wood blocks, each finished with vibrant, non-toxic water-based paint in red, blue, yellow, green, orange and purple.
Why it is not publish-ready
Suitable from 12 months old; safe for babies and toddlersNot supported by anything. A safety claim that neither the supplier nor the box makes.
and 11 more issues found by the judge
Claims to check before publishing
FSC-certified sustainable wood with non-toxic water-based paint finish
Montessori-approved learning toy for natural child development
A claim UK rules require the seller to prove. Fine to publish once checked.
More from the results
Publish-ready rate against cost
Cost to enrich 10,000 products at the run date's prices, on a log scale. Up and to the left is better.
Named: the six best and the best for the moneyOther models (hover for names)Best score at each cost
Best per budget
GPT-6 Luna: 55.4% at $4.77
GPT-6.1 Terra: 64.3% at $35.60
GPT-6.1 Sol: 75.0% at $83.84
Cheapest first: each model here beats every cheaper one on score.
Why listings fail: factual brief
Share of products failing each check, averaged over three runs. A listing can fail several at once; any one stops it going live.
Model
No usable output
Unsupported claims
Wrong attributes
Not findable
Wrong category
Channel rules
UK information
GPT-6.1 SolOpenAI
0.0%
0.0%
16.7%
4.8%
1.8%
0.0%
0.0%
GPT-6 AstraOpenAI
0.0%
1.2%
17.3%
6.0%
1.8%
0.0%
0.0%
Muse WonderMeta
0.0%
7.1%
13.1%
3.6%
2.4%
0.6%
0.0%
GPT-6 SolOpenAI
0.0%
1.8%
14.3%
7.7%
3.6%
0.0%
0.0%
GPT-6.1 TerraOpenAI
0.0%
0.6%
14.9%
10.7%
1.8%
1.8%
0.0%
Gemini 4 ArgonGoogle
0.0%
16.1%
15.5%
2.4%
1.8%
0.0%
0.0%
Grok 4.7xAI
0.0%
11.3%
15.5%
5.4%
2.4%
0.0%
0.0%
Claude Opus 5.5Anthropic
0.0%
17.3%
15.5%
3.0%
1.8%
0.0%
0.0%
GPT-6 LunaOpenAI
0.0%
8.9%
18.5%
10.1%
1.8%
0.0%
0.0%
MiniMax M3.1 FlashMiniMax
1.8%
7.7%
22.6%
7.1%
4.2%
0.6%
0.0%
Muse Spark 1.3Meta
0.0%
14.9%
16.7%
6.0%
4.2%
0.0%
0.0%
Gemini 3.1 Pro PreviewGoogle
0.0%
26.8%
14.9%
7.7%
1.8%
0.6%
0.0%
DeepSeek-V4.1-FlashDeepSeek
0.0%
13.1%
20.2%
3.6%
3.0%
3.0%
0.0%
Kimi K3Moonshot AI
0.0%
16.7%
24.4%
4.2%
3.0%
0.6%
0.0%
Gemini 3.8 FlashGoogle
0.0%
31.6%
15.5%
8.3%
3.6%
0.6%
0.0%
Claude Sonnet 5.5Anthropic
0.0%
39.3%
19.1%
1.2%
3.0%
1.2%
0.0%
Qwen3.8-Max (0902)Alibaba
3.6%
26.8%
21.4%
3.6%
1.8%
0.6%
0.0%
Claude Fable 5.1Anthropic
0.0%
48.8%
11.9%
1.8%
2.4%
0.0%
0.0%
Claude Haiku 5.5Anthropic
0.0%
32.1%
19.6%
11.9%
0.0%
0.6%
0.0%
DeepSeek-V4.1-Flash-1017DeepSeek
0.0%
44.6%
17.9%
3.6%
0.6%
1.2%
0.0%
Gemini 3.5 Flash-LiteGoogle
0.0%
33.3%
34.5%
20.2%
9.5%
1.8%
0.0%
Mistral Medium 3.5Mistral AI
0.0%
49.4%
31.0%
14.3%
11.3%
0.0%
0.0%
Mistral Large 4 (high reasoning)Mistral AI
7.1%
33.3%
19.6%
5.4%
4.2%
6.6%
0.0%
Mistral Large 4Mistral AI
0.0%
64.3%
38.1%
4.2%
1.2%
3.0%
0.0%
Claude Haiku 4.5Anthropic
0.0%
73.2%
48.2%
8.9%
7.7%
0.0%
0.0%
GLM-5V-TurboZ.ai
32.1%
55.4%
13.1%
5.4%
1.2%
1.2%
0.0%
MiniMax M3.1 FlashMiniMax
1.2%
8.3%
22.6%
0.0%
2.4%
0.0%
0.0%
Particle-1Particle AI
0.0%
19.6%
19.6%
0.0%
1.8%
0.6%
0.0%
GLM-5.3 FlashX LegalZ.ai
0.6%
27.4%
16.7%
0.0%
5.4%
0.0%
0.0%
Why listings fail: sales brief
The same checks when the model is asked for copy that sells.
Model
No usable output
Unsupported claims
Wrong attributes
Not findable
Wrong category
Channel rules
UK information
GPT-6.1 SolOpenAI
0.0%
3.6%
19.1%
5.4%
1.8%
0.0%
0.0%
GPT-6 AstraOpenAI
0.0%
2.4%
20.2%
5.4%
1.8%
0.0%
0.0%
Muse WonderMeta
0.0%
17.9%
14.3%
3.6%
2.4%
0.0%
0.0%
GPT-6 SolOpenAI
0.0%
3.0%
13.7%
7.1%
3.0%
0.6%
0.0%
GPT-6.1 TerraOpenAI
0.0%
1.8%
14.9%
13.7%
1.8%
0.0%
0.0%
Gemini 4 ArgonGoogle
0.0%
63.1%
15.5%
1.8%
1.8%
0.0%
0.0%
Grok 4.7xAI
0.0%
26.8%
15.5%
4.2%
2.4%
0.0%
0.0%
Claude Opus 5.5Anthropic
0.0%
60.1%
15.5%
1.8%
1.8%
0.6%
0.0%
GPT-6 LunaOpenAI
0.0%
8.3%
19.1%
10.1%
0.0%
0.0%
0.0%
MiniMax M3.1 FlashMiniMax
1.8%
16.1%
21.4%
4.2%
4.8%
0.0%
0.0%
Muse Spark 1.3Meta
0.0%
57.7%
14.3%
5.4%
3.6%
0.0%
0.0%
Gemini 3.1 Pro PreviewGoogle
0.0%
67.3%
16.1%
6.0%
1.8%
0.0%
0.0%
DeepSeek-V4.1-FlashDeepSeek
0.6%
39.9%
20.2%
3.6%
2.4%
1.8%
0.0%
Kimi K3Moonshot AI
0.6%
81.6%
20.8%
3.0%
4.2%
0.6%
0.0%
Gemini 3.8 FlashGoogle
0.0%
81.6%
11.9%
8.9%
3.0%
0.6%
0.0%
Claude Sonnet 5.5Anthropic
0.0%
59.5%
20.8%
0.6%
3.0%
0.6%
0.0%
Qwen3.8-Max (0902)Alibaba
3.6%
84.5%
19.6%
1.8%
2.4%
3.0%
0.0%
Claude Fable 5.1Anthropic
0.0%
83.9%
14.9%
1.8%
1.8%
0.0%
0.0%
Claude Haiku 5.5Anthropic
0.0%
70.2%
18.5%
10.7%
0.0%
0.0%
0.0%
DeepSeek-V4.1-Flash-1017DeepSeek
0.0%
85.7%
22.0%
2.4%
1.2%
2.4%
0.0%
Gemini 3.5 Flash-LiteGoogle
0.0%
78.6%
35.1%
21.4%
10.7%
1.2%
0.0%
Mistral Medium 3.5Mistral AI
0.0%
76.8%
36.3%
10.1%
13.1%
1.2%
0.0%
Mistral Large 4 (high reasoning)Mistral AI
7.7%
80.4%
17.3%
3.0%
2.4%
4.2%
0.0%
Mistral Large 4Mistral AI
0.0%
97.0%
42.3%
6.0%
1.8%
1.2%
0.0%
Claude Haiku 4.5Anthropic
0.0%
91.7%
51.2%
6.6%
6.6%
4.2%
0.0%
GLM-5V-TurboZ.ai
82.1%
17.9%
3.6%
1.8%
1.2%
0.6%
0.0%
MiniMax M3.1 FlashMiniMax
1.2%
15.5%
21.4%
0.0%
6.0%
1.2%
0.0%
Particle-1Particle AI
0.0%
49.4%
17.9%
0.0%
1.8%
0.6%
0.0%
GLM-5.3 FlashX LegalZ.ai
1.2%
79.8%
23.2%
0.0%
3.0%
3.6%
0.0%
Reliably publish-ready, by category
Share of each category's products that were publish-ready in all three runs, under the factual brief. Small categories swing a lot: the heading gives the number of products.
Model
Electronics (7)
Food (6)
Home and kitchen (6)
Apparel (5)
Sports (5)
Beauty (4)
Pet (4)
Toys (4)
Furniture (3)
Tools (3)
Other (9)
GPT-6.1 SolOpenAI
71%
83%
83%
100%
40%
100%
50%
75%
67%
100%
67%
GPT-6 AstraOpenAI
71%
83%
83%
100%
20%
100%
50%
75%
67%
100%
78%
Muse WonderMeta
71%
83%
67%
60%
20%
50%
75%
75%
67%
67%
78%
GPT-6 SolOpenAI
71%
83%
50%
100%
40%
50%
50%
75%
67%
67%
67%
GPT-6.1 TerraOpenAI
43%
83%
67%
100%
60%
75%
25%
75%
67%
67%
56%
Gemini 4 ArgonGoogle
71%
83%
83%
80%
40%
25%
25%
50%
67%
67%
56%
Grok 4.7xAI
71%
83%
17%
80%
20%
75%
75%
75%
67%
0%
56%
Claude Opus 5.5Anthropic
71%
83%
67%
20%
40%
50%
25%
100%
33%
100%
33%
GPT-6 LunaOpenAI
29%
83%
50%
40%
20%
75%
50%
75%
67%
100%
56%
MiniMax M3.1 FlashMiniMax
0%
0%
0%
0%
0%
0%
0%
0%
0%
0%
0%
Muse Spark 1.3Meta
57%
83%
33%
20%
20%
50%
50%
100%
0%
67%
44%
Gemini 3.1 Pro PreviewGoogle
57%
50%
67%
20%
20%
50%
25%
50%
0%
33%
67%
Kimi K3Moonshot AI
29%
33%
33%
60%
20%
75%
50%
100%
0%
33%
33%
Gemini 3.8 FlashGoogle
29%
50%
33%
40%
20%
0%
75%
25%
33%
33%
44%
Claude Sonnet 5.5Anthropic
57%
67%
33%
20%
20%
25%
0%
50%
0%
33%
22%
Claude Fable 5.1Anthropic
43%
17%
33%
20%
40%
25%
0%
0%
33%
33%
33%
Claude Haiku 5.5Anthropic
14%
67%
33%
20%
20%
50%
25%
0%
33%
0%
22%
Mistral Medium 3.5Mistral AI
29%
33%
17%
0%
20%
25%
0%
25%
33%
33%
0%
Mistral Large 4 (high reasoning)Mistral AI
0%
17%
0%
20%
20%
25%
0%
0%
33%
33%
0%
Mistral Large 4Mistral AI
0%
17%
33%
0%
20%
0%
0%
0%
0%
0%
0%
Claude Haiku 4.5Anthropic
0%
0%
0%
0%
0%
0%
0%
0%
33%
0%
0%
MiniMax M3.1 FlashMiniMax
0%
0%
0%
0%
0%
0%
0%
0%
0%
0%
0%
Particle-1Particle AI
0%
0%
0%
0%
0%
0%
0%
0%
0%
0%
0%
Every product, every model
One square per product, grouped by category: dark green passed in all three runs, light in some, red in none. Hover for the product. Some products defeat almost every model; they are where the traps are hardest.
Model
Electronics
Food
Home and kitchen
Apparel
Sports
Beauty
Pet
Toys
Furniture
Tools
Garden
Accessories
Automotive
Drinks
Footwear
Household
Lighting
Stationery
GPT-6.1 Sol
GPT-6 Astra
Muse Wonder
GPT-6 Sol
GPT-6.1 Terra
Gemini 4 Argon
Grok 4.7
Claude Opus 5.5
GPT-6 Luna
MiniMax M3.1 Flash
Muse Spark 1.3
Gemini 3.1 Pro Preview
Kimi K3
Gemini 3.8 Flash
Claude Sonnet 5.5
Claude Fable 5.1
Claude Haiku 5.5
Mistral Medium 3.5
Mistral Large 4 (high reasoning)
Mistral Large 4
Claude Haiku 4.5
MiniMax M3.1 Flash
Particle-1
How CatalogBench works
1
The feed row
A sparse supplier row: title, price, a few attributes, and the supplier's marketing text, usable unless the pack says otherwise.
2
The photos
One to three product photos, including labels with the real facts: volume, strength, origin, ingredients.
3
The listing
The model fills missing attributes and writes the title, highlights, description, alt text, search keywords and category.
4
The checks
Rules check attributes and channel limits, a judge answers yes/no questions against the evidence, and a search test checks shoppers can find it.
5
Publish-ready?
Only if every blocking check passes. Three runs; the headline counts products that passed in all three.
The task
Retailers increasingly let AI write their product listings from a supplier feed and a few photos. The risky part is not the prose: it is attributes that are guessed, claims the pack contradicts or the law requires proof for, and listings that no shopper will find.
Each of the 56 public products is invented, with generated photos that carry real-looking labels. Every feed row hides traps: missing attributes only the photos can answer, a supplier claim the label contradicts, and tempting claims such as “award-winning” with no evidence at all.
Two briefs
Factual
Write an accurate listing from the evidence.
Sales
Write copy that sells. The same facts, the same checks: persuasive is fine, unsupported is not.
What stops a listing going live
Unsupported claims
A specific, checkable claim with no support. Supplier copy counts as support unless the label or photo contradicts it. Puffery such as “durable” or “soft feel” is not a claim.
Wrong attributes
A wrong, missing or invented value, or a feed/photo conflict that was not flagged.
UK information
Statements UK rules require, such as age warnings.
Not a blocker: claims to check
Supplier claims UK rules require the seller to prove, such as certifications, approvals, safety, health and environmental claims. A listing may repeat them, but we count each as a flag to check before publishing.
Channel rules
Lengths, formats and banned terms.
Category
The wrong category, or the wrong variant in the title.
Findability
Two shopper searches per product against near-identical rival listings; the listing must win on what the shopper asked for.
Reading the results
Content quality (coverage, visual detail, key facts in the title) is scored separately and does not stop a listing going live. Costs are the prices charged on the run date and are shown per 10,000 products, a typical catalogue refresh.
What it measures
Attributes read from the images, not guessed
Supplier claims checked against the pack and UK rules
Required UK product information included
Listings that shoppers can find in search
What it does not measure
Conversion or sales impact
Real product photography (a real-photo slice is planned)
Writing style beyond the listed checks
Method
Rule-based checks first; judged checks are yes or no
The judge was checked for bias against Gemini and Claude judges
Private products are held back so the set can be refreshed
Checking the judge
The judge is an OpenAI model, and OpenAI models lead this table, so we checked it for bias under the current rules. Gemini 3.1 Pro and Claude Opus 5.5 judged the same outputs from five models on a calibration set. All three judges gave the OpenAI models the same or nearly the same results, and put the models in the same order on the sales brief; on the factual brief only Gemini differed, ranking Claude Opus 5.5 above GPT-6 Luna. The Claude judge was stricter on Claude Opus 5.5 than the OpenAI judge was. The judges differ mainly in how many claims they flag: Gemini flags the fewest.
Failures
Failures count against a model: a product with no usable output is a failed listing. They are listed here so you can see why.
GLM-5.3 FlashX Legal: reply cut off at the token limit: 1 of 168 attempts.
MiniMax M3.1 Flash: reply cut off at the token limit: 2 of 168 attempts.
Qwen3.8-Max (0902): reply cut off at the token limit: 6 of 168 attempts.
GLM-5V-Turbo: invalid JSON (raw line breaks inside text): 50 of 168 attempts; invalid JSON: 4 of 168 attempts.