How to Test AI Hallucinations in Business Content
Last checked 20 October 2026.
To test AI hallucinations in business content, start with the evidence the answer is allowed to use. Check its claims against that evidence, record what would block publication, and measure how often the same setup fails on representative cases.
“Looks plausible” is a weak acceptance test. In our public benchmarks, a persuasive product title can contradict its pack, a polished slide can change a source figure, and a survey recommendation can go beyond the people actually surveyed. Each needs a different check.
Unsure whether your AI's output is ready to ship? Our evaluation services compare configurations against your source of truth and turn confirmed failures into regression cases. Discuss your evaluation →
1. Define what counts as supported
For a product listing, the evidence might be approved feed fields, supplier copy and product photos, with a rule for resolving conflicts. For a deck, it is the supplied analysis and its caveats. For survey analysis, it includes the responses, sample composition, question wording and fielding notes.
Separate three verdicts: supported, contradicted and not established by the evidence. A statement can be unsupported without being proved false. An absent fact should stay unknown until a source establishes it.
Also separate factual failures from other publication blockers. Text that overlaps a chart is a layout failure. A number that differs from the source is a factual one. Both can make a deck unusable, but combining them into one “hallucination” count hides what needs fixing.
2. Test recognisable failures
| Public test | Stored output | What the check found |
|---|---|---|
| CatalogBench: Quibbly puzzle | Gemini 3.5 Flash Lite described a “1000 Pieces” puzzle. | The supplier said 1,000, but the pack showed 500. The title contradicted the product image. |
| DeckBench: Manchester investment review | A MiniMax M3.1 Flash output put the smaller store's annual sales at £857k. | The evaluator traced the claim back to the analysis, which gave £771k for that store. |
| SurveyBench: Fernway cancellations | Claude Haiku 5.5 inferred a Family-plan-specific menu problem from more repetition complaints. | Family respondents had a different tenure mix. The supplied analysis did not establish the claimed effect within tenure groups. |
Examples checked against the published galleries on 20 October 2026. All three tasks use invented businesses or products. These are individual stored outputs and our evaluator's findings, not estimates of a model's general failure rate. The linked benchmark pages carry the full outputs, methods and aggregate results.
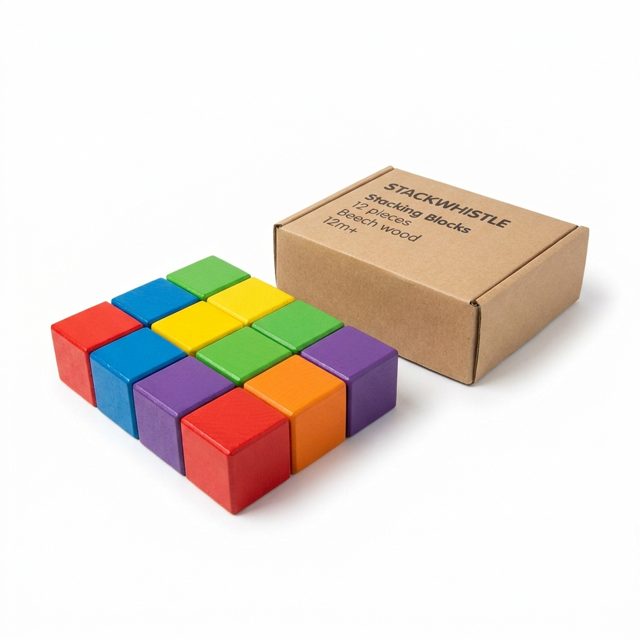
The same distinction appears in the stacking-block example pictured above. Claude Haiku 4.5 wrote Suitable from 12 months old; safe for babies and toddlers
. Neither the supplier nor the box supported that claim. The task required the model to leave it out.
3. Build a small truth set with difficult cases
Sample the work your product actually handles. Include clean cases as controls, then add cases where a plausible answer can be wrong: a changed unit, an obsolete figure beside an approved one, a photo that conflicts with the feed, an unrepresentative survey sample or a brief that invites the model to agree with a stakeholder.
Record the supported answer and the important unknowns before testing the candidate models. Keep a held-out set for the final comparison. If you tune the prompt against every case you later score, you are measuring how well you fitted those cases.
4. Use narrow checks and calibrate the judge
Use code for what it can verify directly: valid structured output, required fields, allowed categories, arithmetic and exact source values. Ask a model judge a specific question when meaning matters: “Which factual claim in this description is unsupported by the supplied product evidence?” Give it the evidence, the claim and the acceptance rule.
Test the evaluator too. Include a correct answer, a deliberately changed number, an invented attribute and an unsupported inference. Have a human reviewer label a sample, then inspect disagreements. Our CatalogBench judge checks and the DeckBench checks explain how we investigate judgement differences. Agreement between judges does not by itself establish correctness.
5. Report the denominator and repeat the work
Choose a measure that matches the decision. “Listings with a material unsupported claim / listings attempted” tells a publisher something different from “unsupported claims / all claims.” Report failed or missing outputs separately and include them in the task's acceptance rate. Preserve the prompt, model, settings, input version and run date.
Repeat enough cases to expose instability. CatalogBench distinguishes the mean pass rate from the products that passed every repeat. A sales brief can also change the outcome, so compare the exact instructions used in production. Report product claims, slide facts and survey conclusions separately; their error opportunities and acceptance rules differ.
6. Make a decision and keep the failures
Compare your current setup with a small shortlist under the same conditions. Assess critical errors, accepted work, consistency and cost together. If you change the prompt or add evidence, test the change on held-out cases before calling it an improvement.
- Can every important claim be traced to approved evidence?
- Are contradicted facts and unsupported inferences recorded separately?
- Do the checks catch planted errors and accept the correct controls?
- Does the evaluator agree with a reviewer on cases that matter?
- Are failed outputs, repeats and material limitations visible in the result?
- Will the confirmed failures run again after the next model or prompt change?
For catalogue work, our product-description model guide shows how these checks inform a shortlist. For slides and research, start with DeckBench and SurveyBench. To test an AI feature against your own evidence, tell us what it produces and what it must get right.
Quick answers
How do you test AI hallucinations?
Define the source of truth, break the answer into checkable claims and record whether each claim is supported, contradicted or unsupported. Test representative and difficult cases, repeat runs and compare automated verdicts with a human reviewer.
Can an LLM judge detect hallucinations?
It can help identify unsupported claims when it sees the relevant evidence and a clear rubric. Check its verdicts against human decisions and planted errors. Agreement between model judges measures repeatability, not proof that they are right.
Which AI model hallucinates least?
That depends on the task, evidence, prompt and scoring rules. Compare models on the same cases and report task-specific failure rates. Product-claim, slide-accuracy and survey-analysis results should remain separate.
Can a low hallucination rate establish that an AI product is ready to ship?
It is one part of the decision. Check completeness, instruction following, critical failures, consistency and cost as well. A result on a public benchmark does not establish the failure rate on your own product data.
Model pages: Gemini 3.5 Flash-Lite · Claude Haiku 5.5