Findings and field notes.
What our benchmarks found, how we run them, and notes on building AI products you can trust.
-
 Benchmarks · · 3 min read
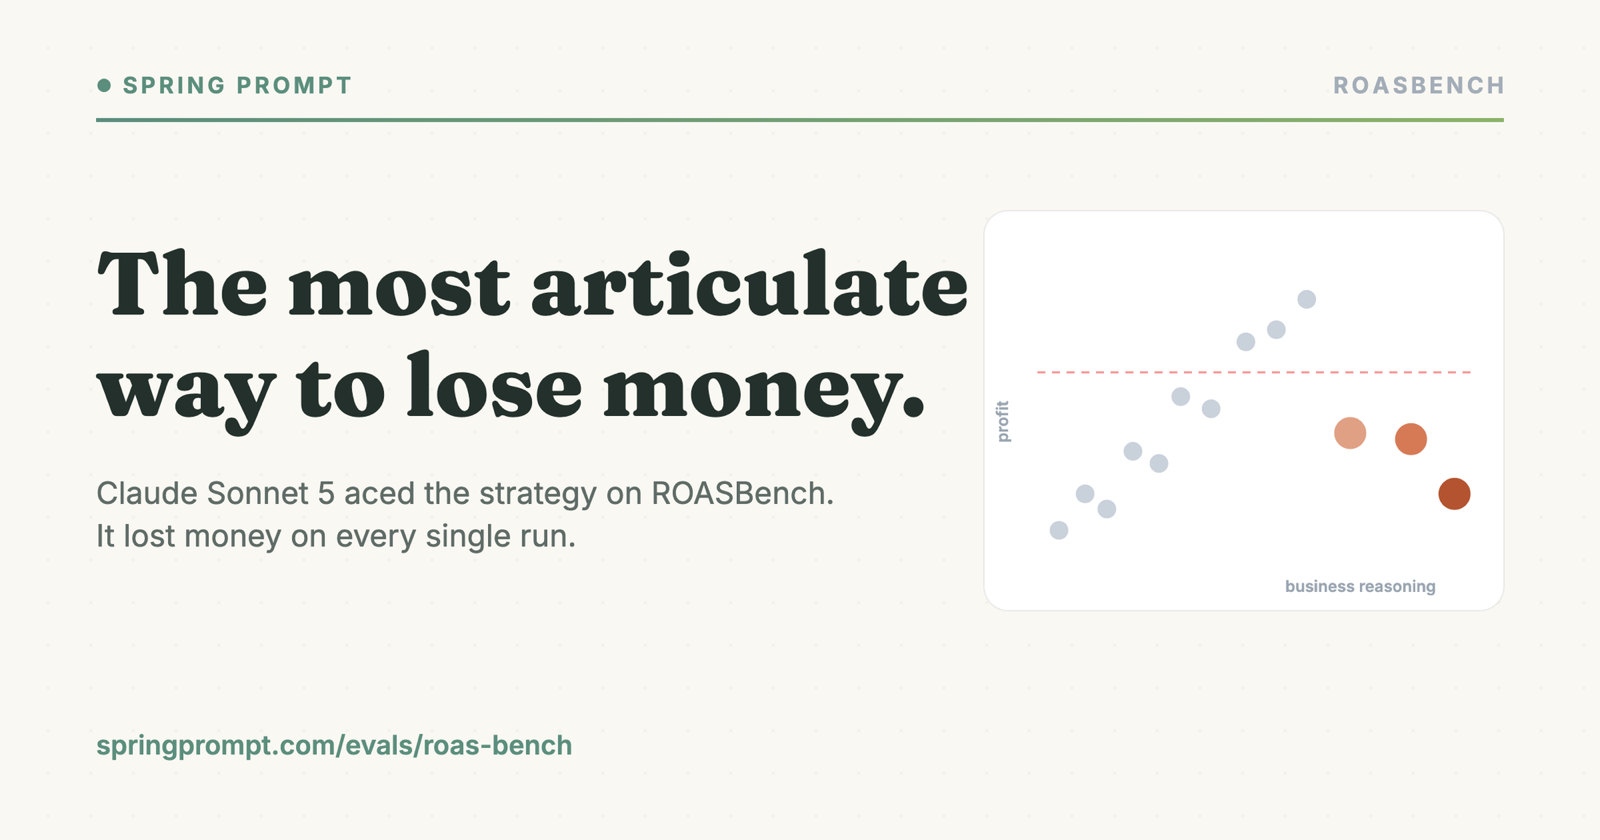
Sonnet 5 gave the sharpest marketing analysis we've ever tested. It also lost money every single time.
A ROASBench case study in why fluent reasoning isn't the same as good decisions, and why for this model more thinking made it worse.
-
 Benchmarks · · 4 min read
Claude vs Gemini vs GPT in a 12-month marketing simulation
ROAS Bench is one of the clearest examples of where frontier models diverge in practice: not on prose quality, but on economic compounding.
-
Benchmarks · · 6 min read
How we built ROASBench to feel like real growth work
ROASBench was built from operator experience, not benchmark theatre. We designed it to feel like real performance marketing: stateful, constrained, path-dependent, and economically unforgiving.
-
Benchmarks · · 4 min read
Why most LLMs still can't run growth
ROAS Bench shows that growth is not a copywriting problem. It is a compounding systems problem, and most models still break the system faster than they improve it.
-
Benchmarks · · 3 min read
The AI marketing benchmark that punishes plausible-sounding strategy
Most LLMs can sound like a competent growth lead for one turn. ROAS Bench is interesting because it makes them live with the consequences for twelve months.