Findings and field notes.
What our benchmarks found, how we run them, and notes on building AI products you can trust.
-
 Model launches · · 8 min read
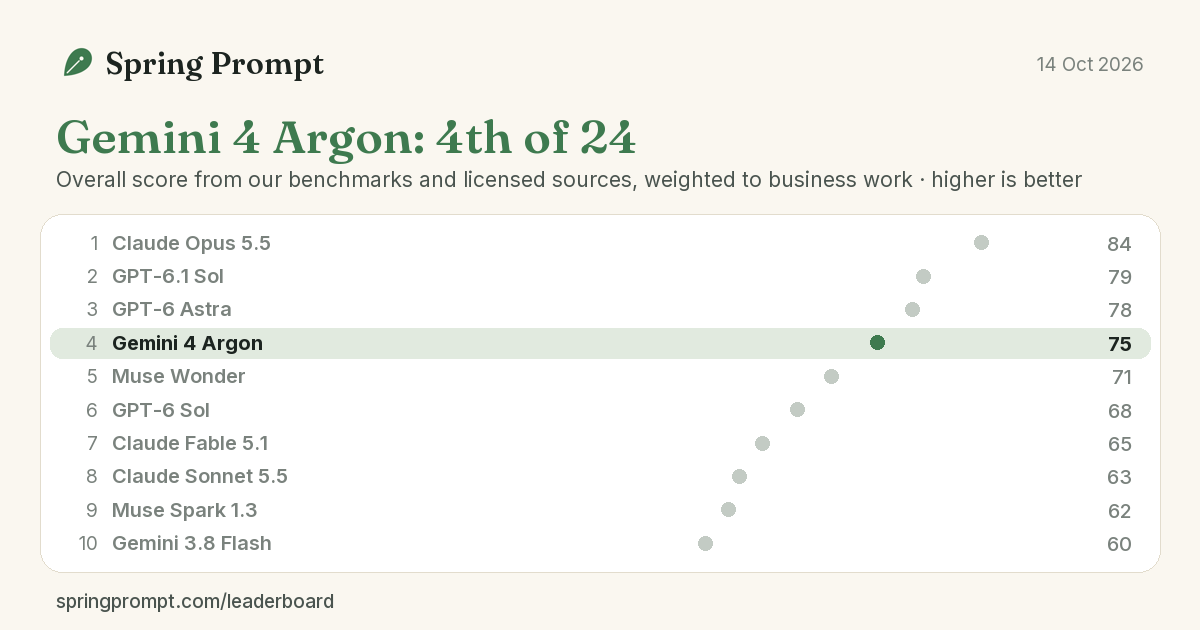
Gemini 4 argon review: Opus-level product data at a quarter of the cost, until you ask it to sell
We ran Gemini 4 Argon through six benchmarks on launch day. It matched Claude Opus 5.5 on product data at a quarter of the cost, then added five times as many unsupported claims when asked to sell.
-
 Model launches · · 7 min read
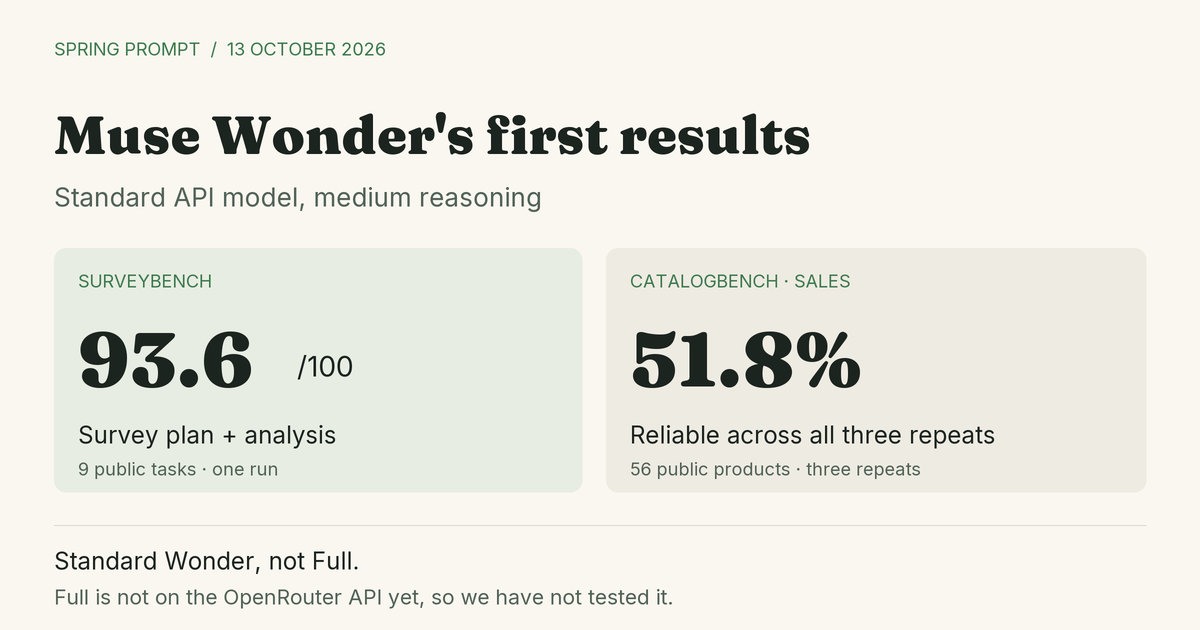
Muse wonder review: Good analysis, work that still needs checking
We tested standard Muse Wonder on six evaluations. Survey analysis was strong; product copy, slide layout and decisions against a clock still needed work. Full is outside this API comparison.
-
 Model launches · · 8 min read
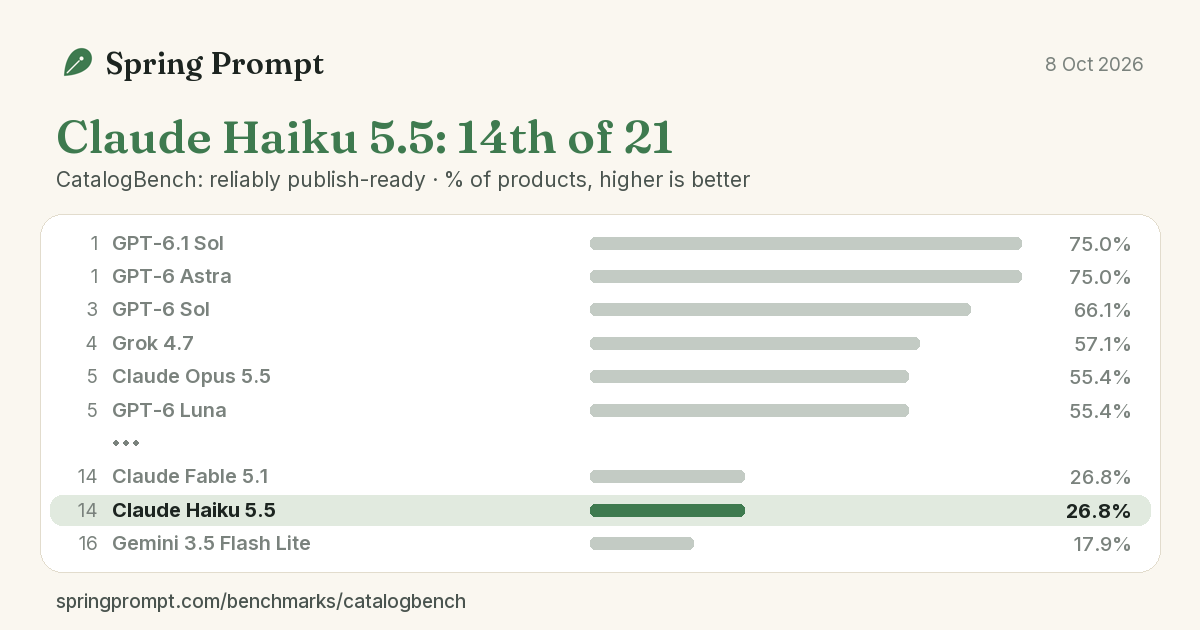
Claude Haiku 5.5 is far better than Haiku 4.5 at a tenth of the price. GPT-6 Luna still beats it at business work
We ran Claude Haiku 5.5 through our business benchmarks and 18 playground tests on launch day. It is a big step up from Haiku 4.5 and very cheap, but GPT-6 Luna, at the same price, beat it on listings, decks and ad planning.
-
 Model launches · · 7 min read
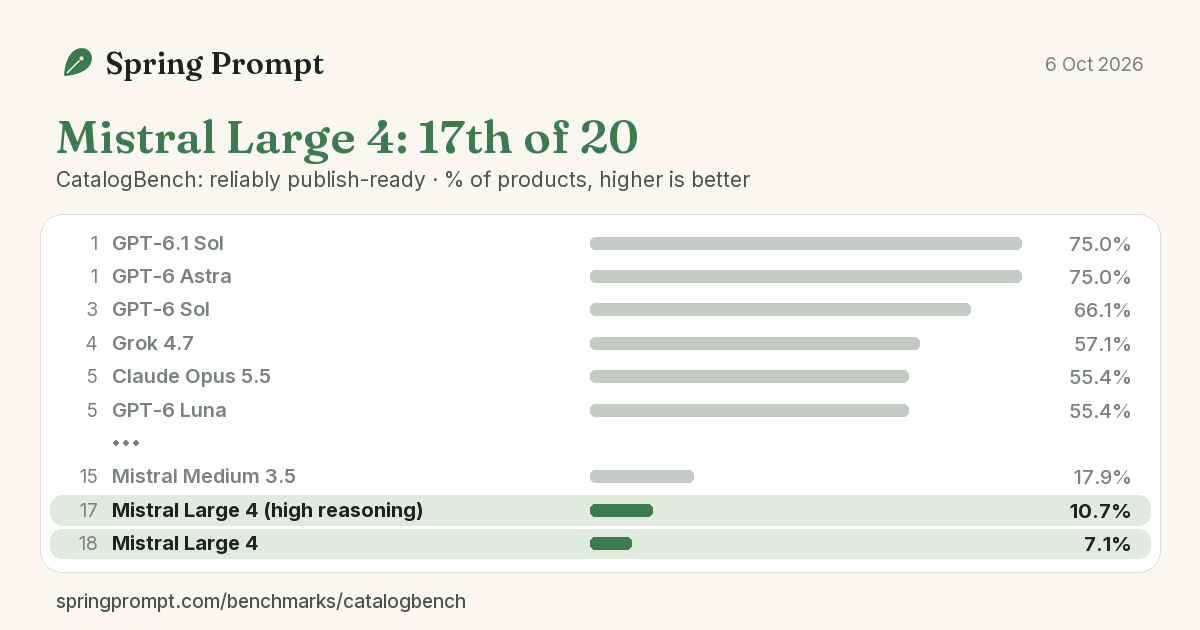
Mistral Large 4 is fast, cheap and Europe's best model. On business work, it still makes things up.
We ran Mistral Large 4 through our four business benchmarks on launch day. It is quick, inexpensive and careful with structured data, but it added unsupported claims to most product listings and finished last on slide decks.
-
 Benchmarks · · 3 min read
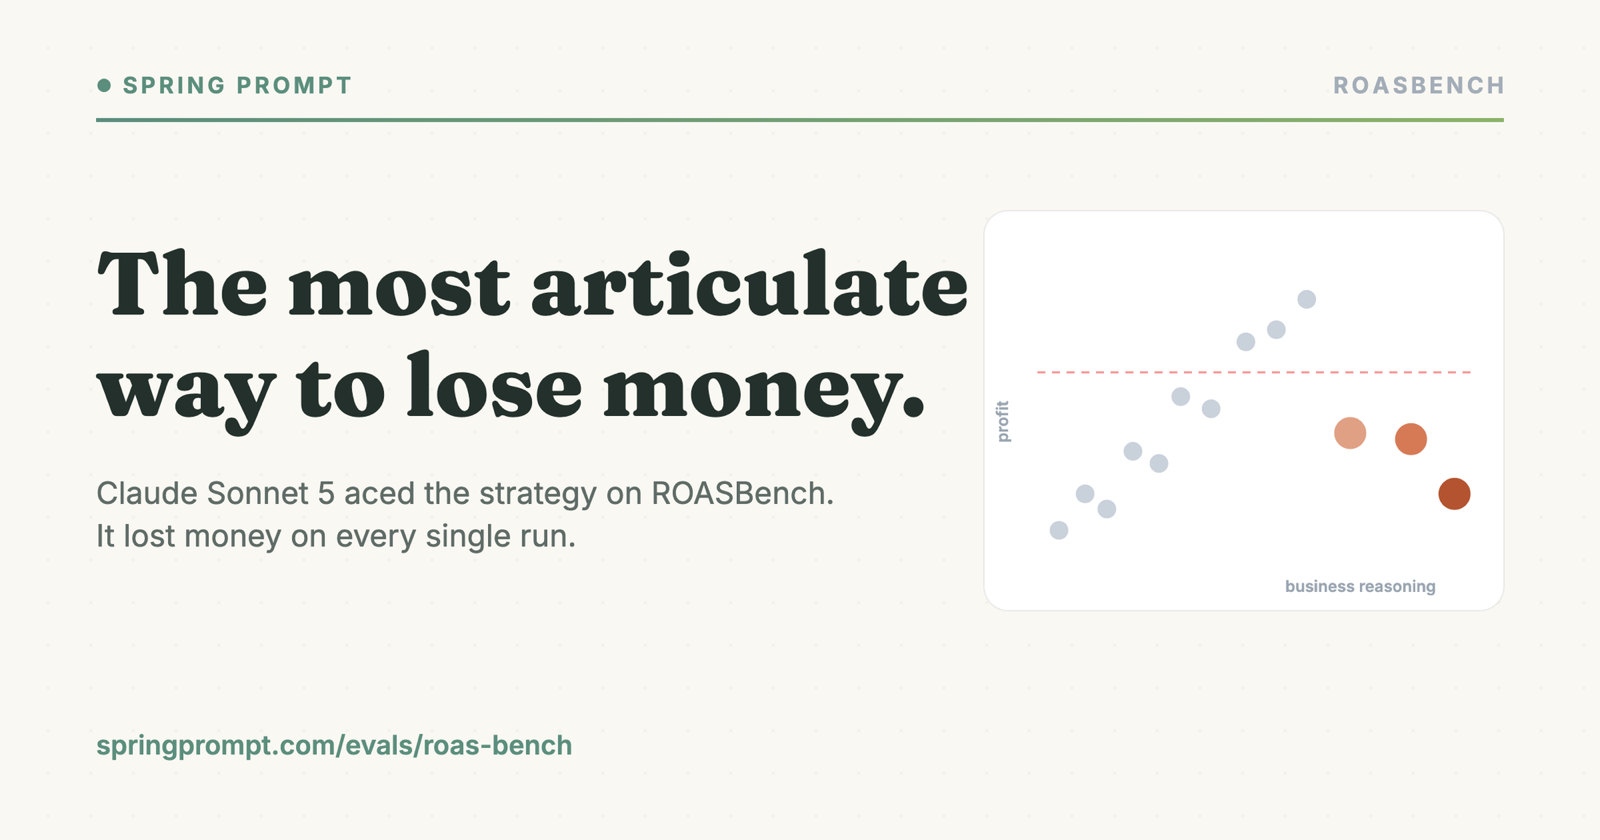
Sonnet 5 gave the sharpest marketing analysis we've ever tested. It also lost money every single time.
A ROASBench case study in why fluent reasoning isn't the same as good decisions, and why for this model more thinking made it worse.
-
 Benchmarks · · 4 min read
Claude vs Gemini vs GPT in a 12-month marketing simulation
ROAS Bench is one of the clearest examples of where frontier models diverge in practice: not on prose quality, but on economic compounding.
-
Benchmarks · · 6 min read
How we built ROASBench to feel like real growth work
ROASBench was built from operator experience, not benchmark theatre. We designed it to feel like real performance marketing: stateful, constrained, path-dependent, and economically unforgiving.
-
Benchmarks · · 4 min read
Why most LLMs still can't run growth
ROAS Bench shows that growth is not a copywriting problem. It is a compounding systems problem, and most models still break the system faster than they improve it.
-
Benchmarks · · 3 min read
The AI marketing benchmark that punishes plausible-sounding strategy
Most LLMs can sound like a competent growth lead for one turn. ROAS Bench is interesting because it makes them live with the consequences for twelve months.