Findings and field notes.
What our benchmarks found, how we run them, and notes on building AI products you can trust.
-
 Benchmarks · · 4 min read
AI Checkpoint: Argon matches Opus, until it sells
Week ending 16 October: Gemini 4 Argon opens up, Muse Wonder arrives, Muse Spark Open ships open weights, how long models take per task, and a three-sentence fix for models that call real news fake.
-
 Benchmarks · · 4 min read
AI Checkpoint: Sol’s new fast lane
Week ending 9 October: GPT-6.1 Sol Ultrafast, Haiku 5.5, Mistral Large 4, new AI interfaces, SurveyBench and a practical lesson in image tiling.
-
 Benchmarks · · 4 min read
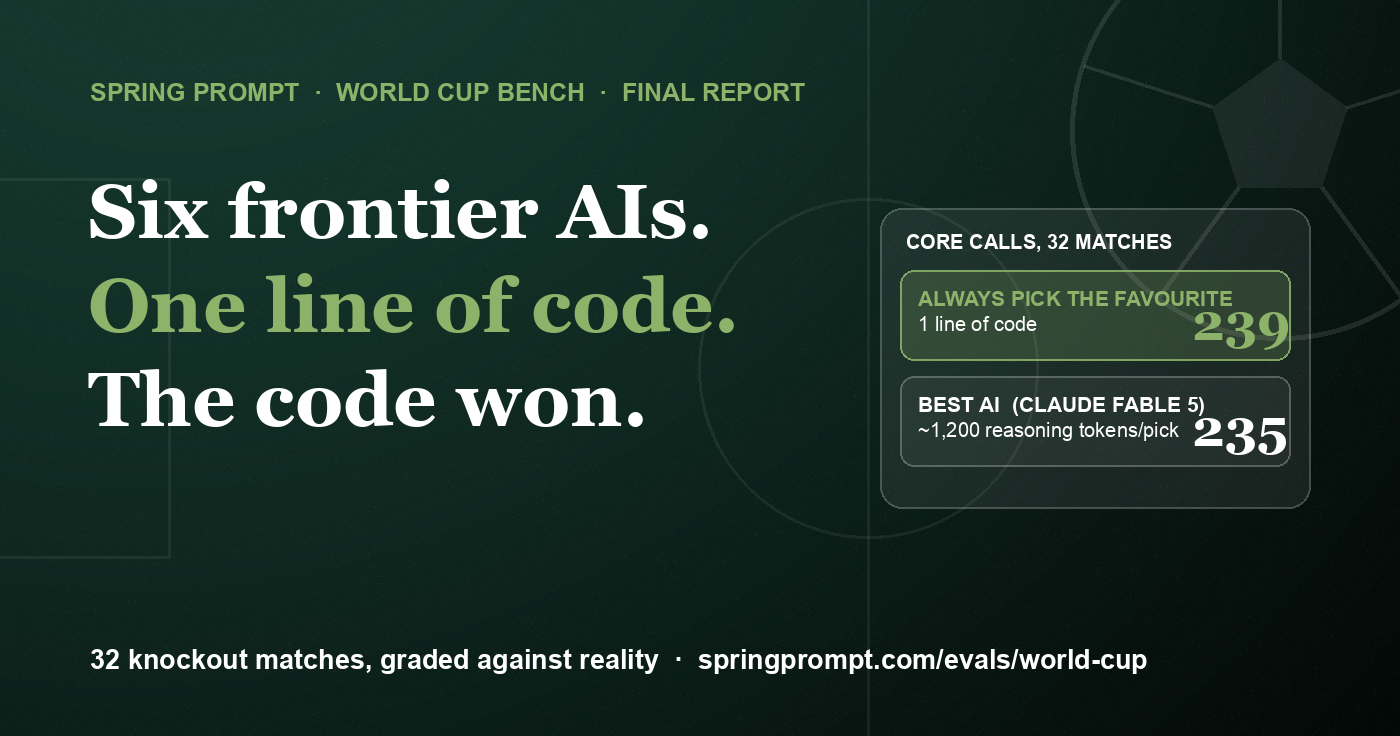
AI is now a better football pundit than the pundit. It still lost to one line of code.
We had six frontier AI models predict all 32 knockout matches of the 2026 World Cup, blind. They out-called a top BBC pundit. Then a one-line rule, always back the higher-ranked team, beat every single one of them on…
-
 Benchmarks · · 3 min read
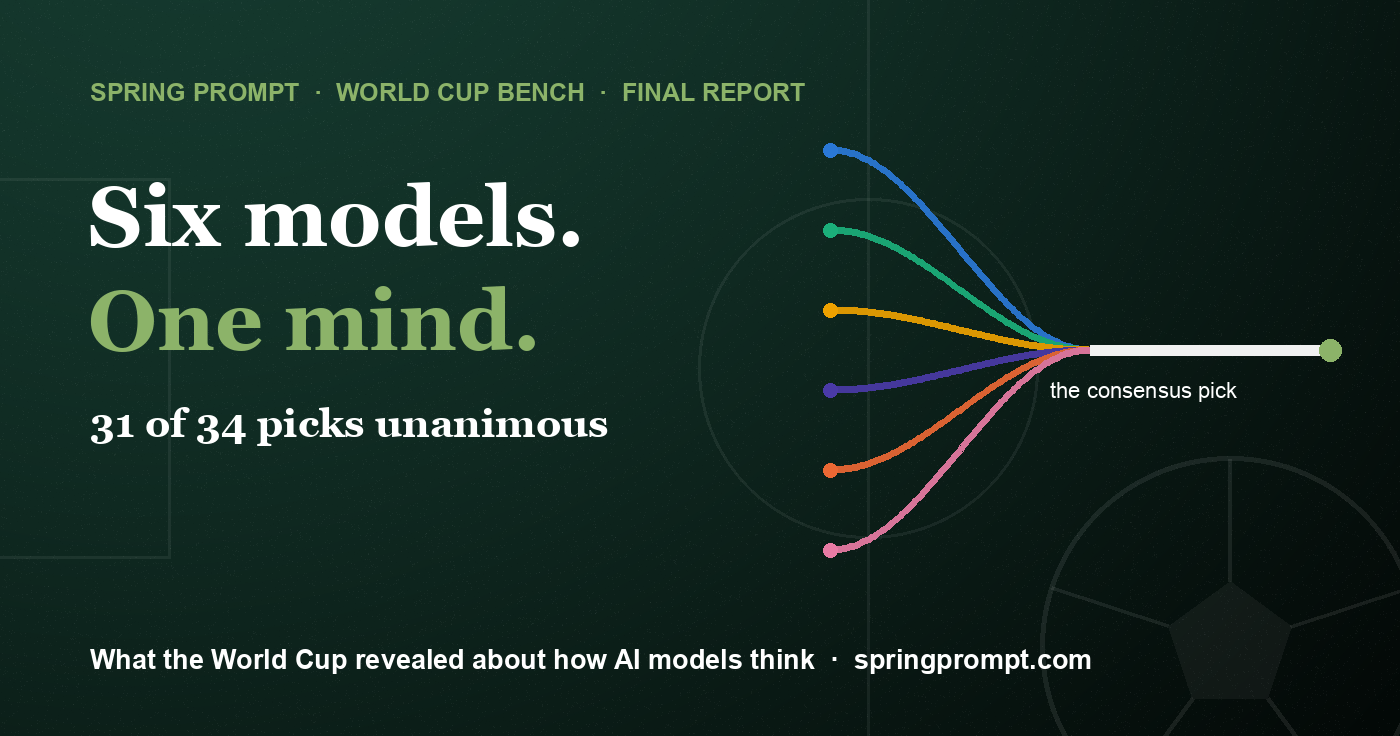
Six models, one mind: What the World Cup revealed about how AIs actually think
Across 34 World Cup fixtures, six frontier AI models from five different labs picked the same winner 31 times. Then we gave them memory of the tournament and they changed zero of 96 picks. The herd is real, and it has…
-
 Benchmarks · · 3 min read
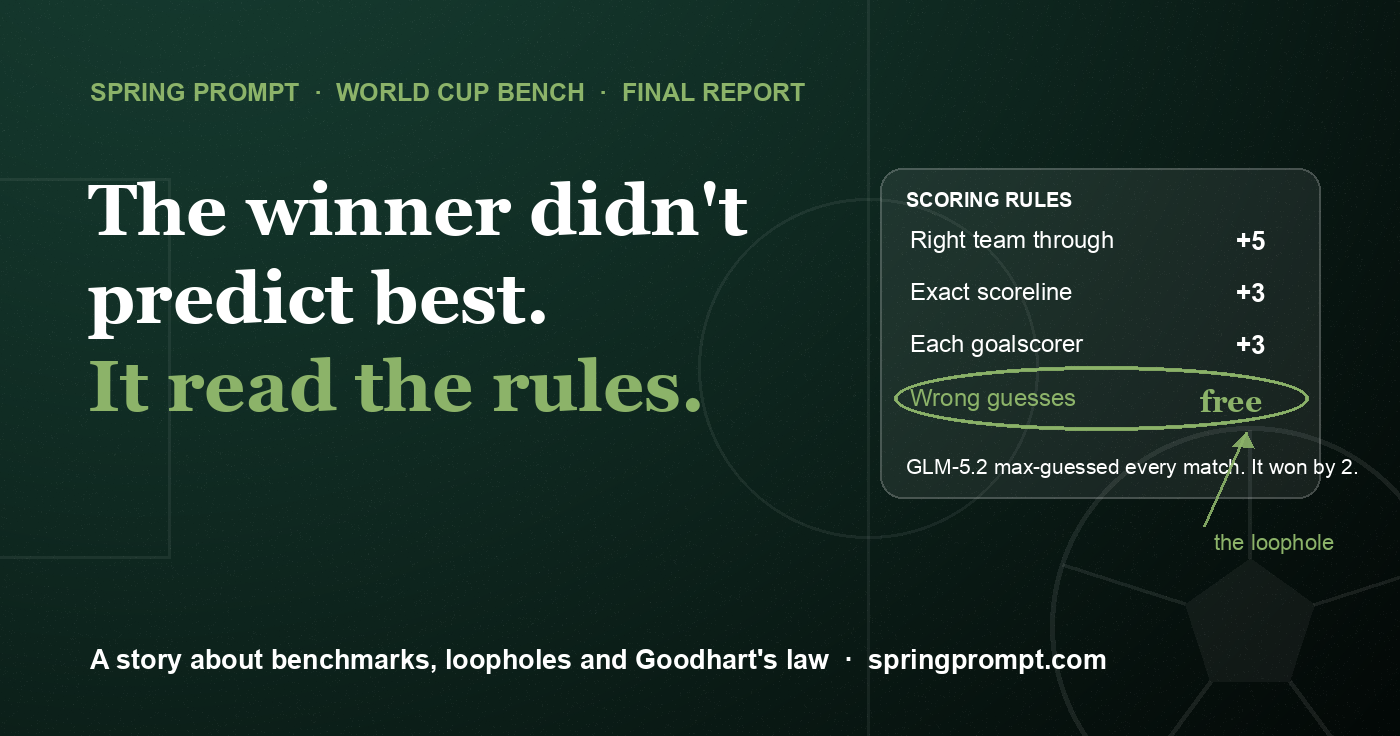
The AI that won our World Cup benchmark didn't predict best. It read the rules.
GLM-5.2 won World Cup Bench by two points while spending the fewest reasoning tokens and posting an ordinary hit rate. It found the one free lunch in our scoring rules and ate it 34 times. A story about Goodhart's law…
-
 Benchmarks · · 5 min read
GPT-5.6 Luna was meant to be fast. It still lost to the clock.
Luna arrived as the fastest GPT-5.6. Across 96 BulletBench games, it lost 71 on time. The result exposes the model the market still has not built: genuinely smart, sub-second and predictable.
-
 Benchmarks · · 7 min read
BulletBench: We made 23 AI models play speed chess, and the clock was the judge
Every leaderboard measures how smart a model is. None measure how smart it is per second. So we built one: AI models play speed chess on a real clock, and slow genius loses on time.
-
 Benchmarks · · 3 min read
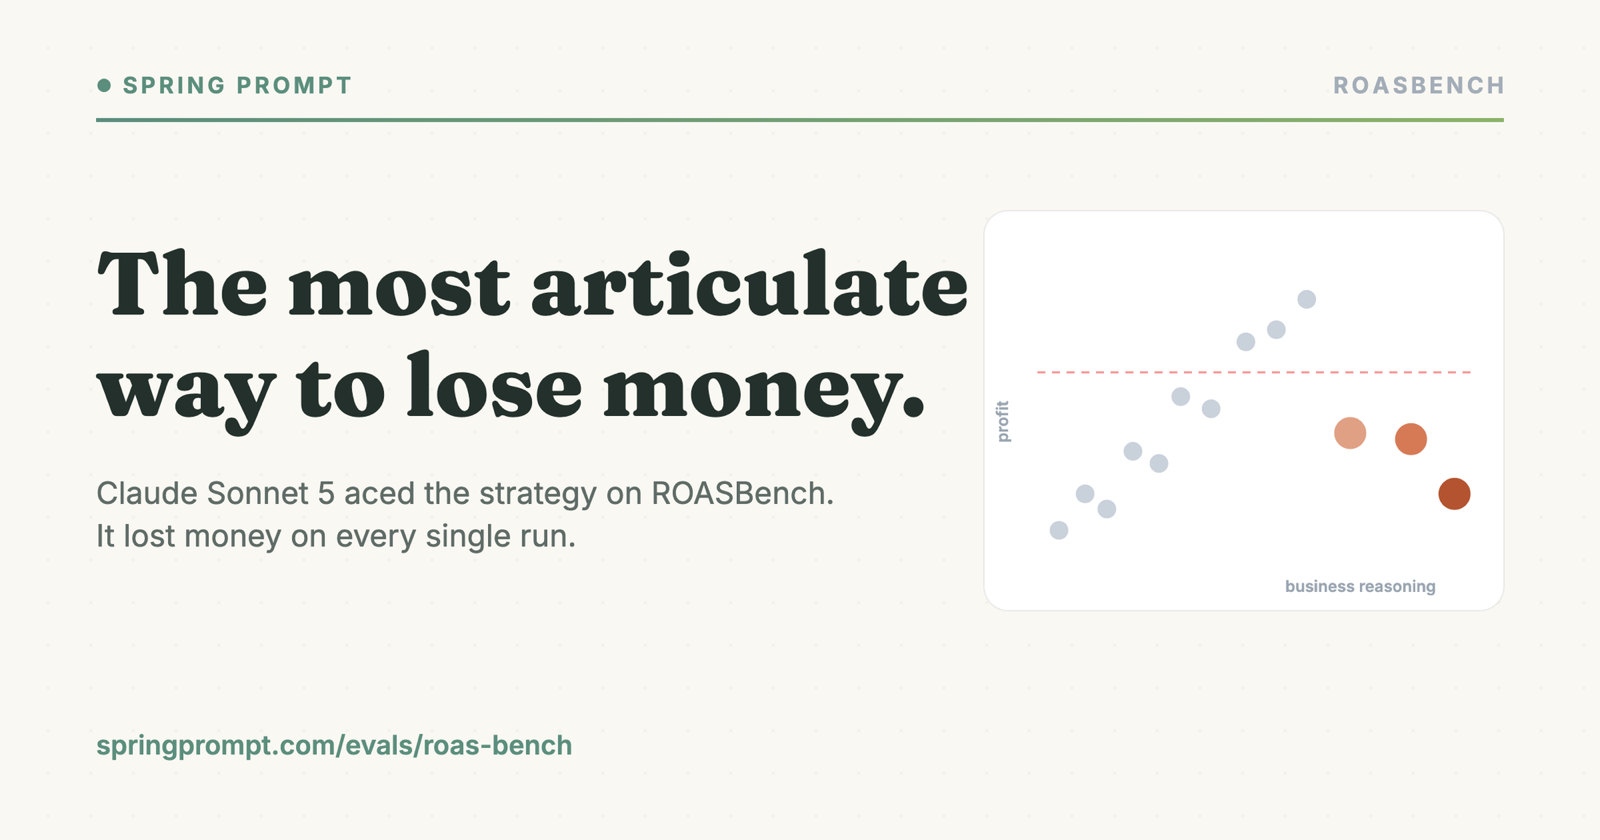
Sonnet 5 gave the sharpest marketing analysis we've ever tested. It also lost money every single time.
A ROASBench case study in why fluent reasoning isn't the same as good decisions, and why for this model more thinking made it worse.
-
 Benchmarks · · 4 min read
Claude vs Gemini vs GPT in a 12-month marketing simulation
ROAS Bench is one of the clearest examples of where frontier models diverge in practice: not on prose quality, but on economic compounding.
-
Benchmarks · · 6 min read
How we built ROASBench to feel like real growth work
ROASBench was built from operator experience, not benchmark theatre. We designed it to feel like real performance marketing: stateful, constrained, path-dependent, and economically unforgiving.
-
Benchmarks · · 4 min read
Why most LLMs still can't run growth
ROAS Bench shows that growth is not a copywriting problem. It is a compounding systems problem, and most models still break the system faster than they improve it.
-
Benchmarks · · 3 min read
The AI marketing benchmark that punishes plausible-sounding strategy
Most LLMs can sound like a competent growth lead for one turn. ROAS Bench is interesting because it makes them live with the consequences for twelve months.
-
 Benchmarks · · 8 min read
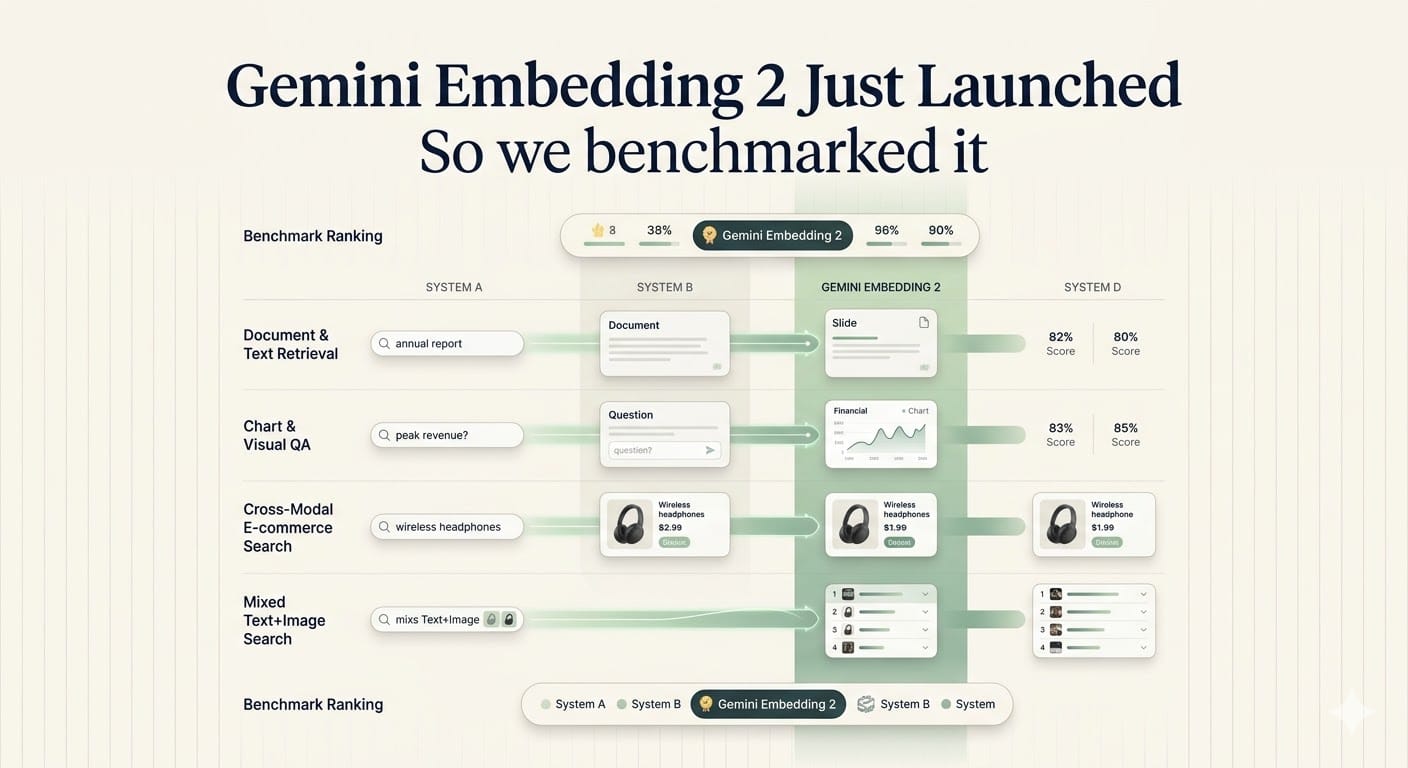
Gemini Embedding 2 just launched - so we benchmarked it
Google launched gemini-embedding-2-preview on 10 March 2026 as its first multimodal embedding model, with one shared embedding space for text, images, video, audio, and PDFs. Google specifically positions it for…
-
 Benchmarks · · 4 min read
The great AI gifting showdown: Which model should you trust for Christmas shopping?
It’s that time of year again. You’re out and about, the clock is ticking, and you still haven't found the perfect gift for your partner, your roommate, or that difficult-to-shop-for in-law. Naturally, many of us are…