Compare / Gemini 4 Argon vs Mistral Medium 3.5
Gemini 4 Argon vs Mistral Medium 3.5
Which is cheaper, which is more capable, and which does better at each kind of work, from 103 results on 7 sources that measured both models.


Of the 103 results both models have, the better value on each. Results whose reported ranges overlap are too close to call.
Results as of 14 October 2026 (catalogue release 2026-10-14-7d7cf32c3f6d). See also Google vs Mistral AI, every model from both labs.
Gemini 4 Argon or Mistral Medium 3.5? The short answer
Pick Gemini 4 Argon if quality matters most: it scores higher (Spring Prompt overall 75 against 16). Pick Mistral Medium 3.5 if cost matters more: it costs 27% less per product listing on CatalogBench.
- Spring Prompt overall: Gemini 4 Argon 75, Mistral Medium 3.5 16 (out of 100; how the score works).
- Mistral Medium 3.5 is cheaper to run: $0.008 against $0.011 per product listing on CatalogBench (27% less).
- Gemini 4 Argon scores higher on the Artificial Analysis Intelligence Index: 52.6 against 14.2.
- Gemini 4 Argon is newer: released 13 Oct 2026, against 28 Apr 2026 for Mistral Medium 3.5.
- On our own benchmarks, on the results both models have: Gemini 4 Argon does better for product listings, decks from an analysis, user surveys and marketing planning; Mistral Medium 3.5 for speed under pressure.
- On third-party benchmarks, on the results both models have: Gemini 4 Argon does better for agents and tool use, reasoning and knowledge, writing and sticking to the facts.
Head to head
Every fact side by side
| Gemini 4 Argon | Mistral Medium 3.5 | |
|---|---|---|
| Price per million tokens | $2.00 in · $10.00 out | $1.50 in · $7.50 out |
| Blended (3 in : 1 out) | $4.00 | $3.00 |
| Cheapest host, blended | – | $3.00 (Mistral) |
| Cost per product listing (CatalogBench) | $0.011 | $0.008 |
| Cached input, per million | – | $0.15 cached input |
| Intelligence Index | 52.6 | 14.2 |
| Spring Prompt overall | 75 | 16 |
| Output speed, tokens a second | – | 165 |
| Context window | 1,048,576 tokens | 262,144 tokens |
| Released | 13 Oct 2026 (newer) | 28 Apr 2026 |
| Weights | Closed | Closed |
| Developer based in | the US | France |
Prices are the developer's list price where we have read it, otherwise the typical host on OpenRouter; see every model's price. Intelligence and speed from Artificial Analysis.
Which is better for what
Each model's rank among the models on sale today, for each kind of work, from our own benchmarks and licensed sources. Further right is better; the better rank is in green.
Their slides, side by side
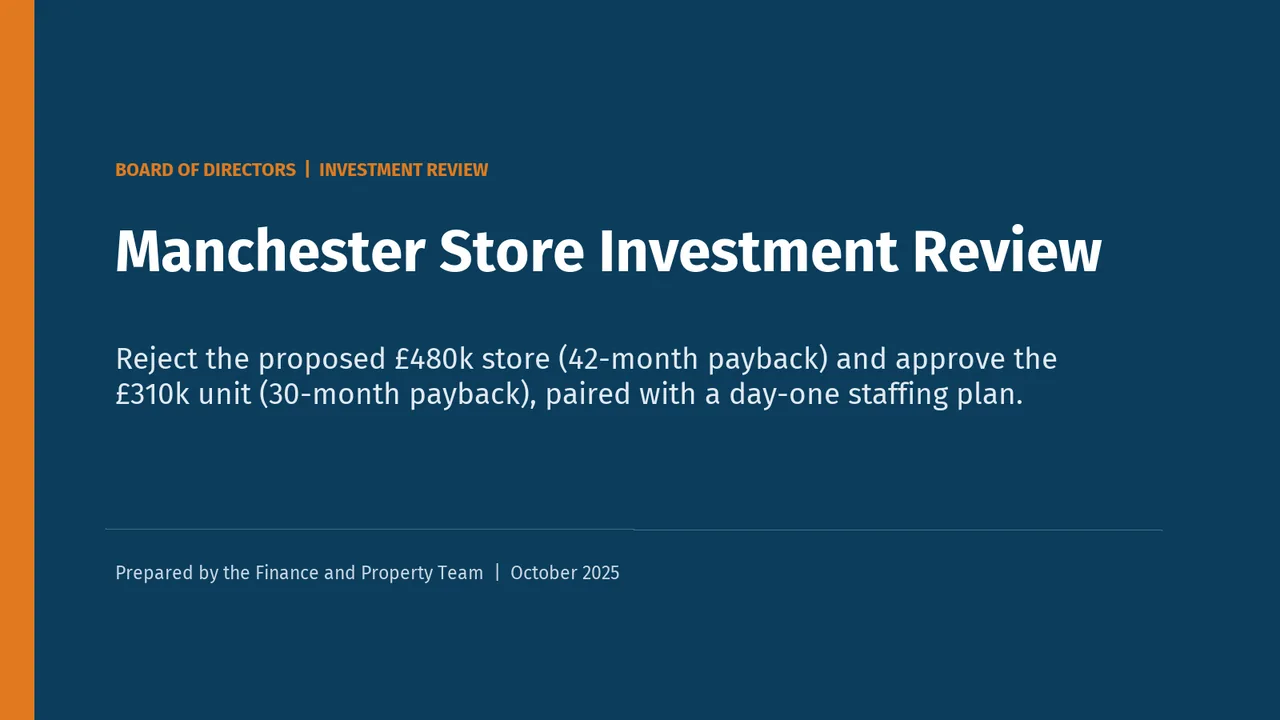
The same brief for both: Manchester store investment review for Hearthside Coffee, an invented company. First slide of each deck from DeckBench.

From our research
Every shared result
Each model's best result on every measure both have, grouped by benchmark, with the setting that produced it. Under each measure, every model that benchmark has measured is a grey tick, best to the right, so you can see where the two sit in the field. The headline measures of each benchmark come first; the rest are under "Show all". Green marks the better value; where a source reports ranges that overlap, neither is marked.
| Measure | Gemini 4 Argon | Mistral Medium 3.5 |
|---|---|---|
| BulletBench measured by Spring Prompt · 3 results | ||
| Cost per game · Blitz 3+2US dollars, lower is better 10 · 5 of 15 measured | $0.12 | $0.0261 |
| Cost per game · Bullet 60sUS dollars, lower is better 10 · 26 of 30 measured | $0.0036 | $0.0354no reasoning |
| Ladder Elo · Bullet 60sladder Elo, higher is better 26 · 8 of 30 measured | 147 | 572no reasoning |
| CatalogBench measured by Spring Prompt · 3 results | ||
| Cost per productUS dollars, lower is better 12 · 8 of 22 measured | $0.0109 | $0.0080 |
| Reliably publish-ready% of products, higher is better 5 · 18 of 22 measured | 60.7% | 17.9% |
| Reliably publish-ready · sales brief% of products, higher is better 9 · 11 of 22 measured | 17.9% | 10.7% |
| DeckBench measured by Spring Prompt · 3 results | ||
| Cost per deckUS dollars, lower is better 10 · 5 of 21 measured | $0.11 | $0.0448 |
| Deck ratingrating, higher is betterThe rating weighs each win by how strong the other deck was; the win rate counts wins against whichever decks a model happened to meet, so the two can disagree. 13 · 19 of 21 measured | 998 | 629 |
| Accurate decks% of tasks, higher is better 13 · 18 of 21 measured | 33.3% | 0.0% |
| ROASBench measured by Spring Prompt · 3 results | ||
| Overall scorescore out of 100, higher is better 8 · 21 of 21 measured | 47.0 | 15.2 |
| Audience scorescore out of 100, higher is better 8 · 21 of 21 measured | 65.5 | 28.5 |
| Business scorescore out of 100, higher is better 8 · 21 of 21 measured | 43.3 | 3.4 |
| SurveyBench measured by Spring Prompt · 3 results | ||
| Analysis ratingrating, higher is betterThe rating weighs each win by how strong the other analysis was; the win rate counts wins against whichever analyses a model happened to meet, so the two can disagree. 5 · 9 of 10 measured | 964 | 544 |
| Cost per taskUS dollars, lower is better 6 · 4 of 10 measured | $0.13 | $0.0730 |
| Analysis scorepoints of 100, higher is better 5 · 9 of 10 measured | 79.6 | 56.7 |
| Arena (formerly LMArena) reported by Arena (formerly LMArena) · 3 results | ||
| Overall · TextArena rating, higher is better 1 · 99 of 387 measured | 1,525high reasoning | 1,427 |
| Overall · Text factualityArena rating, higher is better 1 · 97 of 163 measured | 1,511high reasoning | 1,431 |
| Business, management and finance · TextArena rating, higher is better 1 · 98 of 380 measured | 1,522high reasoning | 1,430 |
| Artificial Analysis reported by Artificial Analysis · 3 results | ||
| Artificial Analysis Intelligence Indexindex score, higher is better 5 · 134 of 244 measured | 52.6high reasoning | 14.2 |
| Humanity's Last Exam% of questions, higher is better 3 · 132 of 243 measured | 57.1%high reasoning | 13.8% |
| Terminal-Bench 4.0% of tasks, higher is better 4 · 67 of 113 measured | 57.1%high reasoning | 0.0% |
Show all 103 results (82 more)
| Measure | Gemini 4 Argon | Mistral Medium 3.5 |
|---|---|---|
| BulletBench measured by Spring Prompt · 7 results | ||
| Games lost on time · Blitz 3+2% of games, lower is better 1 · 1 of 15 measured | 0.0% | 0.0% |
| Games lost on time · Bullet 60s% of games, lower is better 28 · 1 of 30 measured | 87.5% | 0.0%no reasoning |
| Invalid moves · Blitz 3+2% of moves, lower is better 1 · 12 of 15 measured | 0.0% | 0.4% |
| Invalid moves · Bullet 60s% of moves, lower is better 1 · 26 of 30 measured | 0.0% | 0.4%no reasoning |
| Ladder Elo · Blitz 3+2ladder Elo, higher is better 1 · 11 of 15 measured | 1,147 | 555 |
| Median move time · Blitz 3+2milliseconds, lower is better 5 · 1 of 15 measured | 1.9 s | 0.5 s |
| Median move time · Bullet 60smilliseconds, lower is better 28 · 5 of 30 measured | 2.9 s | 0.5 sno reasoning |
| CatalogBench measured by Spring Prompt · 28 results | ||
| Channel compliance% of products, higher is better 1 · 1 of 22 measured | 100.0% | 100.0% |
| Channel rules broken% of products, lower is better 1 · 1 of 22 measured | 0.0% | 0.0% |
| Channel rules broken · sales brief% of products, lower is better 1 · 17 of 22 measured | 0.0% | 1.2% |
| Claims to check% of products, lower is better 1 · 20 of 22 measured | 0.0% | 3.6% |
| Claims to check · sales brief% of products, lower is better 1 · 20 of 22 measured | 0.0% | 25.6% |
| Conflicts caught% of conflicts, higher is better 1 · 21 of 22 measured | 100.0% | 90.9% |
| Content quality% of checks, higher is better 4 · 21 of 22 measured | 98.2% | 94.1% |
| Content quality · sales brief% of checks, higher is better 4 · 19 of 22 measured | 98.4% | 94.1% |
| Decision accuracy% of decisions, higher is better 5 · 20 of 22 measured | 97.8% | 92.6% |
| Failed outputs% of products, lower is better 1 · 1 of 22 measured | 0.0% | 0.0% |
| Failed outputs · sales brief% of products, lower is better 1 · 1 of 22 measured | 0.0% | 0.0% |
| Field accuracy% of missing fields, higher is better 3 · 18 of 22 measured | 94.7% | 91.7% |
| Invented values% of filled values, lower is better 14 · 1 of 22 measured | 1.7% | 0.0% |
| Missing UK information% of products, lower is better 1 · 1 of 22 measured | 0.0% | 0.0% |
| Missing UK information · sales brief% of products, lower is better 1 · 1 of 22 measured | 0.0% | 0.0% |
| Not findable% of products, lower is better 3 · 21 of 22 measured | 2.4% | 14.3% |
| Not findable · sales brief% of products, lower is better 2 · 19 of 22 measured | 1.8% | 10.1% |
| Publish-ready listings% of products, higher is better 5 · 20 of 22 measured | 70.8% | 29.8% |
| Publish-ready listings · sales brief% of products, higher is better 8 · 14 of 22 measured | 35.1% | 17.3% |
| Time per productseconds, lower is better 3 · 2 of 22 measured | 7.30 | 4.90 |
| Unsupported claimsclaims per product, lower is better 6 · 20 of 22 measured | 0.42 | 1.74 |
| Unsupported claims% of products, lower is better 9 · 20 of 22 measured | 16.1% | 49.4% |
| Unsupported claims · sales briefclaims per product, lower is better 12 · 17 of 22 measured | 1.98 | 3.55 |
| Unsupported claims · sales brief% of products, lower is better 12 · 15 of 22 measured | 63.1% | 76.8% |
| Wrong attributes% of products, lower is better 6 · 20 of 22 measured | 15.5% | 31.0% |
| Wrong attributes · sales brief% of products, lower is better 7 · 21 of 22 measured | 15.5% | 36.3% |
| Wrong category or variant% of products, lower is better 4 · 22 of 22 measured | 1.8% | 11.3% |
| Wrong category or variant · sales brief% of products, lower is better 4 · 22 of 22 measured | 1.8% | 13.1% |
| DeckBench measured by Spring Prompt · 14 results | ||
| Caveat dropped% of tasks, lower is better 1 · 1 of 21 measured | 0.0% | 0.0% |
| Clean layout% of tasks, higher is better 13 · 6 of 21 measured | 33.3% | 66.7% |
| Design quality% of the maximum, higher is better 16 · 19 of 21 measured | 55.2% | 43.7% |
| Draft figure quoted% of tasks, lower is better 17 · 17 of 21 measured | 50.0% | 50.0% |
| Findings missing% of tasks, lower is better 1 · 1 of 21 measured | 0.0% | 0.0% |
| Head-to-head win rate% of comparisons, higher is betterThe rating weighs each win by how strong the other deck was; the win rate counts wins against whichever decks a model happened to meet, so the two can disagree. 13 · 19 of 21 measured | 57.0% | 24.4% |
| Layout defects% of tasks, lower is better 13 · 6 of 21 measured | 66.7% | 33.3% |
| Misleading metric used% of tasks, lower is better 1 · 1 of 21 measured | 0.0% | 0.0% |
| Presentable decks% of tasks, higher is better 12 · 12 of 21 measured | 0.0% | 0.0% |
| Recommendation late or wrong% of tasks, lower is better 1 · 15 of 21 measured | 0.0% | 50.0% |
| Slides needing work% of tasks, lower is better 15 · 10 of 21 measured | 66.7% | 50.0% |
| Time per deckseconds, lower is better 6 · 2 of 21 measured | 67.5 | 25.0 |
| Unsupported claims% of tasks, lower is better 11 · 15 of 21 measured | 16.7% | 33.3% |
| Unsupported numbers% of tasks, lower is better 1 · 1 of 21 measured | 0.0% | 0.0% |
| ROASBench measured by Spring Prompt · 6 results | ||
| Consistency scorescore out of 100, higher is better 5 · 20 of 21 measured | 34.7 | 8.7 |
| Contribution profitsimulated US dollars, higher is better 5 · 20 of 21 measured | $673,561 | −$159,882 |
| Cost of a runUS dollars, lower is better 11 · 7 of 21 measured | $0.24 | $0.15 |
| Months over budgetmonths of 12, lower is better 1 · 21 of 21 measured | 0 | 3 |
| Planning scorescore out of 100, higher is better 1 · 2 of 21 measured | 55.4 | 55.2 |
| Return on ad spendprofit per $1 spent, higher is better 8 · 20 of 21 measured | $0.55 | −$0.17 |
| SurveyBench measured by Spring Prompt · 17 results | ||
| Head-to-head win rate% of comparisons, higher is betterThe rating weighs each win by how strong the other analysis was; the win rate counts wins against whichever analyses a model happened to meet, so the two can disagree. 5 · 9 of 10 measured | 42.2% | 21.8% |
| Leading or double-barrelled questions% of tasks, lower is better 8 · 7 of 10 measured | 66.7% | 55.6% |
| Mistaken next steps% of tasks, lower is better 5 · 10 of 10 measured | 33.3% | 77.8% |
| Numbers right% of answers, higher is better 7 · 8 of 10 measured | 97.1% | 75.5% |
| Objectives unanswerable% of tasks, lower is better 1 · 6 of 10 measured | 0.0% | 11.1% |
| Precision ignored% of tasks, lower is better 4 · 8 of 10 measured | 11.1% | 100.0% |
| Research scorepoints of 100, higher is better 5 · 9 of 10 measured | 83.3 | 64.2 |
| Sound research% of tasks, higher is better 5 · 5 of 10 measured | 0.0% | 0.0% |
| Stakeholder's view presumed% of tasks, lower is better 4 · 9 of 10 measured | 11.1% | 33.3% |
| Survey plan scorepoints of 100, higher is better 4 · 9 of 10 measured | 91.8 | 81.5 |
| Survey structure% of tasks, lower is better 1 · 3 of 10 measured | 0.0% | 11.1% |
| Time per taskseconds, lower is better 3 · 2 of 10 measured | 74.4 | 47.5 |
| Traps handled% of traps, higher is better 5 · 9 of 10 measured | 84.1% | 59.4% |
| Traps missed% of tasks, lower is better 5 · 8 of 10 measured | 77.8% | 100.0% |
| Unsupported findings% of tasks, lower is better 7 · 8 of 10 measured | 88.9% | 100.0% |
| Wrong numbers% of tasks, lower is better 7 · 8 of 10 measured | 33.3% | 100.0% |
| Wrong recommendation% of tasks, lower is better 3 · 7 of 10 measured | 11.1% | 44.4% |
| Arena (formerly LMArena) reported by Arena (formerly LMArena) · 8 results | ||
| Confirmed task success · AgentIPS effect estimate, higher is better 3 · 45 of 48 measured | 0.15high reasoning, arena agent | -0.15arena agent |
| Creative writing · TextArena rating, higher is better 1 · 95 of 385 measured | 1,519high reasoning | 1,400 |
| Expert prompts · TextArena rating, higher is better 7 · 119 of 338 measured | 1,539high reasoning | 1,435 |
| Instruction following · TextArena rating, higher is better 1 · 92 of 387 measured | 1,528high reasoning | 1,422 |
| Praise over complaint · AgentIPS effect estimate, higher is better 4 · 45 of 48 measured | 0.28high reasoning, arena agent | -0.18arena agent |
| Steerability · AgentIPS effect estimate, higher is better 1 · 39 of 48 measured | 0.13high reasoning, arena agent | -0.06arena agent |
| Tool grounding · AgentIPS effect estimate, higher is better 29 · 46 of 48 measured | 0.00high reasoning, arena agent | -0.02arena agent |
| Writing, literature and language · TextArena rating, higher is better 1 · 100 of 386 measured | 1,522high reasoning | 1,405 |
| Artificial Analysis reported by Artificial Analysis · 2 results | ||
| Long-context reasoning (AA-LCR)% of questions, higher is better 44 · 114 of 234 measured | 79.7%high reasoning | 69.3% |
| SciCode% of problems, higher is better 3 · 78 of 114 measured | 61.8%high reasoning | 40.2% |
Compare them with other models
- Google vs Mistral AIEvery model from both labs, best against best
- Gemini 4 Argon vs Claude Opus 5.5Most intelligent at $3–10 per million tokens
- Gemini 4 Argon vs Claude Sonnet 5.5Cheapest with similar intelligence
- Gemini 4 Argon vs GPT-6 AstraJust above overall
- Gemini 4 Argon vs Muse WonderJust below overall
- Mistral Medium 3.5 vs Claude Opus 5.5Most intelligent at $3–10 per million tokens
- Mistral Medium 3.5 vs Mistral Large 4Most intelligent from the EU
Quick answers
Is Gemini 4 Argon better than Mistral Medium 3.5?
Pick Gemini 4 Argon if quality matters most: it scores higher (Spring Prompt overall 75 against 16). Pick Mistral Medium 3.5 if cost matters more: it costs 27% less per product listing on CatalogBench.
Which is cheaper, Gemini 4 Argon or Mistral Medium 3.5?
Mistral Medium 3.5 is cheaper to run: $0.008 against $0.011 per product listing on CatalogBench (27% less).
Which is better for product listings, Gemini 4 Argon or Mistral Medium 3.5?
Gemini 4 Argon ranks 7 of 22 models on sale for turning a sparse product feed and photos into listings that can go live, against 16 for Mistral Medium 3.5.
Which is better for decks from an analysis, Gemini 4 Argon or Mistral Medium 3.5?
Gemini 4 Argon ranks 13 of 21 models on sale for turning a finished analysis into a deck you could present as it is, against 19 for Mistral Medium 3.5.
Which is better for user surveys, Gemini 4 Argon or Mistral Medium 3.5?
Gemini 4 Argon ranks 5 of 10 models on sale for planning a user survey and reading its results without being misled, against 9 for Mistral Medium 3.5.
Which is better for marketing planning, Gemini 4 Argon or Mistral Medium 3.5?
Gemini 4 Argon ranks 8 of 21 models on sale for planning a year of ad spend without overspending, against 21 for Mistral Medium 3.5.
Which is better for agents and tool use, Gemini 4 Argon or Mistral Medium 3.5?
Gemini 4 Argon ranks 3 of 166 models on sale for multi-step tasks with tools: support desks, coding agents, function calls, against 96 for Mistral Medium 3.5.
Which has the bigger context window, Gemini 4 Argon or Mistral Medium 3.5?
Gemini 4 Argon: 1,048,576 tokens, against 262,144 for Mistral Medium 3.5.
Run Gemini 4 Argon and Mistral Medium 3.5 on your own prompt
Benchmarks aren't your data. Try both side by side in the playground, with the cost of every answer.