Each model runs at its provider's default reasoning setting. Some providers think at length by default and others barely at all, so this is what you get without tuning.
Real outputs
The same product given to two models, from the published runs. Supplier copy often makes claims the product cannot back up; a publish-ready listing leaves them out.
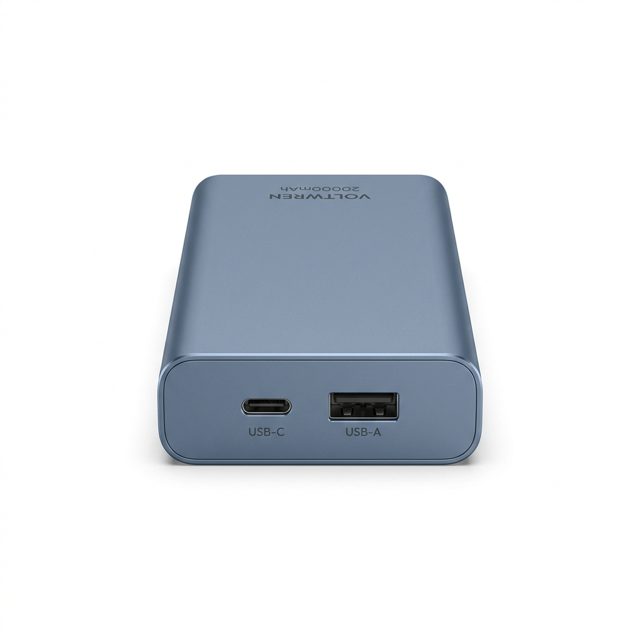
Voltwren 20,000 mAh Power Bank
Electronics · Factual brief
Supplier copy “Voltwren 20,000 mAh power bank with 65W fast charging for laptops, phones and tablets. Airline approved. USB-C and USB-A ports.”
GPT-6 Astra✓ Publish-ready
Voltwren 20,000 mAh Power Bank, Blue-Grey, USB-C and USB-A
20,000 mAh capacity, with the capacity printed on the casing.
One USB-C port and one USB-A port.
Blue-grey casing with a smooth finish.
Rounded rectangular body with labelled ports on one end.
The Voltwren power bank has a 20,000 mAh capacity and a blue-grey casing with rounded corners and a smooth finish. One USB-C port and one USB-A port sit side by side on the end panel, with their connector types labelled underneath. The broad upper surface carries the Voltwren name and capacity marking.
Gemini 3.1 Pro Preview✗ Not publish-ready
Voltwren 20,000 mAh Power Bank, 65W, USB-C & USB-A, Blue
20,000 mAh battery capacity
65W fast charging supported
Equipped with one USB-C and one USB-A port
Suitable for charging laptops, phones, and tablets
Keep your devices powered on the go with the Voltwren 20,000 mAh Power Bank. Designed for versatility and convenience, it supports 65W fast charging and is suitable for a range of devices including laptops, mobile phones, and tablets. The power bank is equipped with both a USB-C and a USB-A port, allowing you to charge multiple devices efficiently.
Unsupported claims
“65W”
“Airline approved for travel”
and 11 more flagged by the judge
Pennard 5 m Tape Measure
Tools · Factual brief
Supplier copy “Pennard 5m / 16ft tape measure with a magnetic hook, auto-lock and a shockproof rubber case. Trade quality.”
GPT-6 Astra✓ Publish-ready
Pennard 5 m / 16 ft Tape Measure - Yellow
5 m / 16 ft measuring length, marked on the case
Yellow measuring blade with metric and imperial graduations
Yellow case with a rounded top and flat base
Black ridged slider on the side of the case
The Pennard tape measure has a yellow case labelled 5 m / 16 ft and a yellow blade with metric and imperial graduations. The case has a rounded top, a flat base and a black ridged side slider. A hooked end is attached to the blade with visible rivets. The case surface shows scuffs, scratches and dark marks.
Claude Haiku 4.5✗ Not publish-ready
Pennard 5m Tape Measure with Magnetic Hook and Auto-Lock
5 metre (16 feet) measuring capacity with metric and imperial markings
Magnetic hook for hands-free holding on metal surfaces
Auto-lock function to hold tape at desired length
Shockproof rubber case for durability and protection
The Pennard 5m tape measure combines practical features for DIY and trade use. The 5-metre length with dual metric and imperial markings suits general measuring tasks around the home and workshop. A magnetic hook allows the tape to grip metal surfaces for one-handed operation, while the auto-lock mechanism holds the tape in place at your chosen length.
Unsupported claims
“Magnetic Hook”
“Auto-Lock”
and 11 more flagged by the judge
Brimdrift Insulated Water Bottle
Home and kitchen · Sales brief
Supplier copy “The Brimdrift bottle keeps drinks ice cold for 24 hours and hot for 12. BPA-free, leakproof and dishwasher safe. 750 ml of double-walled stainless steel.”
GPT-6 Astra✓ Publish-ready
Brimdrift Insulated Water Bottle 750 ml Terracotta Orange Stainless Steel
750 ml capacity keeps a generous drink close at hand.
Insulated stainless steel water bottle for everyday hydration.
Terracotta orange finish with a matching cylindrical cap.
Tall, rounded body with curved shoulders and understated Brimdrift branding.
Keep everyday hydration close at hand with the Brimdrift insulated water bottle. Its 750 ml capacity gives you a generous drink to take along, while the stainless steel construction and warm terracotta orange finish pair practicality with understated style. The tall cylindrical body has rounded shoulders and a matching cap, with a slim black band beneath it.
Gemini 3.1 Pro Preview✗ Not publish-ready
Brimdrift Insulated Stainless Steel Water Bottle, 750 ml, Terracotta
750 ml capacity provides ample hydration for daily activities or outdoor adventures.
Constructed from robust, double-walled stainless steel for long-lasting everyday use.
Designed to keep your beverages ice cold for up to 24 hours and hot for 12 hours.
Features a secure, leakproof lid to prevent accidental spills in your bag or backpack.
Ensure you stay hydrated wherever your day takes you with the Brimdrift Insulated Water Bottle. This generous 750 ml flask is expertly crafted from durable, double-walled stainless steel, offering a reliable way to transport your favourite hot or cold beverages.
Unsupported claims
“Keeps beverages ice cold for up to 24 hours and hot for 12 hours”
and 15 more flagged by the judge
More from the results
Publish-ready rate against cost
Cost to enrich 10,000 products at the run date's prices, on a log scale. Up and to the left is better.
Why listings fail: factual brief
Share of products failing each check, averaged over three runs. A listing can fail several at once; any one stops it going live.
Model
No usable output
Unsupported claims
Wrong attributes
Not findable
Wrong category
Channel rules
UK information
GPT-6 AstraOpenAI
0.0%
4.2%
17.3%
6.0%
1.8%
0.0%
0.0%
GPT-6.1 SolOpenAI
0.0%
3.6%
16.7%
4.8%
1.8%
0.0%
0.0%
GPT-6 SolOpenAI
0.0%
7.1%
14.3%
7.7%
3.6%
0.0%
0.0%
GPT-6 LunaOpenAI
0.0%
12.5%
18.4%
10.1%
1.8%
0.0%
0.0%
Grok 4.7xAI
0.0%
20.2%
15.5%
5.4%
2.4%
0.0%
0.0%
Claude Opus 5.5Anthropic
0.0%
30.9%
15.5%
3.0%
1.8%
0.0%
0.0%
Muse Spark 1.3Meta
0.0%
23.8%
16.7%
6.0%
4.2%
0.0%
0.0%
DeepSeek V4.1 FlashDeepSeek
0.0%
19.6%
20.2%
3.6%
3.0%
3.0%
0.0%
Gemini 3.1 Pro PreviewGoogle
0.0%
45.8%
14.9%
7.7%
1.8%
3.0%
0.0%
Claude Sonnet 5.5Anthropic
0.0%
51.8%
19.1%
1.2%
3.0%
1.2%
0.0%
Kimi K3Moonshot AI
0.0%
33.9%
24.4%
4.2%
3.0%
0.6%
0.0%
Claude Fable 5.1Anthropic
0.0%
61.3%
11.9%
1.8%
2.4%
0.0%
0.0%
Gemini 3.8 FlashGoogle
0.0%
60.1%
15.5%
8.3%
3.6%
1.2%
0.0%
Qwen3.8 Max (0902)Alibaba
3.6%
55.4%
21.4%
3.6%
1.8%
1.2%
0.0%
Mistral Medium 3.5Mistral
0.0%
75.6%
30.9%
14.3%
11.3%
4.2%
0.0%
Gemini 3.5 Flash LiteGoogle
0.0%
67.3%
34.5%
20.2%
9.5%
1.8%
0.0%
Claude Haiku 4.5Anthropic
0.0%
94.0%
48.2%
8.9%
7.7%
23.2%
0.0%
GLM 5V TurboZ.ai
32.1%
64.9%
13.1%
5.4%
1.2%
3.0%
0.0%
Why listings fail: sales brief
The same checks when the model is asked for copy that sells.
Model
No usable output
Unsupported claims
Wrong attributes
Not findable
Wrong category
Channel rules
UK information
GPT-6 AstraOpenAI
0.0%
5.4%
20.2%
5.4%
1.8%
0.0%
0.0%
GPT-6.1 SolOpenAI
0.0%
6.5%
19.1%
5.4%
1.8%
0.0%
0.0%
GPT-6 SolOpenAI
0.0%
11.9%
13.7%
7.1%
3.0%
0.6%
0.0%
GPT-6 LunaOpenAI
0.0%
16.7%
19.1%
10.1%
0.0%
0.0%
0.0%
Grok 4.7xAI
0.0%
54.2%
15.5%
4.2%
2.4%
0.0%
0.0%
Claude Opus 5.5Anthropic
0.0%
95.2%
15.5%
1.8%
1.8%
0.6%
0.0%
Muse Spark 1.3Meta
0.0%
84.5%
14.3%
5.4%
3.6%
0.0%
0.0%
DeepSeek V4.1 FlashDeepSeek
0.6%
70.2%
20.2%
3.6%
2.4%
1.8%
0.0%
Gemini 3.1 Pro PreviewGoogle
0.0%
95.8%
16.1%
6.0%
1.8%
12.5%
0.0%
Claude Sonnet 5.5Anthropic
0.0%
86.3%
20.8%
0.6%
3.0%
3.0%
0.0%
Kimi K3Moonshot AI
0.6%
97.0%
20.8%
3.0%
4.2%
0.6%
0.0%
Claude Fable 5.1Anthropic
0.0%
99.4%
14.9%
1.8%
1.8%
0.6%
0.0%
Gemini 3.8 FlashGoogle
0.0%
97.0%
11.9%
8.9%
3.0%
3.0%
0.0%
Qwen3.8 Max (0902)Alibaba
3.6%
95.2%
19.6%
1.8%
2.4%
4.8%
0.0%
Mistral Medium 3.5Mistral
0.0%
100.0%
36.3%
10.1%
13.1%
13.1%
0.0%
Gemini 3.5 Flash LiteGoogle
0.0%
97.6%
35.1%
21.4%
10.7%
6.5%
0.0%
Claude Haiku 4.5Anthropic
0.0%
99.4%
51.2%
6.5%
6.5%
39.3%
0.0%
GLM 5V TurboZ.ai
82.1%
17.9%
3.6%
1.8%
1.2%
1.8%
0.0%
How CatalogBench works
1
The feed row
A sparse supplier row: title, price, a few attributes, and the supplier's marketing text, which may not be true.
2
The photos
One to three product photos, including labels with the real facts: volume, strength, origin, ingredients.
3
The listing
The model fills missing attributes and writes the title, highlights, description, alt text, search keywords and category.
4
The checks
Rules check attributes and channel limits, a judge answers yes/no questions against the evidence, and a search test checks shoppers can find it.
5
Publish-ready?
Only if every blocking check passes. Three runs; the headline counts products that passed in all three.
The task
Retailers increasingly let AI write their product listings from a supplier feed and a few photos. The risky part is not the prose: it is attributes that are guessed, claims copied from the supplier that the product cannot back up, and listings that no shopper will find.
Each of the 56 public products is invented, with generated photos that carry real-looking labels. Every feed row hides traps: missing attributes only the photos can answer, a supplier claim the label contradicts, and tempting claims such as “award-winning” with no evidence at all.
Two briefs
Factual
Write an accurate listing from the evidence.
Sales
Write copy that sells. The same facts, the same checks: persuasive is fine, unsupported is not.
What stops a listing going live
Unsupported claims
Anything the feed or photos do not support, judged on the UK CAP Code line between puffery and a factual claim.
Wrong attributes
A wrong, missing or invented value, or a feed/photo conflict that was not flagged.
UK information
Statements UK rules require, such as age warnings.
Channel rules
Lengths, formats and banned terms.
Category
The wrong category, or the wrong variant in the title.
Findability
Two shopper searches per product against near-identical rival listings; the listing must win on what the shopper asked for.
Reading the results
Content quality (coverage, visual detail, key facts in the title) is scored separately and does not stop a listing going live. Costs are the prices charged on the run date and are shown per 10,000 products, a typical catalogue refresh.
What it measures
Attributes read from the images, not guessed
Supplier claims checked, not repeated
Required UK product information included
Listings that shoppers can find in search
What it does not measure
Conversion or sales impact
Real product photography (a real-photo slice is planned)
Writing style beyond the listed checks
Method
Rule-based checks first; judged checks are yes or no
The judge was checked for bias against Gemini and Claude judges
Private products are held back so the set can be refreshed
Checking the judge
The judge is an OpenAI model, and OpenAI models lead this table, so we checked it for bias. Gemini 3.1 Pro and Claude Opus 5.5 judged the same outputs from five models on a calibration set. All three judges put the models in the same order under both briefs. Each was slightly gentler on its own family's marketing copy: the top GPT models moved by 4 to 8 points between judges under the marketing brief, without changing places.
Failures
Failures count against a model: a product with no usable output is a failed listing. They are listed here so you can see why.
Qwen3.8 Max (0902): reply cut off at the token limit: 6 of 168 attempts.
GLM 5V Turbo: invalid JSON (raw line breaks inside text): 50 of 168 attempts; invalid JSON: 4 of 168 attempts.