
Compare / Muse Wonder vs Kimi K3.1 Pro
Muse Wonder vs Kimi K3.1 Pro
Which is cheaper, which is more capable, and which does better at each kind of work, from 84 results on 6 sources that measured both models.


Of the 84 results both models have, the better value on each. Results whose reported ranges overlap are too close to call.
Results as of 10 November 2026 (catalogue release 2026-11-10-8342a7178929). See also Meta vs Moonshot AI, every model from both labs.
Muse Wonder or Kimi K3.1 Pro? The short answer
They score about the same, so pick Muse Wonder: it costs 21% less per product listing on CatalogBench.
- Spring Prompt overall: Muse Wonder 69, Kimi K3.1 Pro 68 (out of 100; how the score works).
- Muse Wonder is cheaper to run: $0.036 against $0.045 per product listing on CatalogBench (21% less).
- Kimi K3.1 Pro is newer: released 23 Oct 2026, against 12 Oct 2026 for Muse Wonder.
- On our own benchmarks, on the results both models have: Muse Wonder does better for user surveys; Kimi K3.1 Pro for marketing planning.
- On third-party benchmarks, on the results both models have: Kimi K3.1 Pro does better for agents and tool use and reasoning and knowledge.
Head to head
Every fact side by side
| Muse Wonder | Kimi K3.1 Pro | |
|---|---|---|
| Price per million tokens | $4.00 in · $20.00 out | $1.75 in · $10.00 out |
| Blended (3 in : 1 out) | $8.00 | $3.81 |
| Cheapest host, blended | – | $2.38 (Relace, FP4) |
| Cost per product listing (CatalogBench) | $0.036 | $0.045 |
| Cached input, per million | $0.20 cached input | – |
| Intelligence Index | 52.4 | – |
| Spring Prompt overall | 69 | 68 |
| Output speed, tokens a second | 153 | – |
| Context window | 1,048,576 tokens | 1,048,576 tokens |
| Released | 12 Oct 2026 | 23 Oct 2026 (newer) |
| Weights | Closed | Open |
| Developer based in | the US | China |
Prices are the developer's list price where we have read it, otherwise the typical host on OpenRouter; see every model's price. Intelligence and speed from Artificial Analysis.
Which is better for what
Each model's rank among the models on sale today, for each kind of work, from our own benchmarks and licensed sources. Further right is better; the better rank is in green.
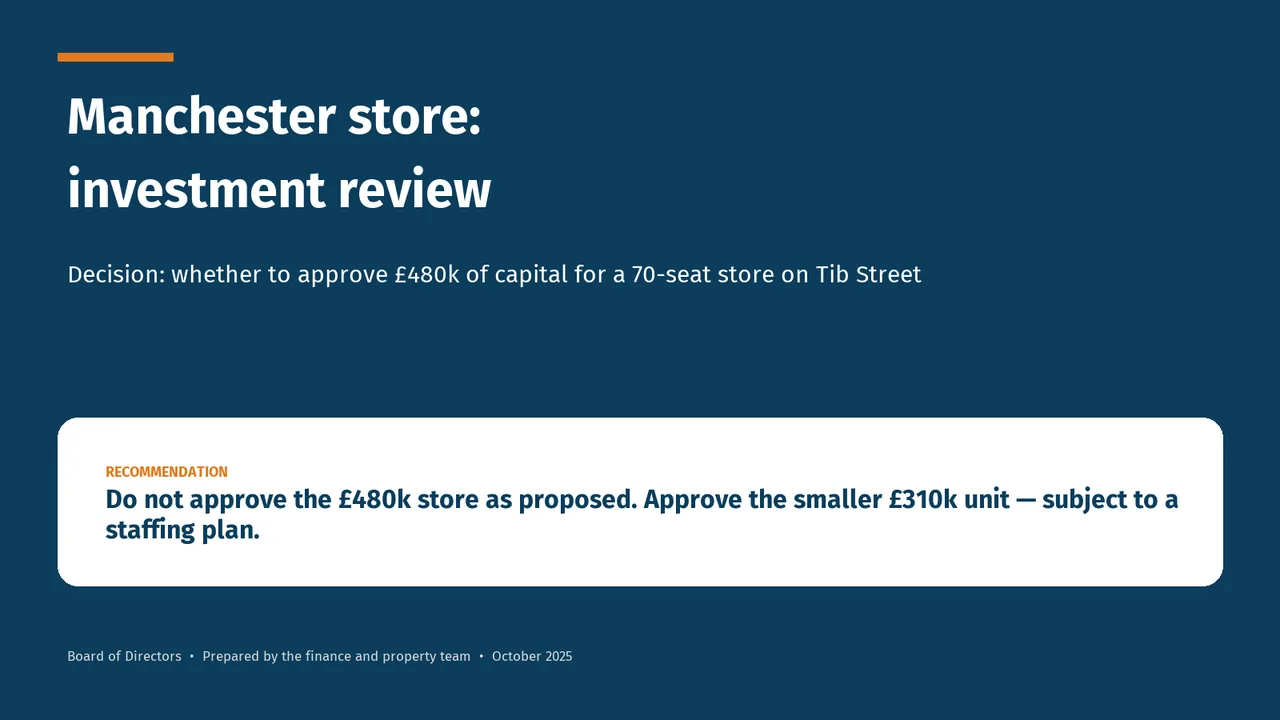
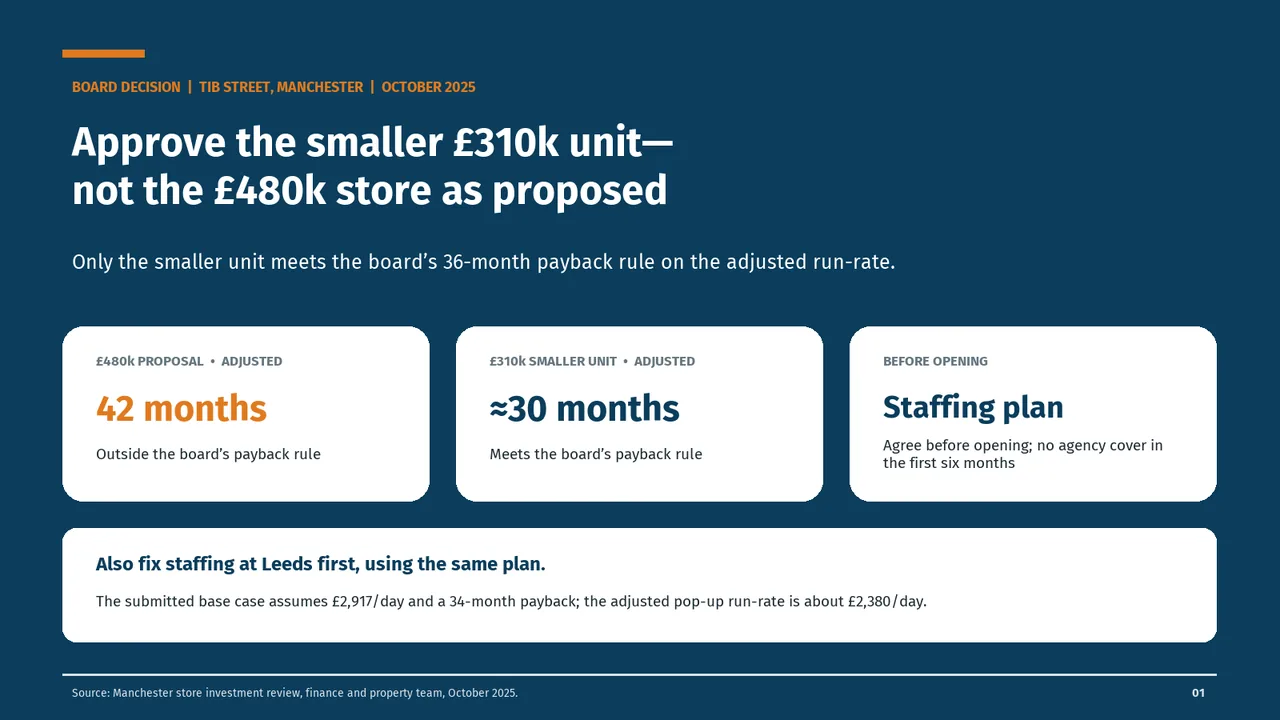
Their slides, side by side
The same brief for both: Manchester store investment review for Hearthside Coffee, an invented company. First slide of each deck from DeckBench.
From our research
- AI Checkpoint: Argon matches Opus, until it sells 16 Oct 2026
- Claude Opus 5.5 vs Muse Wonder Full: Eight Crafts, and Opus Still Wins Most 13 Oct 2026
- Muse Wonder review: good analysis, work that still needs checking 13 Oct 2026
- Claude Fable 5.2 review: first on our survey and ad budget tests, and one of the dearest models to run 10 Nov 2026
Every shared result
Each model's best result on every measure both have, grouped by benchmark, with the setting that produced it. Under each measure, every model that benchmark has measured is a grey tick, best to the right, so you can see where the two sit in the field. The headline measures of each benchmark come first; the rest are under "Show all". Green marks the better value; where a source reports ranges that overlap, neither is marked.
| Measure | Muse Wonder | Kimi K3.1 Pro |
|---|---|---|
| BulletBench measured by Spring Prompt · 3 results | ||
| Cost per game · Bullet 60sUS dollars, lower is better 36 · 28 of 38 measured | $0.0663minimal reasoning | $0.0175low reasoning |
| Ladder Elo · Bullet 60sladder Elo, higher is better 21 · 31 of 38 measured | 409minimal reasoning | 147low reasoning |
| Games lost on time · Bullet 60s% of games, lower is better 25 · 34 of 38 measured | 58.3%minimal reasoning | 87.5%low reasoning |
| CatalogBench measured by Spring Prompt · 3 results | ||
| Cost per productUS dollars, lower is better 24 · 27 of 30 measured | $0.0361 | $0.0454 |
| Channel compliance% of products, higher is better 22 · 1 of 30 measured | 99.4% | 100.0% |
| Channel rules broken% of products, lower is better 17 · 1 of 30 measured | 0.6% | 0.0% |
| DeckBench measured by Spring Prompt · 3 results | ||
| Cost per deckUS dollars, lower is better 22 · 27 of 30 measured | $0.18 | $0.54 |
| Deck ratingrating, higher is betterThe rating weighs each win by how strong the other deck was; the win rate counts wins against whichever decks a model happened to meet, so the two can disagree. 13 · 12 of 30 measured | 1,232 | 1,238 |
| Accurate decks% of tasks, higher is better 1 · 9 of 30 measured | 100.0% | 66.7% |
| ROASBench measured by Spring Prompt · 3 results | ||
| Overall scorescore out of 100, higher is better 19 · 4 of 30 measured | 38.9 | 55.1 |
| Audience scorescore out of 100, higher is better 21 · 8 of 30 measured | 54.7 | 67.6 |
| Business scorescore out of 100, higher is better 19 · 3 of 30 measured | 34.5 | 58.2 |
| SurveyBench measured by Spring Prompt · 3 results | ||
| Analysis ratingrating, higher is betterThe rating weighs each win by how strong the other analysis was; the win rate counts wins against whichever analyses a model happened to meet, so the two can disagree. 2 · 19 of 21 measured | 1,471 | 608 |
| Cost per taskUS dollars, lower is better 18 · 20 of 21 measured | $0.35 | $0.74 |
| Analysis scorepoints of 100, higher is better 3 · 20 of 21 measured | 96.2 | 14.5 |
| Artificial Analysis reported by Artificial Analysis · 3 results | ||
| Humanity's Last Exam% of questions, higher is better 10 · 9 of 250 measured | 50.1%max reasoning | 52.5% |
| Terminal-Bench 4.0% of tasks, higher is better 9 · 1 of 120 measured | 52.0%max reasoning | 67.2% |
| Long-context reasoning (AA-LCR)% of questions, higher is better 36 · 3 of 241 measured | 80.7%max reasoning | 86.3% |
Show all 84 results (66 more)
| Measure | Muse Wonder | Kimi K3.1 Pro |
|---|---|---|
| BulletBench measured by Spring Prompt · 2 results | ||
| Invalid moves · Bullet 60s% of moves, lower is better 1 · 1 of 38 measured | 0.0%minimal reasoning | 0.0%low reasoning |
| Median move time · Bullet 60smilliseconds, lower is better 28 · 38 of 38 measured | 1.9 sminimal reasoning | 5.0 slow reasoning |
| CatalogBench measured by Spring Prompt · 26 results | ||
| Channel rules broken · sales brief% of products, lower is better 1 · 1 of 30 measured | 0.0% | 0.0% |
| Claims to check% of products, lower is better 1 · 1 of 28 measured | 0.0% | 0.0% |
| Claims to check · sales brief% of products, lower is better 1 · 1 of 28 measured | 0.0% | 0.0% |
| Conflicts caught% of conflicts, higher is better 1 · 1 of 30 measured | 100.0% | 100.0% |
| Content quality% of checks, higher is better 5 · 1 of 30 measured | 98.3% | 98.9% |
| Content quality · sales brief% of checks, higher is better 4 · 24 of 30 measured | 98.5% | 95.3% |
| Decision accuracy% of decisions, higher is better 5 · 1 of 30 measured | 98.3% | 98.9% |
| Failed outputs% of products, lower is better 1 · 1 of 30 measured | 0.0% | 0.0% |
| Failed outputs · sales brief% of products, lower is better 1 · 28 of 30 measured | 0.0% | 3.6% |
| Field accuracy% of missing fields, higher is better 2 · 3 of 30 measured | 96.1% | 95.6% |
| Invented values% of filled values, lower is better 11 · 21 of 30 measured | 1.4% | 2.1% |
| Missing UK information% of products, lower is better 1 · 1 of 30 measured | 0.0% | 0.0% |
| Missing UK information · sales brief% of products, lower is better 1 · 1 of 30 measured | 0.0% | 0.0% |
| Not findable% of products, lower is better 9 · 17 of 30 measured | 3.6% | 5.4% |
| Not findable · sales brief% of products, lower is better 14 · 14 of 30 measured | 3.6% | 3.6% |
| Publish-ready listings% of products, higher is better 5 · 2 of 30 measured | 75.0% | 78.6% |
| Publish-ready listings · sales brief% of products, higher is better 7 · 2 of 30 measured | 67.3% | 75.0% |
| Time per productseconds, lower is better 11 · 30 of 30 measured | 10.2 | 114 |
| Unsupported claimsclaims per product, lower is better 6 · 1 of 30 measured | 0.21 | 0.00 |
| Unsupported claims% of products, lower is better 7 · 1 of 30 measured | 7.1% | 0.0% |
| Unsupported claims · sales brief% of products, lower is better 8 · 1 of 30 measured | 17.9% | 1.8% |
| Unsupported claims · sales briefclaims per product, lower is better 7 · 5 of 30 measured | 0.36 | 0.21 |
| Wrong attributes% of products, lower is better 3 · 13 of 30 measured | 13.1% | 16.1% |
| Wrong attributes · sales brief% of products, lower is better 5 · 5 of 30 measured | 14.3% | 14.3% |
| Wrong category or variant% of products, lower is better 17 · 5 of 30 measured | 2.4% | 1.8% |
| Wrong category or variant · sales brief% of products, lower is better 16 · 27 of 30 measured | 2.4% | 5.4% |
| DeckBench measured by Spring Prompt · 14 results | ||
| Caveat dropped% of tasks, lower is better 1 · 14 of 30 measured | 0.0% | 16.7% |
| Clean layout% of tasks, higher is better 23 · 27 of 30 measured | 16.7% | 0.0% |
| Design quality% of the maximum, higher is better 13 · 3 of 30 measured | 67.1% | 83.9% |
| Draft figure quoted% of tasks, lower is better 1 · 1 of 30 measured | 0.0% | 0.0% |
| Findings missing% of tasks, lower is better 1 · 28 of 30 measured | 0.0% | 33.3% |
| Head-to-head win rate% of comparisons, higher is betterThe rating weighs each win by how strong the other deck was; the win rate counts wins against whichever decks a model happened to meet, so the two can disagree. 15 · 10 of 30 measured | 60.5% | 71.1% |
| Layout defects% of tasks, lower is better 23 · 27 of 30 measured | 83.3% | 100.0% |
| Misleading metric used% of tasks, lower is better 1 · 1 of 30 measured | 0.0% | 0.0% |
| Presentable decks% of tasks, higher is better 12 · 14 of 30 measured | 16.7% | 0.0% |
| Recommendation late or wrong% of tasks, lower is better 1 · 1 of 30 measured | 0.0% | 0.0% |
| Slides needing work% of tasks, lower is better 22 · 1 of 30 measured | 66.7% | 0.0% |
| Time per deckseconds, lower is better 3 · 30 of 30 measured | 28.6 | 1,288 |
| Unsupported claims% of tasks, lower is better 1 · 1 of 30 measured | 0.0% | 0.0% |
| Unsupported numbers% of tasks, lower is better 1 · 1 of 30 measured | 0.0% | 0.0% |
| ROASBench measured by Spring Prompt · 6 results | ||
| Consistency scorescore out of 100, higher is better 19 · 6 of 30 measured | 25.9 | 36.3 |
| Contribution profitsimulated US dollars, higher is better 20 · 4 of 30 measured | $489,176 | $858,023 |
| Cost of a runUS dollars, lower is better 23 · 28 of 30 measured | $0.57 | $1.60 |
| Months over budgetmonths of 12, lower is better 1 · 1 of 30 measured | 0 | 0 |
| Planning scorescore out of 100, higher is better 6 · 4 of 30 measured | 55.0 | 55.0 |
| Return on ad spendprofit per $1 spent, higher is better 20 · 2 of 30 measured | $0.41 | $0.72 |
| SurveyBench measured by Spring Prompt · 17 results | ||
| Head-to-head win rate% of comparisons, higher is betterThe rating weighs each win by how strong the other analysis was; the win rate counts wins against whichever analyses a model happened to meet, so the two can disagree. 4 · 15 of 21 measured | 73.2% | 36.1% |
| Leading or double-barrelled questions% of tasks, lower is better 12 · 7 of 21 measured | 44.4% | 22.2% |
| Mistaken next steps% of tasks, lower is better 1 · 19 of 21 measured | 0.0% | 77.8% |
| Numbers right% of answers, higher is better 1 · 1 of 21 measured | 100.0% | 100.0% |
| Objectives unanswerable% of tasks, lower is better 12 · 1 of 21 measured | 11.1% | 0.0% |
| Precision ignored% of tasks, lower is better 13 · 1 of 21 measured | 22.2% | 0.0% |
| Research scorepoints of 100, higher is better 4 · 20 of 21 measured | 93.6 | 39.2 |
| Sound research% of tasks, higher is better 4 · 12 of 21 measured | 33.3% | 0.0% |
| Stakeholder's view presumed% of tasks, lower is better 9 · 1 of 21 measured | 11.1% | 0.0% |
| Survey plan scorepoints of 100, higher is better 14 · 3 of 21 measured | 87.8 | 97.0 |
| Survey structure% of tasks, lower is better 16 · 3 of 21 measured | 33.3% | 11.1% |
| Time per taskseconds, lower is better 5 · 21 of 21 measured | 83.2 | 1,956 |
| Traps handled% of traps, higher is better 1 · 10 of 21 measured | 100.0% | 93.3% |
| Traps missed% of tasks, lower is better 1 · 13 of 21 measured | 0.0% | 88.9% |
| Unsupported findings% of tasks, lower is better 3 · 12 of 21 measured | 11.1% | 77.8% |
| Wrong numbers% of tasks, lower is better 1 · 17 of 21 measured | 0.0% | 77.8% |
| Wrong recommendation% of tasks, lower is better 1 · 21 of 21 measured | 0.0% | 100.0% |
| Artificial Analysis reported by Artificial Analysis · 1 result | ||
| SciCode% of problems, higher is better 8 · 7 of 121 measured | 60.3%max reasoning | 60.8% |
Compare them with other models
- Meta vs Moonshot AIEvery model from both labs, best against best
- Muse Wonder vs Claude Opus 5.5Most intelligent at $3–10 per million tokens
- Muse Wonder vs Claude Sonnet 5.5Cheapest with similar intelligence
- Muse Wonder vs Claude Fable 5.2Highest-scoring overall available today
- Kimi K3.1 Pro vs Claude Opus 5.5Highest-scoring overall at $3–10 per million tokens
- Kimi K3.1 Pro vs Claude Fable 5.2Highest-scoring overall available today
- Kimi K3.1 Pro vs GPT-6 SolJust below overall
Quick answers
Is Muse Wonder better than Kimi K3.1 Pro?
They score about the same, so pick Muse Wonder: it costs 21% less per product listing on CatalogBench.
Which is cheaper, Muse Wonder or Kimi K3.1 Pro?
Muse Wonder is cheaper to run: $0.036 against $0.045 per product listing on CatalogBench (21% less).
Which is better for decks from an analysis, Muse Wonder or Kimi K3.1 Pro?
Kimi K3.1 Pro ranks 12 of 29 models on sale for turning a finished analysis into a deck you could present as it is, against 13 for Muse Wonder.
Which is better for user surveys, Muse Wonder or Kimi K3.1 Pro?
Muse Wonder ranks 2 of 20 models on sale for planning a user survey and reading its results without being misled, against 18 for Kimi K3.1 Pro.
Which is better for marketing planning, Muse Wonder or Kimi K3.1 Pro?
Kimi K3.1 Pro ranks 4 of 29 models on sale for planning a year of ad spend without overspending, against 19 for Muse Wonder.
Which is better for agents and tool use, Muse Wonder or Kimi K3.1 Pro?
Kimi K3.1 Pro ranks 1 of 159 models on sale for multi-step tasks with tools: support desks, coding agents, function calls, against 11 for Muse Wonder.
Which is better for reasoning and knowledge, Muse Wonder or Kimi K3.1 Pro?
Muse Wonder ranks 8 of 187 models on sale for hard questions across science, maths and general knowledge, against 9 for Kimi K3.1 Pro.
Run Muse Wonder and Kimi K3.1 Pro on your own prompt.
Benchmarks aren't your task. Test both side by side on your prompt, with every answer checked against your rules and the cost of each one.