
Compare / Claude Opus 5.5 vs Kimi K3.1 Pro
Claude Opus 5.5 vs Kimi K3.1 Pro
Which is cheaper, which is more capable, and which does better at each kind of work, from 75 results on 4 sources that measured both models.


Of the 75 results both models have, the better value on each. Results whose reported ranges overlap are too close to call.
Results as of 4 November 2026 (catalogue release 2026-11-04-56cfea57899a). See also Anthropic vs Moonshot AI, every model from both labs.
Claude Opus 5.5 or Kimi K3.1 Pro? The short answer
Pick Claude Opus 5.5: it scores higher (Spring Prompt overall 83 against 56) at about the same price.
- Spring Prompt overall: Claude Opus 5.5 83, Kimi K3.1 Pro 56 (out of 100; how the score works).
- They cost about the same to run: $0.040 and $0.045 per product listing on CatalogBench.
- On our own benchmarks, on the results both models have: Claude Opus 5.5 does better for user surveys; Kimi K3.1 Pro for marketing planning.
Head to head
Every fact side by side
| Claude Opus 5.5 | Kimi K3.1 Pro | |
|---|---|---|
| Price per million tokens | $4.00 in · $20.00 out | $2.00 in · $10.00 out |
| Blended (3 in : 1 out) | $8.00 | $4.00 |
| Cheapest host, blended | $8.00 (Amazon Bedrock) | $4.00 (Moonshot AI, MXFP4) |
| Cost per product listing (CatalogBench) | $0.040 | $0.045 |
| Cached input, per million | $0.20 cached input | – |
| Intelligence Index | 57.6 | – |
| Spring Prompt overall | 83 | 56 |
| Output speed, tokens a second | 96 | – |
| Context window | 1,000,000 tokens | 1,048,576 tokens |
| Released | 22 Sep 2026 | – |
| Weights | Closed | Open |
| Developer based in | the US | China |
Prices are the developer's list price where we have read it, otherwise the typical host on OpenRouter; see every model's price. Intelligence and speed from Artificial Analysis.
Which is better for what
Each model's rank among the models on sale today, for each kind of work, from our own benchmarks and licensed sources. Further right is better; the better rank is in green.
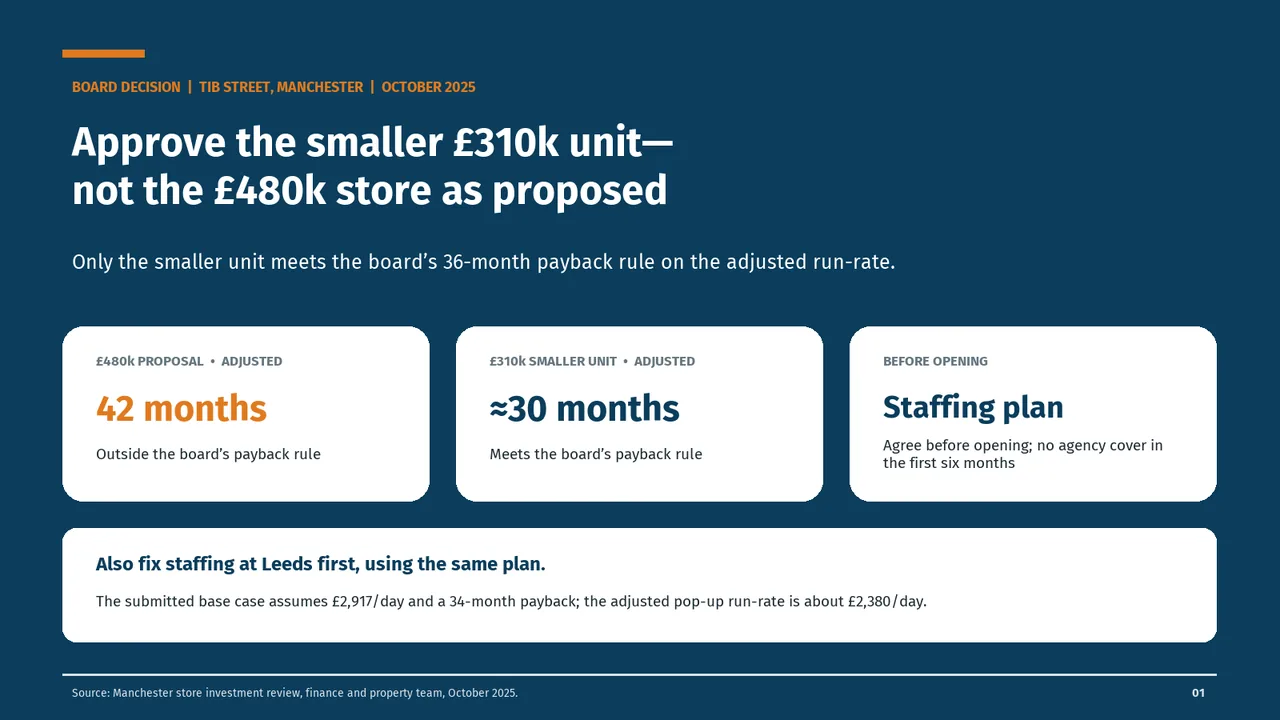
Their slides, side by side
The same brief for both: Manchester store investment review for Hearthside Coffee, an invented company. First slide of each deck from DeckBench.

From our research
- AI Checkpoint: Argon matches Opus, until it sells 16 Oct 2026
- Gemini 4 Argon review: Opus-level product data at a quarter of the cost, until you ask it to sell 14 Oct 2026
- Claude Opus 5.5 vs Muse Wonder Full: Eight Crafts, and Opus Still Wins Most 13 Oct 2026
- Muse Wonder review: good analysis, work that still needs checking 13 Oct 2026
Every shared result
Each model's best result on every measure both have, grouped by benchmark, with the setting that produced it. Under each measure, every model that benchmark has measured is a grey tick, best to the right, so you can see where the two sit in the field. The headline measures of each benchmark come first; the rest are under "Show all". Green marks the better value; where a source reports ranges that overlap, neither is marked.
| Measure | Claude Opus 5.5 | Kimi K3.1 Pro |
|---|---|---|
| CatalogBench measured by Spring Prompt · 3 results | ||
| Cost per productUS dollars, lower is better 23 · 24 of 26 measured | $0.0400 | $0.0454 |
| Channel compliance% of products, higher is better 1 · 1 of 26 measured | 100.0% | 100.0% |
| Channel rules broken% of products, lower is better 1 · 1 of 26 measured | 0.0% | 0.0% |
| DeckBench measured by Spring Prompt · 3 results | ||
| Cost per deckUS dollars, lower is better 22 · 24 of 26 measured | $0.26 | $0.54 |
| Deck ratingrating, higher is betterThe rating weighs each win by how strong the other deck was; the win rate counts wins against whichever decks a model happened to meet, so the two can disagree. 4 · 11 of 26 measured | 1,406 | 1,259 |
| Accurate decks% of tasks, higher is better 5 · 7 of 26 measured | 83.3% | 66.7% |
| ROASBench measured by Spring Prompt · 3 results | ||
| Overall scorescore out of 100, higher is better 7 · 3 of 26 measured | 51.7 | 55.1 |
| Audience scorescore out of 100, higher is better 5 · 7 of 26 measured | 67.7 | 67.6 |
| Business scorescore out of 100, higher is better 7 · 2 of 26 measured | 52.3 | 58.2 |
| SurveyBench measured by Spring Prompt · 3 results | ||
| Analysis ratingrating, higher is betterThe rating weighs each win by how strong the other analysis was; the win rate counts wins against whichever analyses a model happened to meet, so the two can disagree. 1 · 13 of 15 measured | 1,507 | 596 |
| Cost per taskUS dollars, lower is better 13 · 14 of 14 measured | $0.46 | $0.74 |
| Analysis scorepoints of 100, higher is better 3 · 14 of 15 measured | 95.3 | 14.5 |
Show all 75 results (63 more)
| Measure | Claude Opus 5.5 | Kimi K3.1 Pro |
|---|---|---|
| CatalogBench measured by Spring Prompt · 26 results | ||
| Channel rules broken · sales brief% of products, lower is better 14 · 1 of 26 measured | 0.6% | 0.0% |
| Claims to check% of products, lower is better 1 · 1 of 26 measured | 0.0% | 0.0% |
| Claims to check · sales brief% of products, lower is better 1 · 1 of 26 measured | 0.0% | 0.0% |
| Conflicts caught% of conflicts, higher is better 1 · 1 of 26 measured | 100.0% | 100.0% |
| Content quality% of checks, higher is better 6 · 1 of 26 measured | 97.9% | 98.9% |
| Content quality · sales brief% of checks, higher is better 9 · 20 of 26 measured | 97.8% | 95.3% |
| Decision accuracy% of decisions, higher is better 8 · 1 of 26 measured | 97.7% | 98.9% |
| Failed outputs% of products, lower is better 1 · 1 of 26 measured | 0.0% | 0.0% |
| Failed outputs · sales brief% of products, lower is better 1 · 24 of 26 measured | 0.0% | 3.6% |
| Field accuracy% of missing fields, higher is better 20 · 2 of 26 measured | 92.2% | 95.6% |
| Invented values% of filled values, lower is better 4 · 18 of 26 measured | 0.5% | 2.1% |
| Missing UK information% of products, lower is better 1 · 1 of 26 measured | 0.0% | 0.0% |
| Missing UK information · sales brief% of products, lower is better 1 · 1 of 26 measured | 0.0% | 0.0% |
| Not findable% of products, lower is better 4 · 12 of 26 measured | 3.0% | 5.4% |
| Not findable · sales brief% of products, lower is better 2 · 10 of 26 measured | 1.8% | 3.6% |
| Publish-ready listings% of products, higher is better 7 · 1 of 26 measured | 70.8% | 78.6% |
| Publish-ready listings · sales brief% of products, higher is better 12 · 2 of 26 measured | 34.5% | 75.0% |
| Time per productseconds, lower is better 15 · 26 of 26 measured | 16.9 | 114 |
| Unsupported claims% of products, lower is better 14 · 1 of 26 measured | 17.3% | 0.0% |
| Unsupported claimsclaims per product, lower is better 11 · 1 of 26 measured | 0.45 | 0.00 |
| Unsupported claims · sales brief% of products, lower is better 14 · 1 of 26 measured | 60.1% | 1.8% |
| Unsupported claims · sales briefclaims per product, lower is better 13 · 5 of 26 measured | 1.66 | 0.21 |
| Wrong attributes% of products, lower is better 7 · 11 of 26 measured | 15.5% | 16.1% |
| Wrong attributes · sales brief% of products, lower is better 9 · 4 of 26 measured | 15.5% | 14.3% |
| Wrong category or variant% of products, lower is better 5 · 5 of 26 measured | 1.8% | 1.8% |
| Wrong category or variant · sales brief% of products, lower is better 5 · 23 of 26 measured | 1.8% | 5.4% |
| DeckBench measured by Spring Prompt · 14 results | ||
| Caveat dropped% of tasks, lower is better 13 · 13 of 26 measured | 16.7% | 16.7% |
| Clean layout% of tasks, higher is better 3 · 24 of 26 measured | 83.3% | 0.0% |
| Design quality% of the maximum, higher is better 9 · 3 of 26 measured | 72.0% | 83.9% |
| Draft figure quoted% of tasks, lower is better 1 · 1 of 26 measured | 0.0% | 0.0% |
| Findings missing% of tasks, lower is better 1 · 24 of 26 measured | 0.0% | 33.3% |
| Head-to-head win rate% of comparisons, higher is betterThe rating weighs each win by how strong the other deck was; the win rate counts wins against whichever decks a model happened to meet, so the two can disagree. 3 · 9 of 26 measured | 86.6% | 75.6% |
| Layout defects% of tasks, lower is better 3 · 24 of 26 measured | 16.7% | 100.0% |
| Misleading metric used% of tasks, lower is better 1 · 1 of 26 measured | 0.0% | 0.0% |
| Presentable decks% of tasks, higher is better 6 · 13 of 26 measured | 33.3% | 0.0% |
| Recommendation late or wrong% of tasks, lower is better 1 · 1 of 26 measured | 0.0% | 0.0% |
| Slides needing work% of tasks, lower is better 18 · 1 of 26 measured | 66.7% | 0.0% |
| Time per deckseconds, lower is better 13 · 26 of 26 measured | 98.5 | 1,288 |
| Unsupported claims% of tasks, lower is better 1 · 1 of 26 measured | 0.0% | 0.0% |
| Unsupported numbers% of tasks, lower is better 1 · 1 of 26 measured | 0.0% | 0.0% |
| ROASBench measured by Spring Prompt · 6 results | ||
| Consistency scorescore out of 100, higher is better 9 · 5 of 26 measured | 33.8 | 36.3 |
| Contribution profitsimulated US dollars, higher is better 2 · 3 of 26 measured | $911,566 | $858,023 |
| Cost of a runUS dollars, lower is better 23 · 25 of 26 measured | $1.06 | $1.60 |
| Months over budgetmonths of 12, lower is better 1 · 1 of 26 measured | 0 | 0 |
| Planning scorescore out of 100, higher is better 18 · 4 of 26 measured | 54.7 | 55.0 |
| Return on ad spendprofit per $1 spent, higher is better 4 · 1 of 26 measured | $0.69 | $0.72 |
| SurveyBench measured by Spring Prompt · 17 results | ||
| Head-to-head win rate% of comparisons, higher is betterThe rating weighs each win by how strong the other analysis was; the win rate counts wins against whichever analyses a model happened to meet, so the two can disagree. 1 · 9 of 15 measured | 84.0% | 35.5% |
| Leading or double-barrelled questions% of tasks, lower is better 1 · 5 of 15 measured | 0.0% | 22.2% |
| Mistaken next steps% of tasks, lower is better 1 · 13 of 15 measured | 0.0% | 77.8% |
| Numbers right% of answers, higher is better 1 · 1 of 15 measured | 100.0% | 100.0% |
| Objectives unanswerable% of tasks, lower is better 1 · 1 of 15 measured | 0.0% | 0.0% |
| Precision ignored% of tasks, lower is better 1 · 1 of 15 measured | 0.0% | 0.0% |
| Research scorepoints of 100, higher is better 2 · 14 of 15 measured | 96.1 | 39.2 |
| Sound research% of tasks, higher is better 2 · 7 of 15 measured | 55.6% | 0.0% |
| Stakeholder's view presumed% of tasks, lower is better 1 · 1 of 15 measured | 0.0% | 0.0% |
| Survey plan scorepoints of 100, higher is better 1 · 3 of 15 measured | 97.8 | 97.0 |
| Survey structure% of tasks, lower is better 3 · 3 of 15 measured | 11.1% | 11.1% |
| Time per taskseconds, lower is better 10 · 14 of 14 measured | 180 | 1,956 |
| Traps handled% of traps, higher is better 2 · 6 of 15 measured | 95.7% | 93.3% |
| Traps missed% of tasks, lower is better 3 · 8 of 15 measured | 33.3% | 88.9% |
| Unsupported findings% of tasks, lower is better 4 · 8 of 15 measured | 22.2% | 77.8% |
| Wrong numbers% of tasks, lower is better 1 · 11 of 15 measured | 0.0% | 77.8% |
| Wrong recommendation% of tasks, lower is better 1 · 14 of 15 measured | 0.0% | 100.0% |
Compare them with other models
Quick answers
Is Claude Opus 5.5 better than Kimi K3.1 Pro?
Pick Claude Opus 5.5: it scores higher (Spring Prompt overall 83 against 56) at about the same price.
Which is cheaper, Claude Opus 5.5 or Kimi K3.1 Pro?
They cost about the same to run: $0.040 and $0.045 per product listing on CatalogBench.
Which is better for decks from an analysis, Claude Opus 5.5 or Kimi K3.1 Pro?
Claude Opus 5.5 ranks 4 of 26 models on sale for turning a finished analysis into a deck you could present as it is, against 11 for Kimi K3.1 Pro.
Which is better for user surveys, Claude Opus 5.5 or Kimi K3.1 Pro?
Claude Opus 5.5 ranks 1 of 15 models on sale for planning a user survey and reading its results without being misled, against 13 for Kimi K3.1 Pro.
Which is better for marketing planning, Claude Opus 5.5 or Kimi K3.1 Pro?
Kimi K3.1 Pro ranks 3 of 26 models on sale for planning a year of ad spend without overspending, against 7 for Claude Opus 5.5.
Which is better for speed under pressure, Claude Opus 5.5 or Kimi K3.1 Pro?
Kimi K3.1 Pro ranks 22 of 30 models on sale for good decisions against a real clock (fast chess), against 30 for Claude Opus 5.5.
Which has the bigger context window, Claude Opus 5.5 or Kimi K3.1 Pro?
Kimi K3.1 Pro: 1,048,576 tokens, against 1,000,000 for Claude Opus 5.5.
Run Claude Opus 5.5 and Kimi K3.1 Pro on your own prompt
Benchmarks aren't your data. Try both side by side in the playground, with the cost of every answer.