Research
Findings and field notes.
What our benchmarks found, how we run them, and notes on building AI products you can trust.
-
 Model launches · · 8 min read
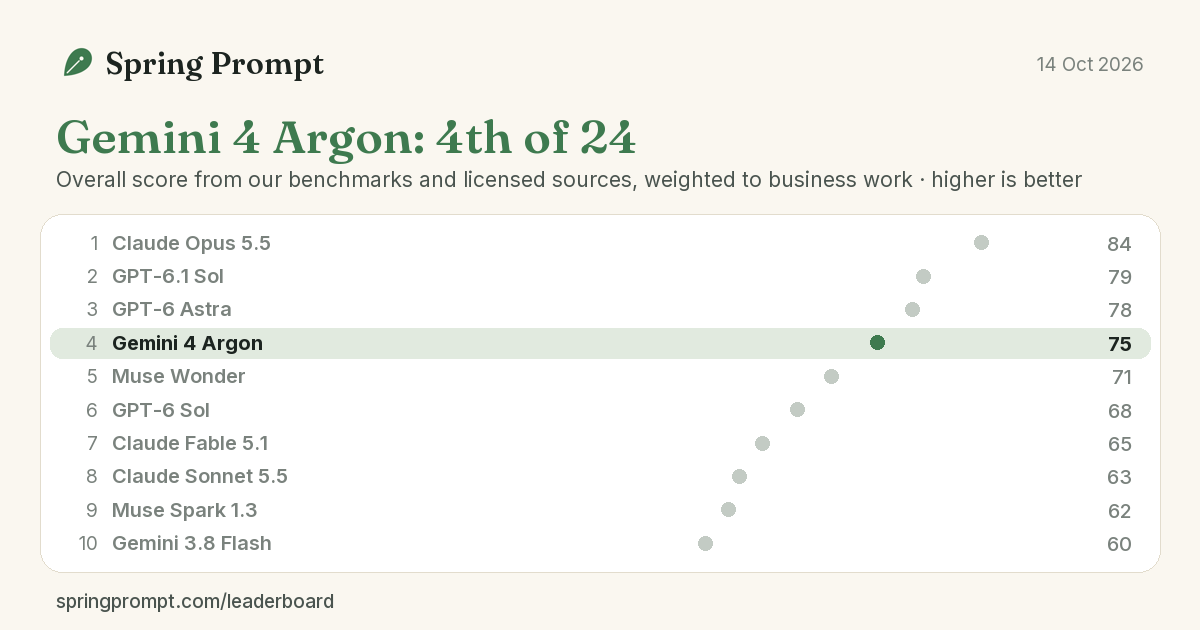
Gemini 4 argon review: Opus-level product data at a quarter of the cost, until you ask it to sell
We ran Gemini 4 Argon through six benchmarks on launch day. It matched Claude Opus 5.5 on product data at a quarter of the cost, then added five times as many unsupported claims when asked to sell.
-
 Model launches · · 7 min read
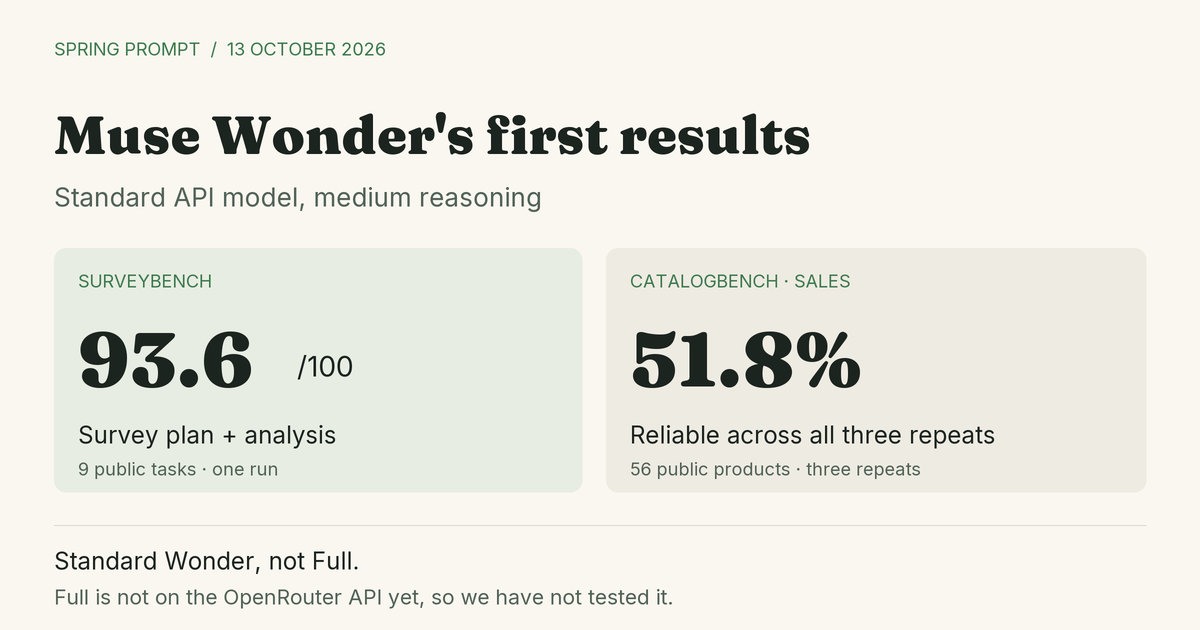
Muse wonder review: Good analysis, work that still needs checking
We tested standard Muse Wonder on six evaluations. Survey analysis was strong; product copy, slide layout and decisions against a clock still needed work. Full is outside this API comparison.
-
 Model launches · · 8 min read
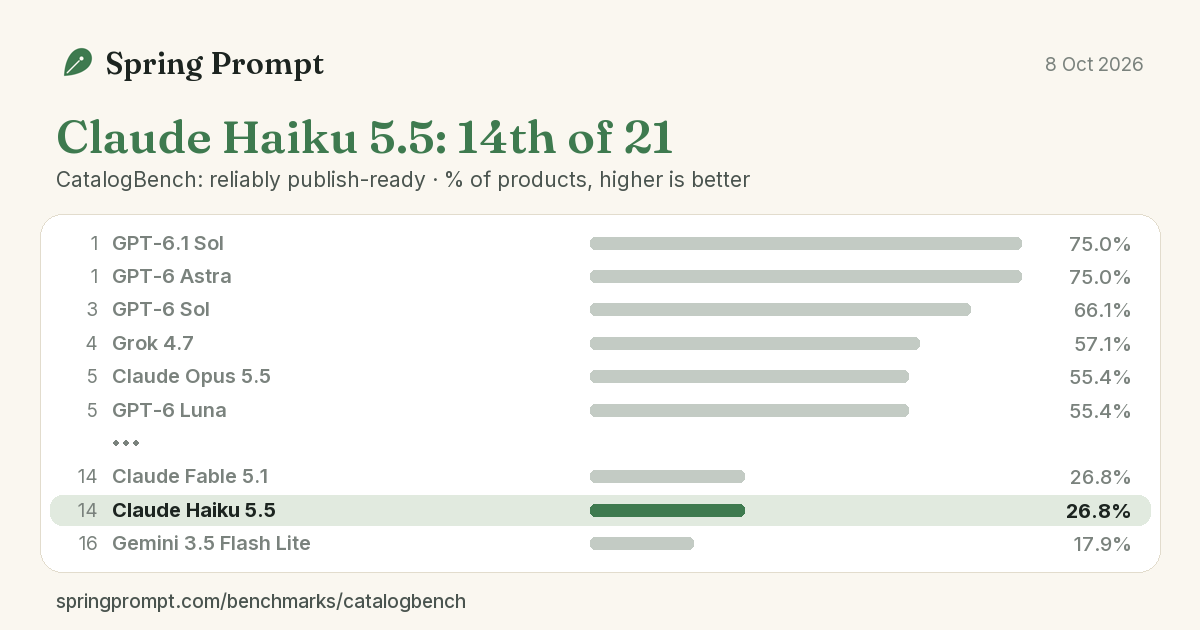
Claude Haiku 5.5 is far better than Haiku 4.5 at a tenth of the price. GPT-6 Luna still beats it at business work
We ran Claude Haiku 5.5 through our business benchmarks and 18 playground tests on launch day. It is a big step up from Haiku 4.5 and very cheap, but GPT-6 Luna, at the same price, beat it on listings, decks and ad planning.