Output tokens per deck:
3 results · tokens, lower is better. Choose a model to highlight it.Clear highlight
- 1 DeepSeek-V4.1-Flash-1017DeepSeek 21,019
- 2 Mercury 3Inception 32,448
- 3 MiniMax M3.1 FlashMiniMax 45,141

Benchmarks / DeckBench
Given a finished analysis, which models make a deck a manager could present as it is: true to the numbers, telling the right story, and well designed?
Which AI model makes the best business presentation? Compare the results below, then inspect and download the slide images, read the judges' findings and compare models' decks. DeckBench tests underlying models on the same business briefs; presentation apps add their own templates and editing tools.
Last updated 19 Oct 2026
3 results · tokens, lower is better. Choose a model to highlight it.Clear highlight
What one deck cost at the run date's prices, on a log scale. Up and to the left is better.
Named: the six best and the best for the moneyOther models (hover for names)Best score at each cost
Cheapest first: each model here beats every cheaper one on score.
| # | Model | Output tokens per deck tokens, lower is better | Deck rating rating | Presentable decks % of tasks | Accurate decks % of tasks | Design quality % of the maximum | Cost per deck US dollars |
|---|---|---|---|---|---|---|---|
| 1 | DeepSeek-V4.1-Flash-1017DeepSeek |
21,019
|
1,145 | 0.0% 0 of 6 | 33.3% 2 of 6 | 68.5% | $0.0255 |
| 2 | Mercury 3Inception |
32,448
|
812 | 0.0% 0 of 6 | 0.0% 0 of 6 | 58.5% | $0.0116 |
| 3 | MiniMax M3.1 FlashMiniMax |
45,141
|
1,090 | 0.0% 0 of 6 | 50.0% 3 of 6 | 46.2% | $0 |
Swipe the table sideways for more columns.
Ranks follow the score as shown, so equal numbers share a rank. Each model runs at its provider's default reasoning setting, one deck per task. The rating comes from head-to-head comparisons, so it keeps separating models even when several make presentable decks; ranges are 95% intervals from resampling the comparisons.
Every model's deck for every public task, as rendered from the slides it returned. Open a deck to see each slide, the judges' rating and what stopped it being presentable.
 GPT-6 Astra
✓ Presentable
 GPT-6 Sol
✗ 1 issue
 GPT-6.1 Sol
✓ Presentable
 Claude Opus 5.5
✓ Presentable
 Claude Sonnet 5.5
✓ Presentable
 Claude Fable 5.1
✗ 3 issues
 GPT-6 Luna
✗ 1 issue
 Grok 4.7
✓ Presentable
 Muse Wonder
✗ 2 issues
 Kimi K3
✗ 5 issues
 Claude Haiku 5.5
✗ 2 issues
 DeepSeek V4.1 Flash 1017
✗ 1 issue
 Qwen3.8 Max (0902)
✗ 2 issues
 minimax-m3.1-flash:free
✗ 5 issues
 Gemini 4 Argon
✗ 2 issues
 Muse Spark 1.3
✗ 2 issues
 Gemini 3.8 Flash
✗ 2 issues
No usable deck
Mercury 3
✗ No deck
 Gemini 3.1 Pro Preview
✗ 2 issues
 Claude Haiku 4.5
✗ 2 issues
 Gemini 3.5 Flash Lite
✗ 4 issues
 Mistral Medium 3.5
✗ 1 issue
 Mistral Large 4
✗ 3 issues
 DeepSeek V4 Pro 0423
✗ 2 issues
No usable deck
GLM 5.3
✗ No deck
 GPT-6 Astra
✓ Presentable
 GPT-6 Sol
✓ Presentable
 GPT-6.1 Sol
✗ 2 issues
 Claude Opus 5.5
✗ 1 issue
 Claude Sonnet 5.5
✗ 1 issue
 Claude Fable 5.1
✓ Presentable
 GPT-6 Luna
✗ 1 issue
 Grok 4.7
✗ 1 issue
 Muse Wonder
✗ 2 issues
 Kimi K3
✗ 1 issue
No usable deck
Claude Haiku 5.5
✗ No deck
 DeepSeek V4.1 Flash 1017
✗ 2 issues
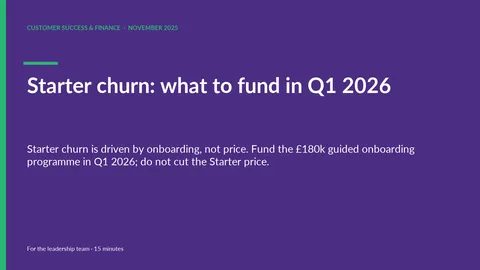 Qwen3.8 Max (0902)
✗ 3 issues
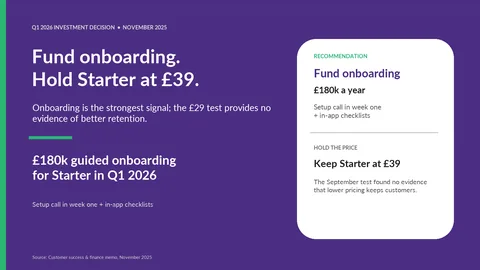 minimax-m3.1-flash:free
✗ 1 issue
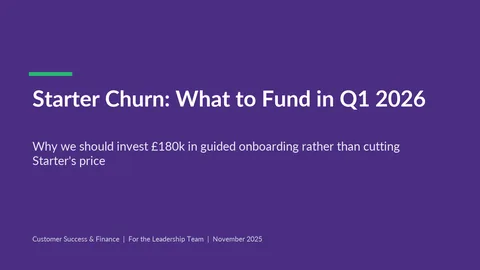 Gemini 4 Argon
✗ 3 issues
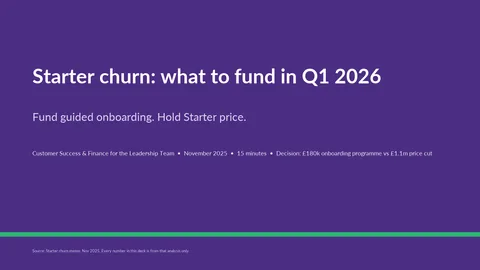 Muse Spark 1.3
✗ 2 issues
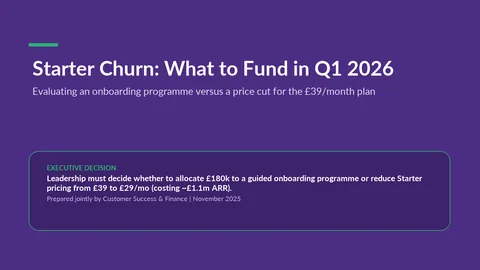 Gemini 3.8 Flash
✗ 2 issues
 Mercury 3
✗ 1 issue
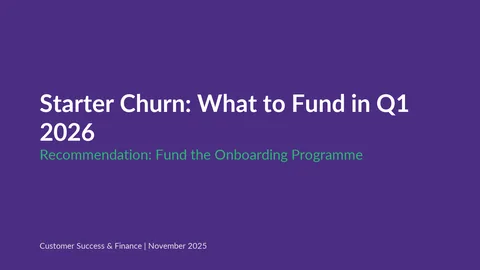 Gemini 3.1 Pro Preview
✗ 1 issue
 Claude Haiku 4.5
✗ 3 issues
 Gemini 3.5 Flash Lite
✗ 3 issues
 Mistral Medium 3.5
✗ 1 issue
 Mistral Large 4
✗ 5 issues
 DeepSeek V4 Pro 0423
✗ 4 issues
No usable deck
GLM 5.3
✗ No deck
 GPT-6 Astra
✓ Presentable
 GPT-6 Sol
✗ 1 issue
 GPT-6.1 Sol
✗ 1 issue
 Claude Opus 5.5
✗ 1 issue
 Claude Sonnet 5.5
✓ Presentable
 Claude Fable 5.1
✗ 3 issues
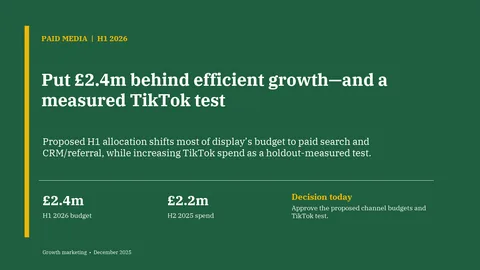 GPT-6 Luna
✗ 1 issue
 Grok 4.7
✓ Presentable
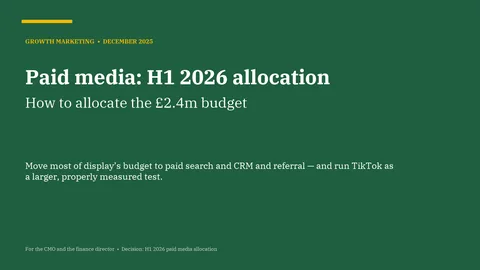 Muse Wonder
✗ 2 issues
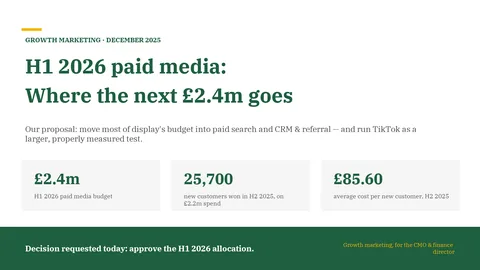 Kimi K3
✗ 1 issue
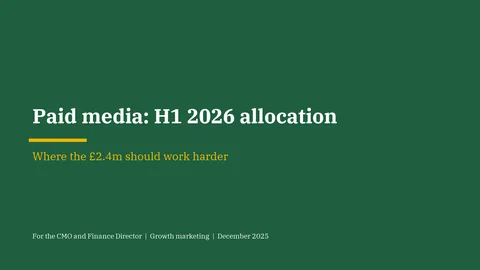 Claude Haiku 5.5
✓ Presentable
 DeepSeek V4.1 Flash 1017
✗ 3 issues
 Qwen3.8 Max (0902)
✓ Presentable
 minimax-m3.1-flash:free
✗ 2 issues
 Gemini 4 Argon
✗ 1 issue
 Muse Spark 1.3
✗ 1 issue
 Gemini 3.8 Flash
✗ 5 issues
 Mercury 3
✗ 1 issue
 Gemini 3.1 Pro Preview
✓ Presentable
 Claude Haiku 4.5
✗ 2 issues
 Gemini 3.5 Flash Lite
✗ 4 issues
 Mistral Medium 3.5
✗ 1 issue
 Mistral Large 4
✗ 2 issues
 DeepSeek V4 Pro 0423
✗ 4 issues
No usable deck
GLM 5.3
✗ No deck
 GPT-6 Astra
✗ 1 issue
 GPT-6 Sol
✓ Presentable
 GPT-6.1 Sol
✗ 1 issue
 Claude Opus 5.5
✓ Presentable
 Claude Sonnet 5.5
✓ Presentable
 Claude Fable 5.1
✗ 2 issues
 GPT-6 Luna
✗ 1 issue
 Grok 4.7
✗ 1 issue
 Muse Wonder
✓ Presentable
 Kimi K3
✗ 1 issue
 Claude Haiku 5.5
✗ 1 issue
 DeepSeek V4.1 Flash 1017
✗ 2 issues
 Qwen3.8 Max (0902)
✗ 1 issue
 minimax-m3.1-flash:free
✗ 2 issues
 Gemini 4 Argon
✗ 2 issues
 Muse Spark 1.3
✗ 4 issues
 Gemini 3.8 Flash
✗ 1 issue
 Mercury 3
✗ 2 issues
 Gemini 3.1 Pro Preview
✗ 3 issues
 Claude Haiku 4.5
✗ 3 issues
 Gemini 3.5 Flash Lite
✗ 2 issues
 Mistral Medium 3.5
✗ 4 issues
 Mistral Large 4
✗ 5 issues
 DeepSeek V4 Pro 0423
✗ 4 issues
No usable deck
GLM 5.3
✗ No deck
 GPT-6 Astra
✓ Presentable
 GPT-6 Sol
✓ Presentable
 GPT-6.1 Sol
✓ Presentable
 Claude Opus 5.5
✗ 2 issues
 Claude Sonnet 5.5
✗ 1 issue
 Claude Fable 5.1
✗ 1 issue
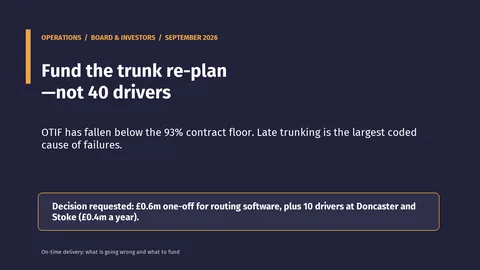 GPT-6 Luna
✗ 1 issue
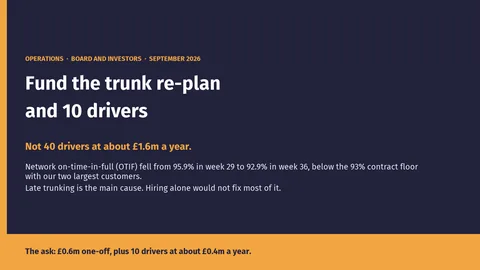 Grok 4.7
✗ 1 issue
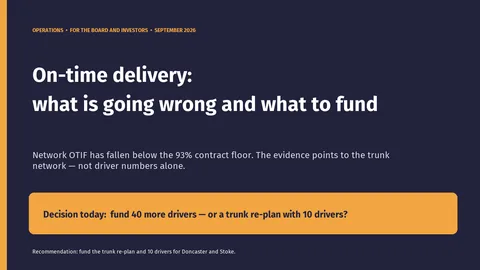 Muse Wonder
✗ 2 issues
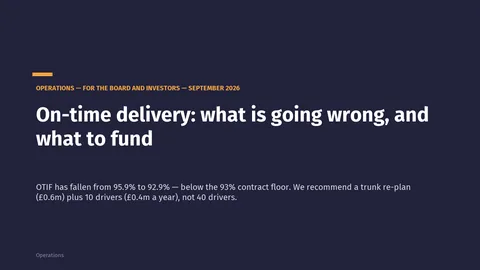 Kimi K3
✗ 1 issue
 Claude Haiku 5.5
✓ Presentable
 DeepSeek V4.1 Flash 1017
✗ 2 issues
 Qwen3.8 Max (0902)
✓ Presentable
No usable deck
minimax-m3.1-flash:free
✗ No deck
 Gemini 4 Argon
✗ 3 issues
 Muse Spark 1.3
✗ 3 issues
 Gemini 3.8 Flash
✗ 4 issues
 Mercury 3
✗ 2 issues
 Gemini 3.1 Pro Preview
✗ 3 issues
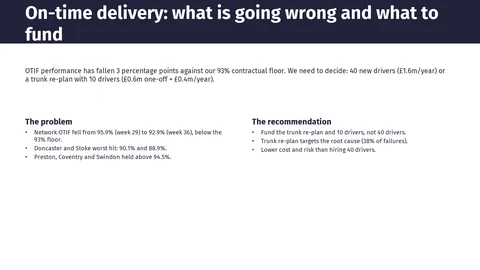 Claude Haiku 4.5
✗ 2 issues
 Gemini 3.5 Flash Lite
✗ 1 issue
 Mistral Medium 3.5
✗ 3 issues
 Mistral Large 4
✗ 4 issues
 DeepSeek V4 Pro 0423
✗ 4 issues
No usable deck
GLM 5.3
✗ No deck
 GPT-6 Astra
✗ 1 issue
 GPT-6 Sol
✗ 1 issue
 GPT-6.1 Sol
✓ Presentable
 Claude Opus 5.5
✗ 2 issues
 Claude Sonnet 5.5
✗ 2 issues
 Claude Fable 5.1
✓ Presentable
 GPT-6 Luna
✗ 1 issue
 Grok 4.7
✗ 2 issues
 Muse Wonder
✗ 1 issue
 Kimi K3
✗ 1 issue
 Claude Haiku 5.5
✗ 1 issue
 DeepSeek V4.1 Flash 1017
✗ 5 issues
 Qwen3.8 Max (0902)
✗ 3 issues
No usable deck
minimax-m3.1-flash:free
✗ No deck
 Gemini 4 Argon
✗ 1 issue
 Muse Spark 1.3
✗ 4 issues
 Gemini 3.8 Flash
✗ 2 issues
 Mercury 3
✗ 1 issue
 Gemini 3.1 Pro Preview
✗ 3 issues
 Claude Haiku 4.5
✗ 4 issues
 Gemini 3.5 Flash Lite
✗ 3 issues
 Mistral Medium 3.5
✗ 3 issues
 Mistral Large 4
✗ 3 issues
 DeepSeek V4 Pro 0423
✗ 3 issues
No usable deck
GLM 5.3
✗ No deck
Share of tasks where the deck said only what the analysis supports, against the share that could also be presented as it is. The gap is layout and design.
Share of tasks failing each check. A deck can fail several at once; any one means it needs fixing before it is shown.
| Model | Layout defects | Slides needing work | Draft figure quoted | Unsupported numbers | Unsupported claims | Caveat dropped | Misleading metric | Findings missing | Recommendation |
|---|---|---|---|---|---|---|---|---|---|
| GPT-6 AstraOpenAI | 0.0% | 33.3% | 0.0% | 0.0% | 0.0% | 0.0% | 0.0% | 0.0% | 0.0% |
| GPT-6 SolOpenAI | 33.3% | 0.0% | 0.0% | 0.0% | 0.0% | 0.0% | 0.0% | 16.7% | 0.0% |
| GPT-6.1 SolOpenAI | 16.7% | 50.0% | 0.0% | 0.0% | 0.0% | 0.0% | 0.0% | 0.0% | 0.0% |
| Claude Opus 5.5Anthropic | 16.7% | 66.7% | 0.0% | 0.0% | 0.0% | 16.7% | 0.0% | 0.0% | 0.0% |
| Claude Sonnet 5.5Anthropic | 0.0% | 33.3% | 0.0% | 0.0% | 0.0% | 16.7% | 0.0% | 0.0% | 16.7% |
| Claude Fable 5.1Anthropic | 66.7% | 50.0% | 33.3% | 0.0% | 0.0% | 0.0% | 0.0% | 0.0% | 0.0% |
| GPT-6 LunaOpenAI | 33.3% | 16.7% | 33.3% | 0.0% | 0.0% | 0.0% | 0.0% | 0.0% | 16.7% |
| Grok 4.7xAI | 16.7% | 16.7% | 16.7% | 0.0% | 0.0% | 16.7% | 0.0% | 0.0% | 16.7% |
| Muse WonderMeta | 83.3% | 66.7% | 0.0% | 0.0% | 0.0% | 0.0% | 0.0% | 0.0% | 0.0% |
| Kimi K3Moonshot AI | 66.7% | 16.7% | 0.0% | 0.0% | 33.3% | 0.0% | 0.0% | 16.7% | 33.3% |
| Claude Haiku 5.5Anthropic | 33.3% | 16.7% | 33.3% | 16.7% | 33.3% | 16.7% | 16.7% | 16.7% | 33.3% |
| DeepSeek-V4.1-Flash-1017DeepSeek | 83.3% | 66.7% | 50.0% | 0.0% | 16.7% | 16.7% | 0.0% | 0.0% | 16.7% |
| Qwen3.8-Max (0902)Alibaba | 33.3% | 50.0% | 33.3% | 0.0% | 16.7% | 16.7% | 0.0% | 0.0% | 0.0% |
| MiniMax M3.1 FlashMiniMax | 100.0% | 83.3% | 33.3% | 50.0% | 50.0% | 33.3% | 33.3% | 50.0% | 33.3% |
| Gemini 4 ArgonGoogle | 66.7% | 66.7% | 50.0% | 0.0% | 16.7% | 0.0% | 0.0% | 0.0% | 0.0% |
| Muse Spark 1.3Meta | 100.0% | 50.0% | 16.7% | 0.0% | 16.7% | 16.7% | 0.0% | 0.0% | 66.7% |
| Gemini 3.8 FlashGoogle | 83.3% | 33.3% | 50.0% | 16.7% | 50.0% | 0.0% | 0.0% | 0.0% | 33.3% |
| Mercury 3Inception | 33.3% | 33.3% | 33.3% | 16.7% | 16.7% | 16.7% | 16.7% | 16.7% | 83.3% |
| Gemini 3.1 Pro PreviewGoogle | 50.0% | 83.3% | 0.0% | 0.0% | 0.0% | 16.7% | 0.0% | 0.0% | 50.0% |
| Claude Haiku 4.5Anthropic | 50.0% | 66.7% | 50.0% | 0.0% | 33.3% | 0.0% | 0.0% | 16.7% | 50.0% |
| Gemini 3.5 Flash-LiteGoogle | 66.7% | 16.7% | 50.0% | 0.0% | 16.7% | 16.7% | 0.0% | 33.3% | 83.3% |
| Mistral Medium 3.5Mistral AI | 33.3% | 50.0% | 50.0% | 0.0% | 33.3% | 0.0% | 0.0% | 0.0% | 50.0% |
| Mistral Large 4Mistral AI | 66.7% | 100.0% | 16.7% | 33.3% | 50.0% | 16.7% | 0.0% | 0.0% | 83.3% |
| DeepSeek-V4-Pro (0423)DeepSeek | 66.7% | 83.3% | 33.3% | 0.0% | 66.7% | 16.7% | 0.0% | 16.7% | 66.7% |
Whether each deck could be presented as it is, and if not, how many kinds of issue it had. Each square opens the deck.
| Model | Hearthside Coffee | Lumio | Pantry Lane | Northgate Homes | Kestrel Logistics | Wrenfield Borough Council | Presentable |
|---|---|---|---|---|---|---|---|
| GPT-6 Astra | ✓ | ✓ | ✓ | 1 | ✓ | 1 | 4 of 6 |
| GPT-6 Sol | 1 | ✓ | 1 | ✓ | ✓ | 1 | 3 of 6 |
| GPT-6.1 Sol | ✓ | 2 | 1 | 1 | ✓ | ✓ | 3 of 6 |
| Claude Sonnet 5.5 | ✓ | 1 | ✓ | ✓ | 1 | 2 | 3 of 6 |
| Claude Opus 5.5 | ✓ | 1 | 1 | ✓ | 2 | 2 | 2 of 6 |
| Claude Fable 5.1 | 3 | ✓ | 3 | 2 | 1 | ✓ | 2 of 6 |
| Grok 4.7 | ✓ | 1 | ✓ | 1 | 1 | 2 | 2 of 6 |
| Claude Haiku 5.5 | 2 | – | ✓ | 1 | ✓ | 1 | 2 of 6 |
| Qwen3.8 Max (0902) | 2 | 3 | ✓ | 1 | ✓ | 3 | 2 of 6 |
| Muse Wonder | 2 | 2 | 2 | ✓ | 2 | 1 | 1 of 6 |
| Gemini 3.1 Pro Preview | 2 | 1 | ✓ | 3 | 3 | 3 | 1 of 6 |
| GPT-6 Luna | 1 | 1 | 1 | 1 | 1 | 1 | 0 of 6 |
| Kimi K3 | 5 | 1 | 1 | 1 | 1 | 1 | 0 of 6 |
| DeepSeek V4.1 Flash 1017 | 1 | 2 | 3 | 2 | 2 | 5 | 0 of 6 |
| minimax-m3.1-flash:free | 5 | 1 | 2 | 2 | – | – | 0 of 6 |
| Gemini 4 Argon | 2 | 3 | 1 | 2 | 3 | 1 | 0 of 6 |
| Muse Spark 1.3 | 2 | 2 | 1 | 4 | 3 | 4 | 0 of 6 |
| Gemini 3.8 Flash | 2 | 2 | 5 | 1 | 4 | 2 | 0 of 6 |
| Mercury 3 | – | 1 | 1 | 2 | 2 | 1 | 0 of 6 |
| Claude Haiku 4.5 | 2 | 3 | 2 | 3 | 2 | 4 | 0 of 6 |
| Gemini 3.5 Flash Lite | 4 | 3 | 4 | 2 | 1 | 3 | 0 of 6 |
| Mistral Medium 3.5 | 1 | 1 | 1 | 4 | 3 | 3 | 0 of 6 |
| Mistral Large 4 | 3 | 5 | 2 | 5 | 4 | 3 | 0 of 6 |
| DeepSeek V4 Pro 0423 | 2 | 4 | 4 | 4 | 4 | 3 | 0 of 6 |
| GLM 5.3 | – | – | – | – | – | – | 0 of 6 |
✓ presentable as it is · a number: the kinds of issue that stopped it · – no usable deck.
An invented company's memo with findings, a recommendation and caveats, two to four data tables, the audience, the decision and a brand kit.
The model returns every slide as positioned text, shapes, native charts and tables. We render it to PowerPoint and to images.
Code checks the layout and traces every number to the analysis; three judges check the story and rate each slide's design.
On each task the judges compare decks in pairs and pick the one they would rather present. The votes become the rating.
Turning an analysis into slides is one of the most common things people ask AI to do at work, and the risk is not ugly slides: it is a number that is not in the analysis, a caveat that falls off, or a draft figure that ends up in front of the board.
Each task is an invented company's analysis written for the benchmark, with planted traps: a caveat that must travel with its number, a figure the memo says not to quote, a metric it warns is misleading, and a finding that contradicts a senior stakeholder's view.
Presentable is a bar: once the best models clear it on every task, it stops telling them apart. The head-to-head rating does not run out of room, because a deck only has to be preferred to another one. Each deck meets about six others per task; a 400-point gap means the higher-rated model's deck is preferred about ten times out of eleven.
A single judge was the strictest of three on unsupported claims (it flagged 24 material claims in a pilot where the other two flagged 12 and 1), and its own model led the pilot. So every judged check is decided by a majority of three judges: GPT-6.1 Sol, Claude Opus 5.5 and Gemini 3.1 Pro. In the pilot they agreed with each other on 97 to 100% of the checks on findings, numbers, recommendations and misleading metrics, and on 89 to 90% of decisions about whether a slide needs work. In head-to-head comparisons a judge never votes on a pair that includes its own vendor's deck. A sample of human ratings is still to come.
A model that made no usable deck on any task has no rating, so it is listed here instead of ranked. They are listed here so you can see why.